



How to Fix Illegible Text and Symbols in Converted Documents

Question details
The user is seeking a way to fix unreadable text and random symbols that appear after converting a document to another format.
- Product
- Document Conversion
- Device & OS
- not provided
- Scenario
- The user converts a file such as a scanned image or a PDF into a text-based format, but the resulting document displays garbled characters instead of the intended text.
- Observed behavior
- The converted document displays unreadable text, numbers, or symbols due to unsupported fonts, incorrect character encoding, poor scan quality, or inaccurate OCR.
Ensure you still have the original source file (such as the original PDF, scan, or image) and verify that its text is legible before attempting to reconvert it.
Adjust OCR Settings and Reconvert
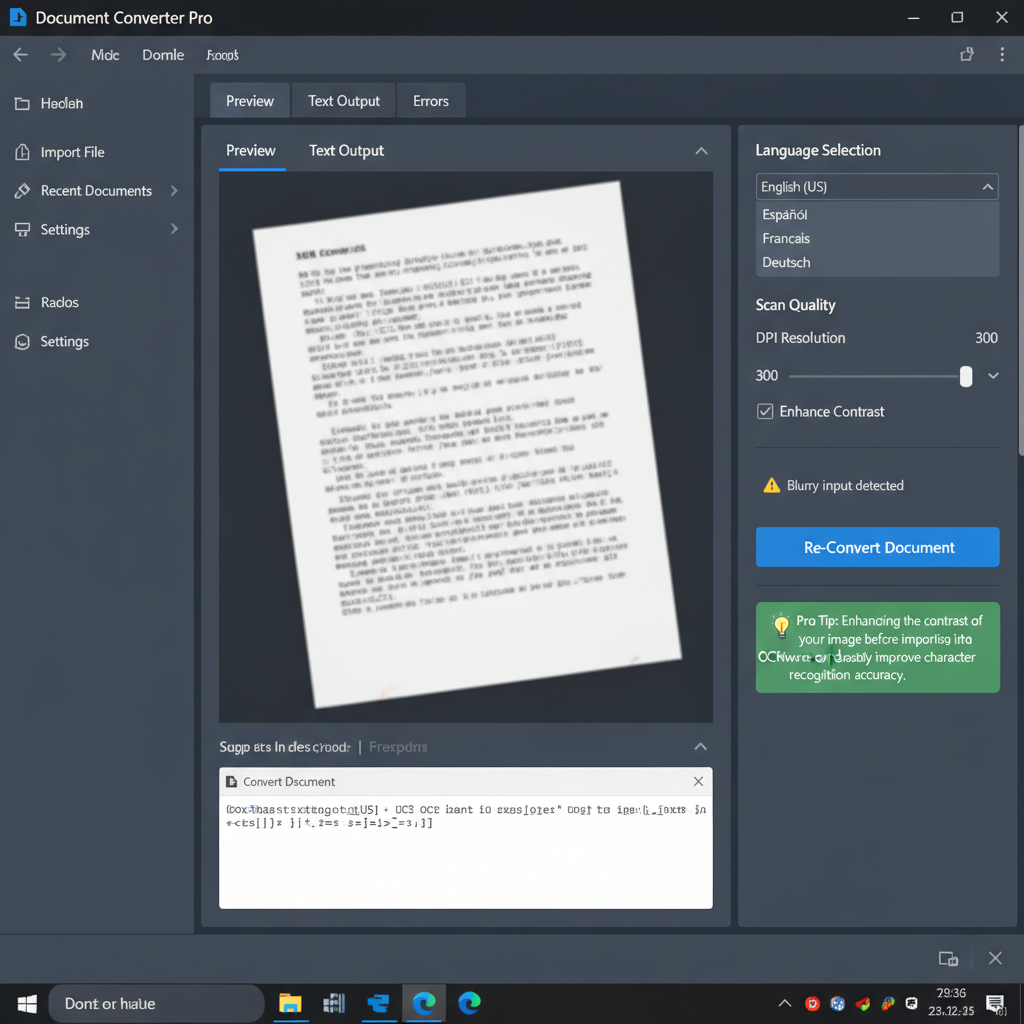
Improving the source scan quality and selecting the correct OCR language can resolve most character recognition errors.
When converting scanned documents or images, Optical Character Recognition (OCR) attempts to identify letters based on their shapes. If the image is blurry or the wrong language is set, the software will output random symbols.
Open your original source image or PDF. Ensure it is scanned at a high resolution (at least 300 DPI) and that the text is sharp and not skewed.
In your document conversion tool, navigate to the OCR or extraction settings and verify that the selected language perfectly matches the primary language of your document.
Click the convert or extract button to process the file again using the optimized settings and high-resolution source.
Fix Font and Encoding Issues
If a document contains unsupported fonts or incorrect character encoding, standard text will display as gibberish.
Convert and Edit Documents Accurately with WPS Office
WPS Office offers highly accurate OCR and robust PDF-to-Word conversion tools, ensuring that your text, fonts, and layouts remain intact without turning into unreadable symbols.
- 1. Open your source file: Launch WPS Office and open your original PDF or image file directly in the software.
- 2. Access the conversion tools: Navigate to the 'Tools' tab and select 'PDF to Word' or click 'OCR' depending on your source file type.
- 3. Set language and extract: Choose the correct document language in the OCR prompt and click 'Extract' or 'Convert' to process your document into clean, editable text.
Frequently Asked Questions
Why does my converted PDF to Word document have weird symbols?
This usually happens when the original PDF uses custom or embedded fonts that are not installed on your computer, or when the conversion software fails to recognize the correct character encoding, replacing unknown letters with random symbols.
How can I improve OCR accuracy to avoid illegible text?
Ensure your source image or scanned document is well-lit, has high contrast, and is saved at a minimum resolution of 300 DPI. Additionally, always confirm the correct language is selected in your OCR tool before converting.
What is character encoding and how does it affect converted files?
Character encoding tells the computer how to interpret text data. If a file is saved in one encoding (like ANSI) but opened or converted using another (like UTF-8), standard text and special characters will turn into unreadable symbols.
Can I manually fix the gibberish text in my converted Word document?
Yes. If the issue is limited to a few specific characters, you can use the 'Find and Replace' feature to manually swap the incorrect symbols with the right letters. However, reconverting the document with better settings is usually faster for heavily corrupted files.


