



How to Prevent Duplicate Counts in PivotTables with Multiple Rows

Question details
The user needs to prevent PivotTables from overstating totals when unpivoted data results in multiple rows for a single response or individual.
- Product
- Spreadsheet
- Device & OS
- not provided
- Scenario
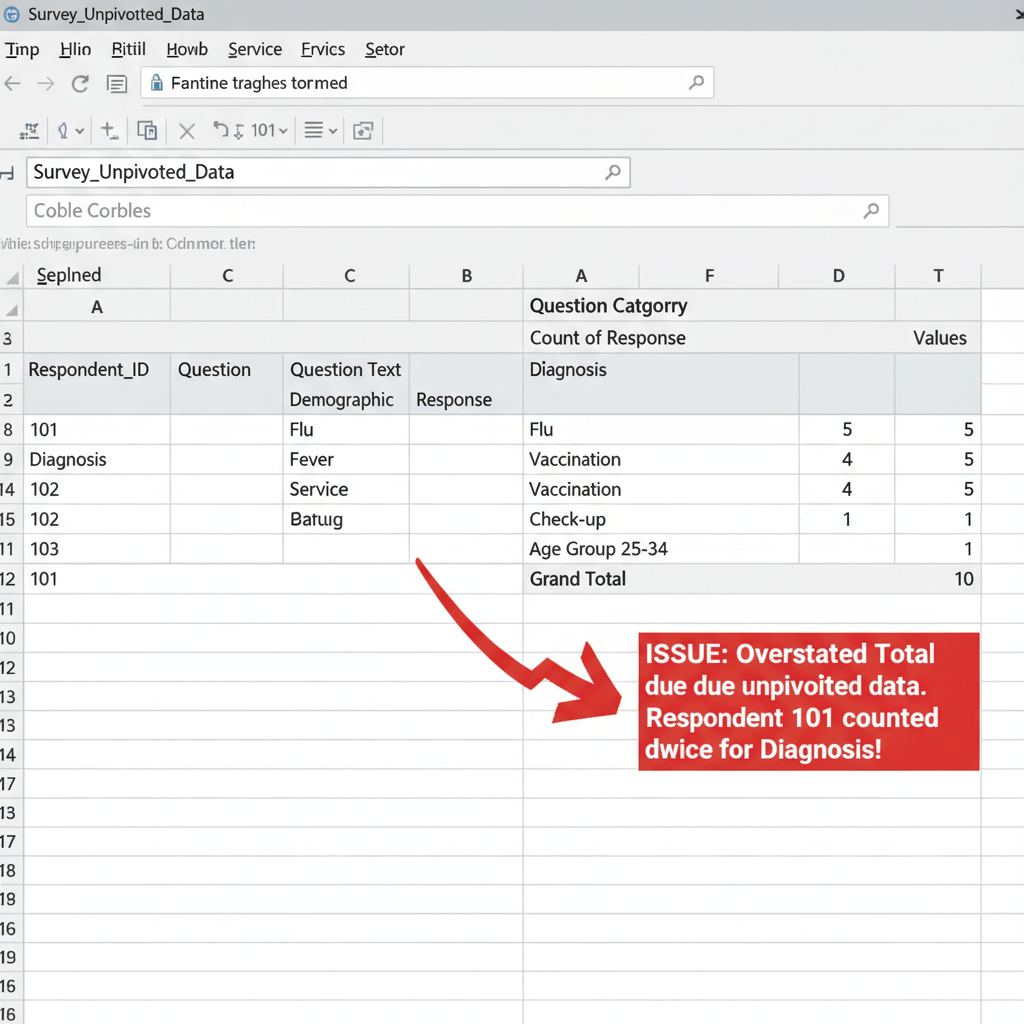
- Analyzing survey or form data that has been unpivoted, causing single submissions to span multiple rows.
- Observed behavior
- Standard PivotTable row counts calculate every row, leading to duplicated counts for diagnoses, services, and categories.
Ensure your dataset contains a unique identifier column, such as a Submission ID or Visit ID, before applying any PivotTable transformations.
Use Distinct Count in the Data Model
Adding your data to the Data Model unlocks the Distinct Count feature, which only counts unique identifiers.
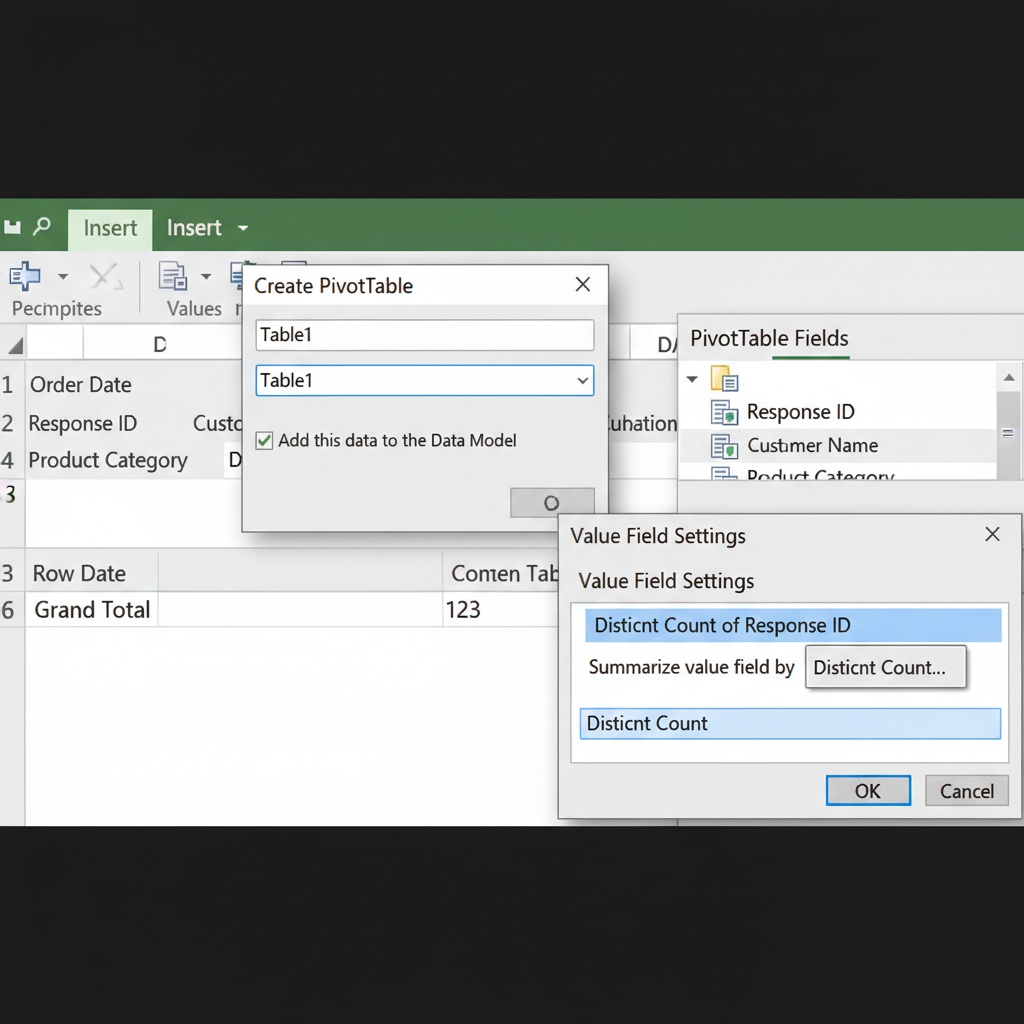
Select your dataset, go to the 'Insert' tab, and click 'PivotTable'. In the creation dialog, check the box for 'Add this data to the Data Model'.
Drag your unique identifier column (e.g., Response ID) into the 'Values' area of the PivotTable Fields pane.
Click on the field in the 'Values' area and select 'Value Field Settings'. Scroll to the bottom of the calculation options and select 'Distinct Count', then click 'OK'.
Create a Helper Column for Unique Values
Use a formula to identify the first instance of a duplicate record if the Data Model is unavailable.
Easily Summarize Unpivoted Data in WPS Spreadsheet
WPS Spreadsheet offers comprehensive PivotTable tools that allow you to accurately process unpivoted datasets, filter out duplicate counts, and extract meaningful insights effortlessly.
- 1. Prepare the Dataset: Open your data in WPS Spreadsheet and ensure a unique ID column is present.
- 2. Create a PivotTable: Navigate to the Insert tab and select PivotTable to organize your unpivoted data.
- 3. Adjust Field Settings: Drag the unique ID into the Values area and customize the field settings to count unique items accurately.
Frequently Asked Questions
Why is my PivotTable counting the same entry multiple times?
By default, PivotTables count every row in your dataset. If your data was unpivoted and a single entry now spans multiple rows, a standard count will include all of those duplicate rows.
What is 'Distinct Count' and how do I access it?
Distinct Count is a function that calculates the number of unique items rather than total rows. You can access it by ensuring 'Add this data to the Data Model' is checked when creating your PivotTable, then selecting 'Distinct Count' in the Value Field Settings.
How do I create a unique identifier if my raw data lacks one?
Before you unpivot your data, insert a new column and either create a sequential number list (1, 2, 3) or combine existing unique columns (like Name and Timestamp) using the CONCATENATE function to serve as a unique key.


