



Fix Exported Word File Contains Images Instead of Editable Text
Question details
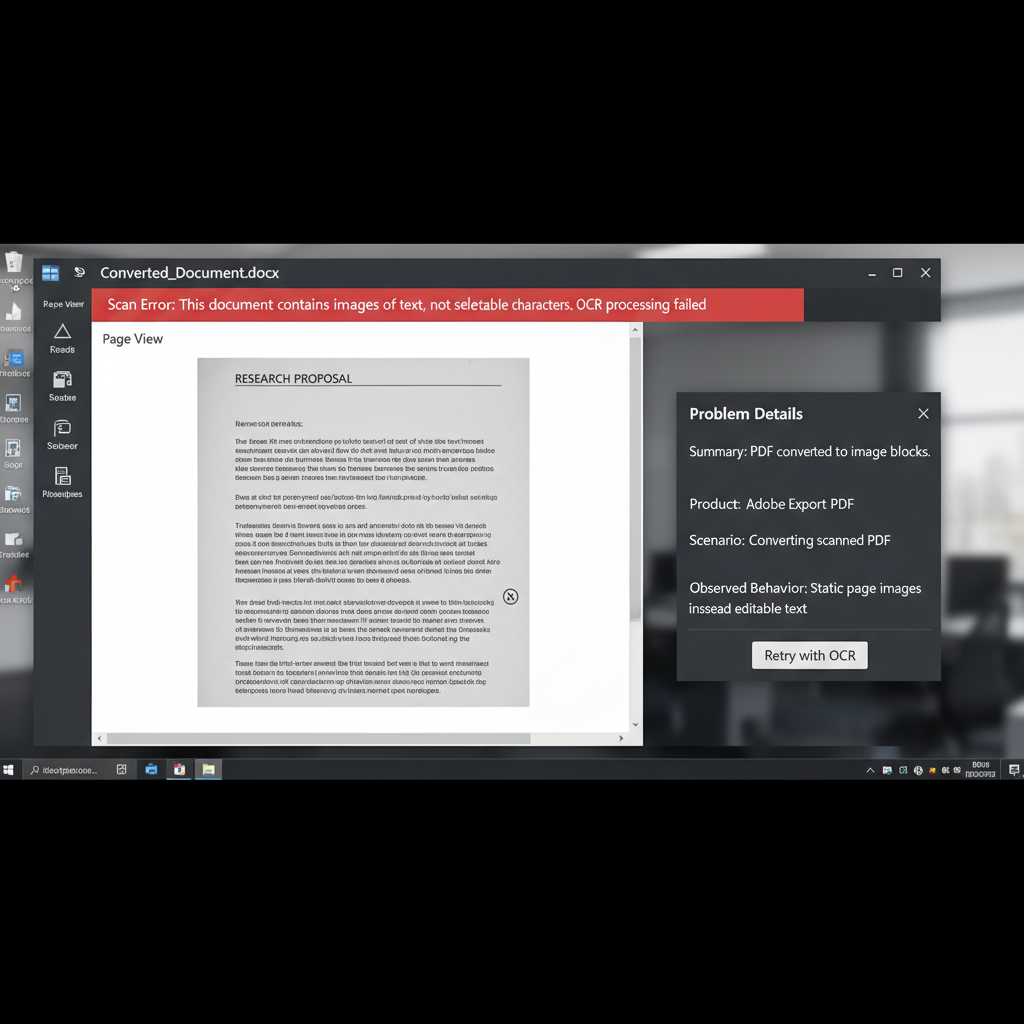
The user is attempting to convert a PDF into a Word document, but the resulting file outputs image blocks instead of editable text.
- Product
- PDF Converters / Adobe Export PDF
- Device & OS
- not provided
- Scenario
- Converting a scanned, image-based, or damaged PDF file into an editable Microsoft Word document for text modification.
- Observed behavior
- The exported Word document contains static page images rather than selectable and editable text characters, usually due to a lack of OCR processing.
Before proceeding, check if your original PDF is image-based by attempting to highlight individual words with your cursor; if you can only select large rectangular blocks or the whole page, the file is a scanned image.
Enable Optical Character Recognition (OCR) During Conversion
To extract editable text from an image-based PDF, you must use a conversion tool equipped with OCR and ensure the feature is actively enabled.
Standard PDF to Word conversion simply maps existing text data from the PDF format to the Word format. If the source file is a scanned document, there is no text data to map—only a picture of text.
Optical Character Recognition (OCR) technology scans these pictures, identifies the letters, and translates them into machine-encoded text. You must use an OCR-capable PDF editor or converter to resolve this issue.
Open your PDF in an application that supports OCR, such as Adobe Acrobat Pro, WPS Office, or a dedicated online OCR PDF converter.
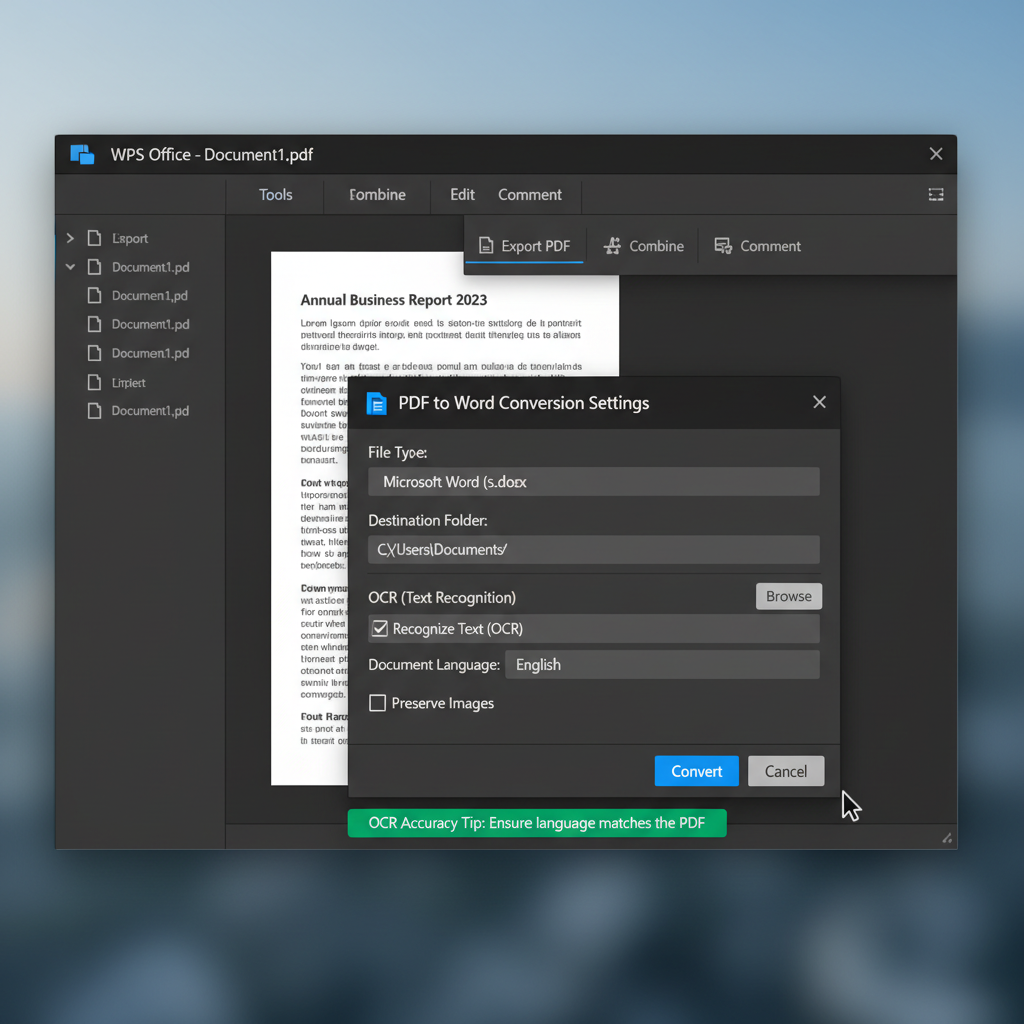
Navigate to the 'Export PDF' or 'PDF to Word' tool within your application.
Look for a settings gear or options menu before finalizing the export. Check the box to 'Recognize Text', 'Enable OCR', or select your specific document language.
Click 'Convert' or 'Export'. The software will process the images and generate a new Word document containing fully editable text.
Verify File Integrity and Improve Scan Quality
Test the conversion tool with a different document to isolate the issue, and ensure your scanned PDF meets the resolution requirements for text extraction.
Convert Scanned PDFs to Editable Word Documents with WPS Office
WPS Office features a powerful, built-in PDF to Word converter equipped with highly accurate OCR technology. It effortlessly recognizes text in scanned or image-based PDFs, ensuring your exported files are fully editable while perfectly preserving the original layout.
- 1. Open your PDF: Launch WPS Office and open the scanned or image-based PDF document.
- 2. Access the PDF to Word tool: Navigate to the 'Tools' tab on the top ribbon and select 'PDF to Word'.
- 3. Enable OCR settings: In the conversion dialog, ensure the OCR option is toggled on and select the correct document language.
- 4. Convert the file: Choose your desired save path and output format (.docx), then click 'Convert'.
- 5. Edit your text: The converted Word document will automatically open in WPS Office, ready for full text editing.
Frequently Asked Questions
Why does my converted Word document look like a single picture?
This happens when the original PDF is an image or a scanned document rather than a digitally created file. Because there is no underlying text data, basic converters simply embed the page images into the Word document unless OCR technology is applied during the conversion.
What is OCR and why do I need it for PDF conversion?
OCR stands for Optical Character Recognition. It is an advanced technology that scans images of text and translates them into machine-readable characters. You need OCR to convert scanned PDFs into Word files so you can actually edit the text instead of just looking at an image.
How can I tell if my PDF requires OCR before converting?
Open your PDF in any reader and try to click and drag your cursor over a specific sentence to highlight it. If you can only select the entire page or a large block, the document is image-based and requires OCR to be properly converted into editable text.
Why did my PDF convert to editable text but it looks garbled or uses strange symbols?
Garbled text usually indicates that the original PDF contains damaged fonts, subset fonts, or the scanning resolution was too poor for the OCR engine to accurately identify the letters. To fix this, try using a higher quality scan (at least 300 DPI) or ensuring the OCR language matches the document text perfectly.


