



How to Batch OCR Multiple Scanned PDF Files for Searchable Documents
Question details
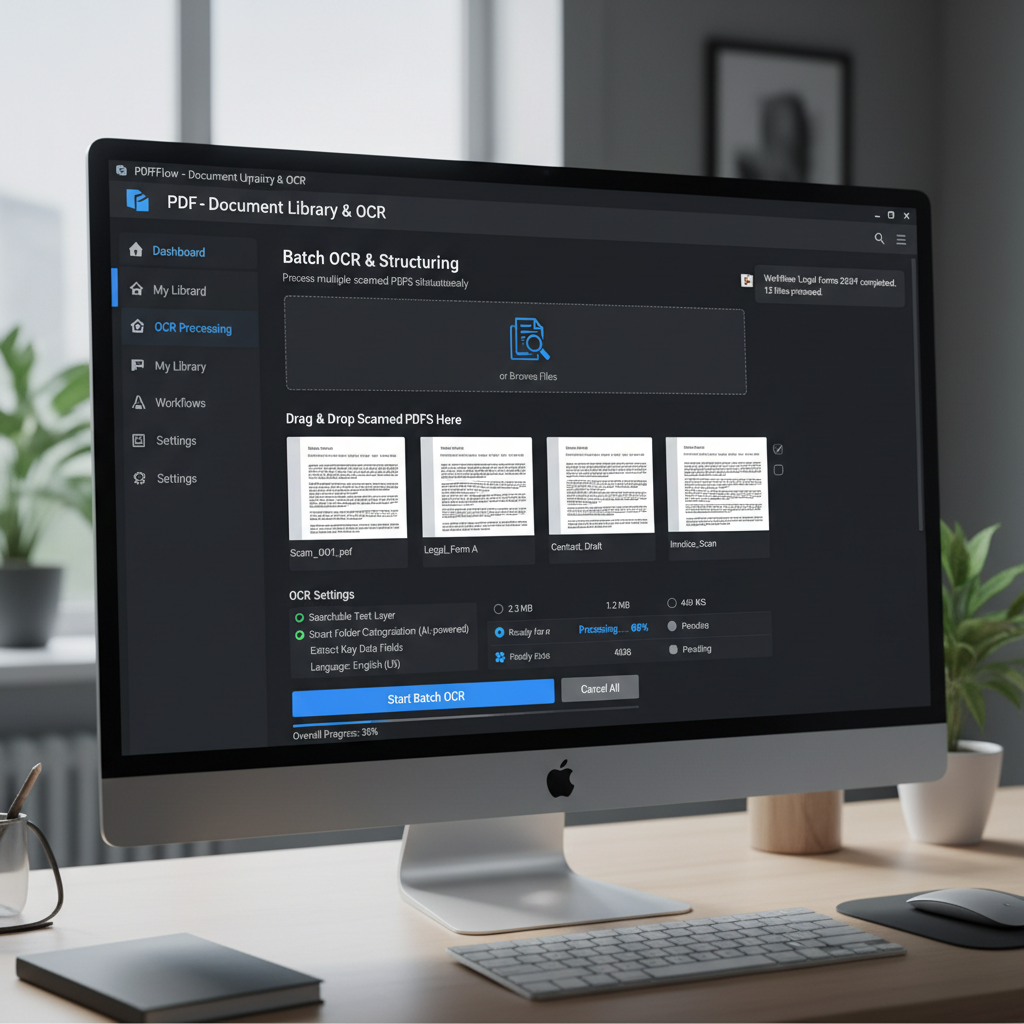
The user needs to apply optical character recognition (OCR) to multiple scanned PDF files simultaneously to make them searchable and easy to organize.
- Product
- Device & OS
- not provided
- Scenario
- Organizing scanned legal forms and paper documents into a structured, searchable folder library.
- Observed behavior
- The current PDF documents are image-based scans and lack searchable or editable text layers.
Gather all your scanned PDFs into a single, dedicated folder on your computer to streamline the batch process and avoid modifying original files accidentally.
Use Adobe Acrobat Action Wizard for Batch OCR
Utilize Adobe Acrobat Pro's built-in Action Wizard to automate text recognition across an entire folder of scanned PDFs.
Adobe Acrobat Pro includes an Action Wizard feature specifically designed to handle repetitive tasks on multiple documents. By setting up an OCR action, you can process an entire directory of legal documents or scanned forms without opening each file individually.
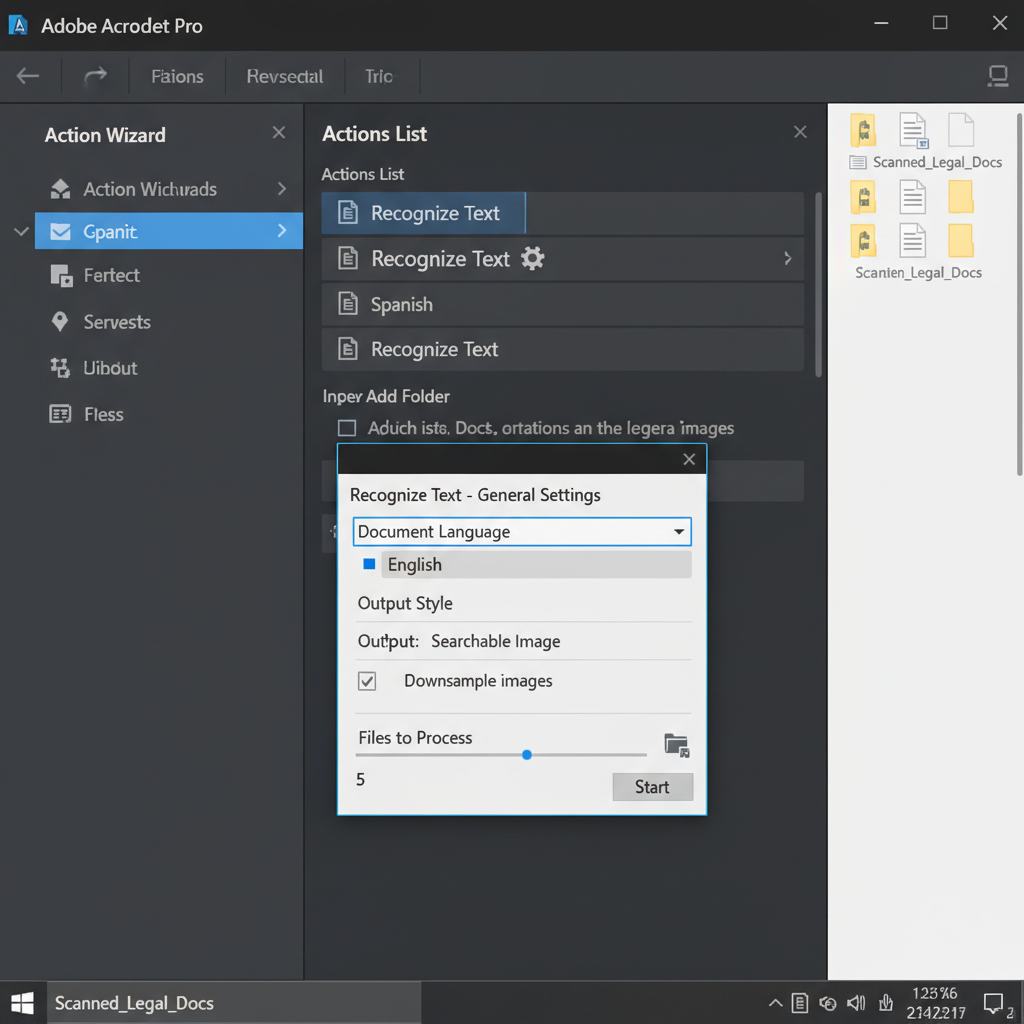
Launch Adobe Acrobat Pro, navigate to the 'Tools' menu at the top, and select the 'Action Wizard' tool from the list of options.
In the Actions List, click on 'Recognize Text'. If it is not visible, click 'New Action', select 'Recognize Text' from the Document Processing tools, and add it to your custom action list.
Click 'Add Folder' or 'Add Files' within the action prompt. Browse your computer and select the dedicated folder containing all the scanned PDFs you want to process.
Click the gear icon next to the 'Recognize Text' step to adjust your settings. Ensure the document language matches your files and set the Output Style to 'Searchable Image' to preserve the original appearance.
Click the 'Start' button to begin the batch process. Once Acrobat finishes processing, review the text accuracy and move the fully searchable files into your structured library.
Convert Scanned Documents to Searchable Text with WPS Office
WPS Office provides powerful PDF editing and OCR capabilities, allowing you to quickly extract text from scanned images or convert image-based PDFs into editable and searchable documents for easier management.
- 1. Open Your Scanned PDF: Launch WPS Office, switch to the PDF tab, and open the scanned document you wish to make searchable.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' or 'Picture to Text' icon.
- 3. Select Extraction Mode: Choose your preferred output. You can extract the text directly into a document or choose to convert the file into a searchable PDF format.
- 4. Start Recognition: Set the document language, click 'Start', and let WPS process the file. Save your new, searchable document to your desired folder.
Frequently Asked Questions
Does batch OCR change the visual layout of my scanned PDFs?
No. If you select the 'Searchable Image' or 'Searchable PDF' setting during the OCR process, the visual appearance of your scanned document remains exactly the same. The OCR tool simply adds an invisible layer of text over the image, allowing you to search and select words.
How do I know if my PDF is already searchable before running OCR?
Open the PDF and try selecting text using your mouse cursor. Alternatively, press 'Ctrl + F' (Windows) or 'Cmd + F' (Mac) and type a word you see on the page. If the text highlights and the search finds it, the document is already searchable and does not need OCR.
Why is the OCR output inaccurate or full of errors?
OCR accuracy depends highly on the quality of the original scan. Low resolution, blurry text, handwriting, complex page backgrounds, or skewed pages can cause recognition errors. Enhancing the scan contrast before running OCR can often improve results.
Can I batch OCR PDFs for free?
Most automated batch processing and advanced OCR tools are premium features in software like Adobe Acrobat Pro. While some open-source or free tier tools exist, they generally have strict limitations on page counts or folder sizes.


