



How to Export Vietnamese or Arabic Text from PDF to Word
Question details
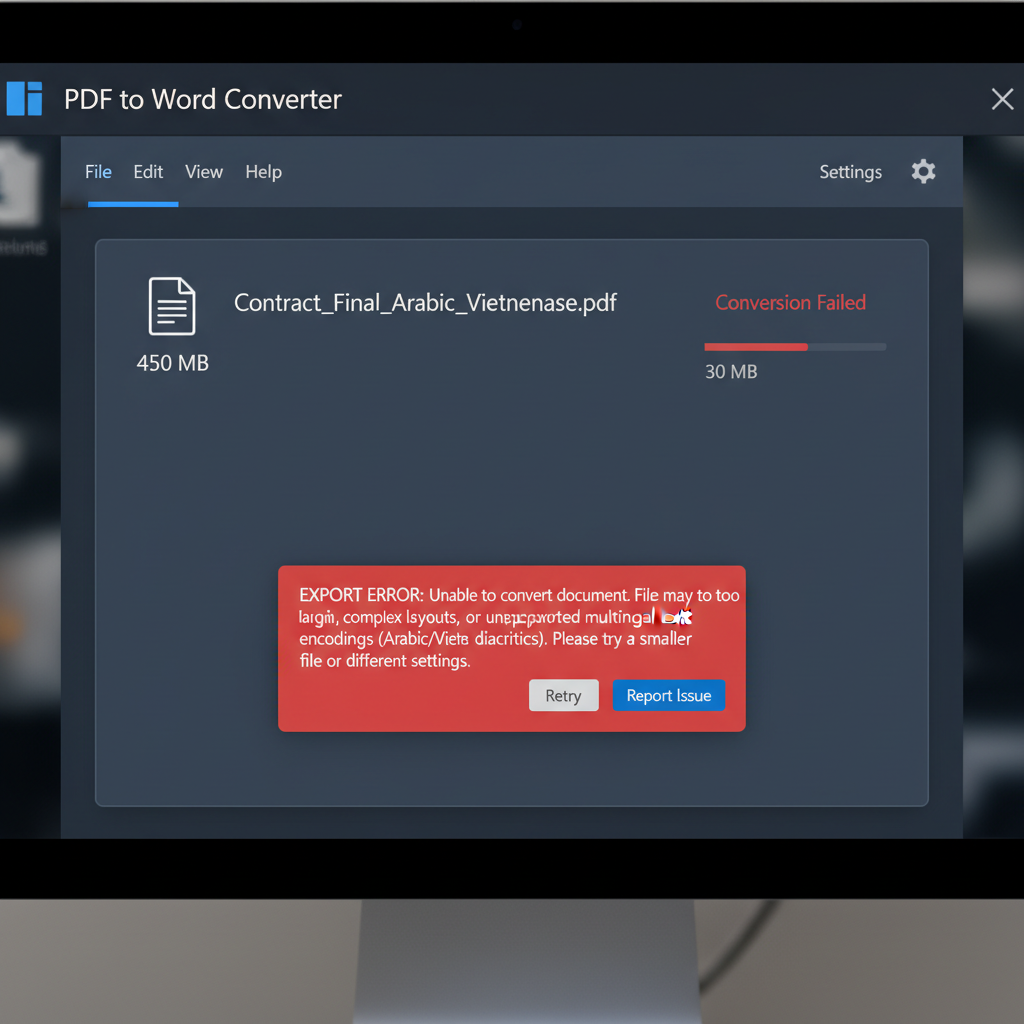
The user needs to export a large PDF document containing Vietnamese or Arabic text into a Microsoft Word file but is encountering conversion failures.
- Product
- PDF to Word Converter
- Device & OS
- not provided
- Scenario
- Converting complex, multilingual PDF documents with specific character encodings (such as Vietnamese and Arabic with diacritics) to an editable DOCX format.
- Observed behavior
- The PDF export to DOCX fails entirely, potentially due to large file sizes, complex layouts, embedded fonts, or unsupported character encodings for right-to-left or diacritic-heavy languages.
Before attempting the conversion again, open the PDF to verify if the text can be highlighted with your cursor. If the document is scanned or text is unselectable, you will need a converter equipped with Optical Character Recognition (OCR) designed for Arabic or Vietnamese.
Use a Cloud-Based PDF Exporter
Cloud-based PDF conversion tools typically possess more powerful processing capabilities to handle large files and complex, non-standard font encodings without crashing.
Desktop applications sometimes fail to parse complex language sets if the system lacks the proper language packs or memory to handle large documents. Using a robust online tool bypasses local hardware and software limitations.
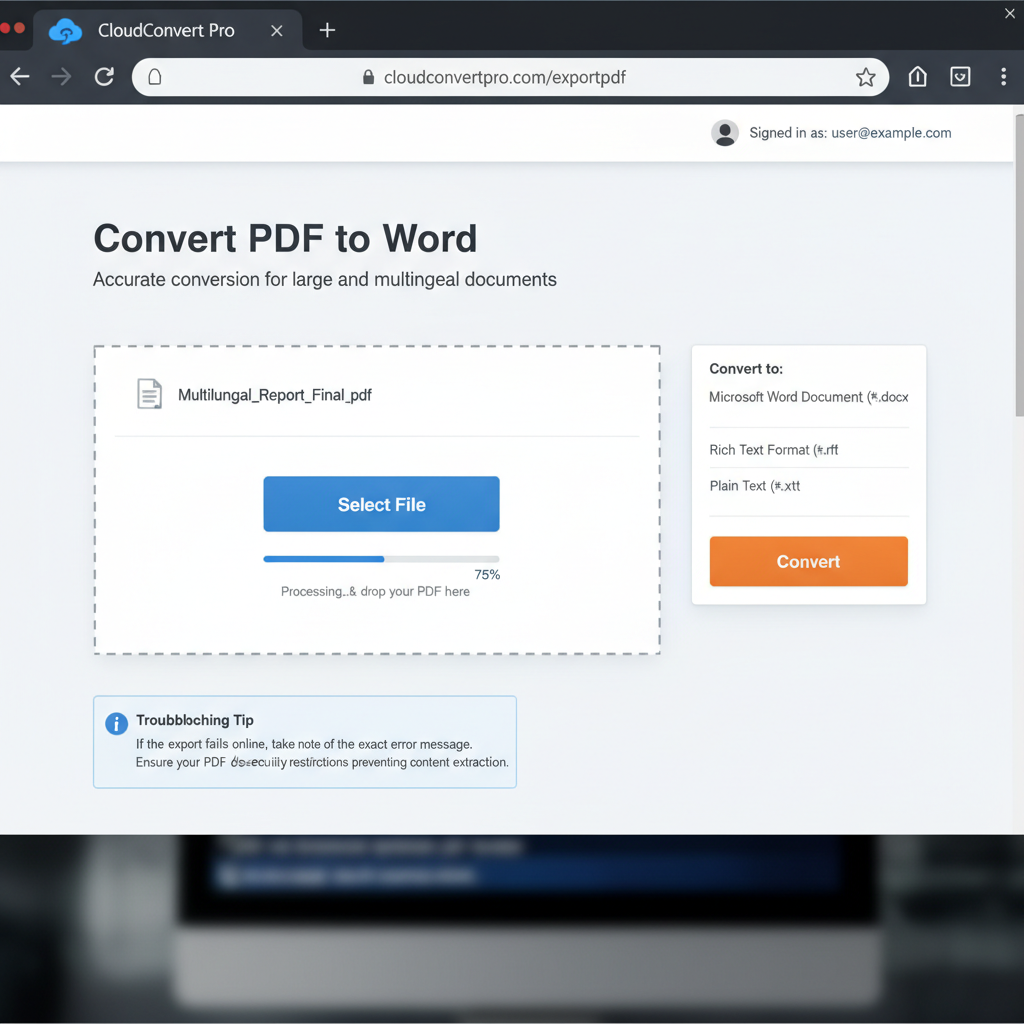
Open your web browser and navigate to a robust online PDF conversion tool, such as Adobe Acrobat Web (cloud.acrobat.com/exportpdf) or the WPS PDF to Word online tool.
Log in using your account credentials to ensure you have access to large-file handling and advanced export features.
Click the 'Select File' button or drag and drop your PDF containing the Vietnamese or Arabic text into the designated upload area.
Choose 'Microsoft Word Document (*.docx)' as your target export format from the dropdown menu, then click 'Export' or 'Convert'.
Download the processed file, open it in Microsoft Word, and check if the Arabic diacritics and Vietnamese special characters have been rendered correctly.
Pre-Process and Split Large PDF Files
Splitting a large PDF reduces the processing load on the conversion engine, preventing timeouts caused by dense formatting or embedded fonts.
Easily Convert Multilingual PDFs to Word with WPS Office
WPS Office features a powerful built-in PDF to Word converter equipped with advanced OCR capabilities. It is optimized to accurately recognize complex character encodings like Vietnamese and Arabic while maintaining your original document layout, even in large files.
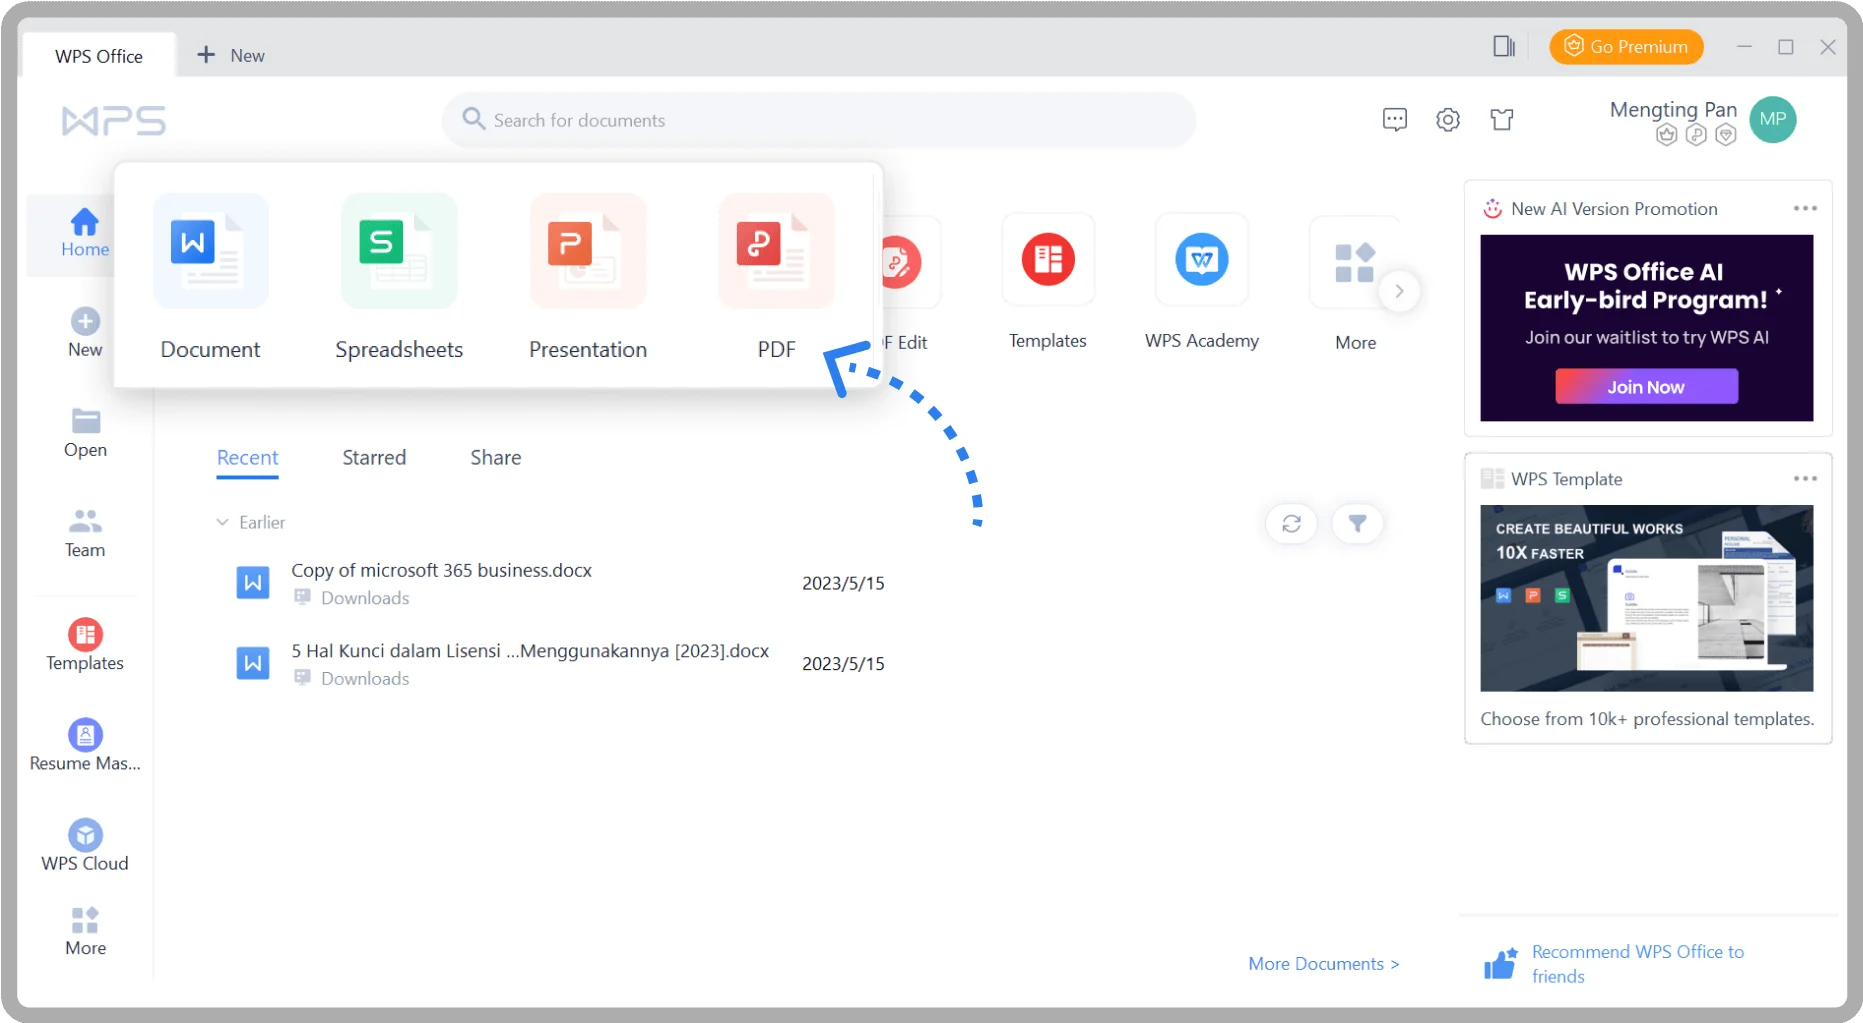
- 1. Open PDF Tools in WPS: Launch WPS Office on your computer and navigate to the 'PDF' tab on the main interface.
- 2. Access the PDF to Word Converter: Click on 'PDF to Word' located in the top toolbar to open the conversion utility.
- 3. Import your document: Drag and drop your Arabic or Vietnamese PDF into the window, or click 'Add Files' to select it from your storage.
- 4. Configure conversion settings: Ensure the output format is set to 'DOCX'. If the document is scanned, toggle on the OCR feature and select the matching language.
- 5. Execute the conversion: Click the 'Convert' button. Once finished, WPS will automatically open the fully editable document.
Frequently Asked Questions
Why do Arabic characters appear disconnected or reversed when exported to Word?
Arabic is a right-to-left (RTL) language that utilizes complex ligatures. Standard PDF converters may lack the required RTL text rendering engines, causing the characters to disconnect or display left-to-right. Using an advanced converter with dedicated RTL support or utilizing an OCR tool usually resolves this.
Does file size affect the PDF to Word conversion process?
Yes. Very large PDF files with high-resolution graphics, hundreds of pages, or intricate embedded fonts demand significant processing power. This can cause basic or free conversion tools to timeout or throw an error. Splitting the document or using a premium cloud converter can mitigate this.
What should I do if the Vietnamese text in the converted Word document looks like gibberish?
This typically occurs when the original PDF uses custom or improperly embedded fonts that the converter cannot map to standard Unicode characters. Try running the PDF through an OCR (Optical Character Recognition) converter, which reads the visual shape of the letters rather than relying on the underlying font encoding.


