



How to Fix Adobe Acrobat OCR Not Working on Scanned PDFs
Question details
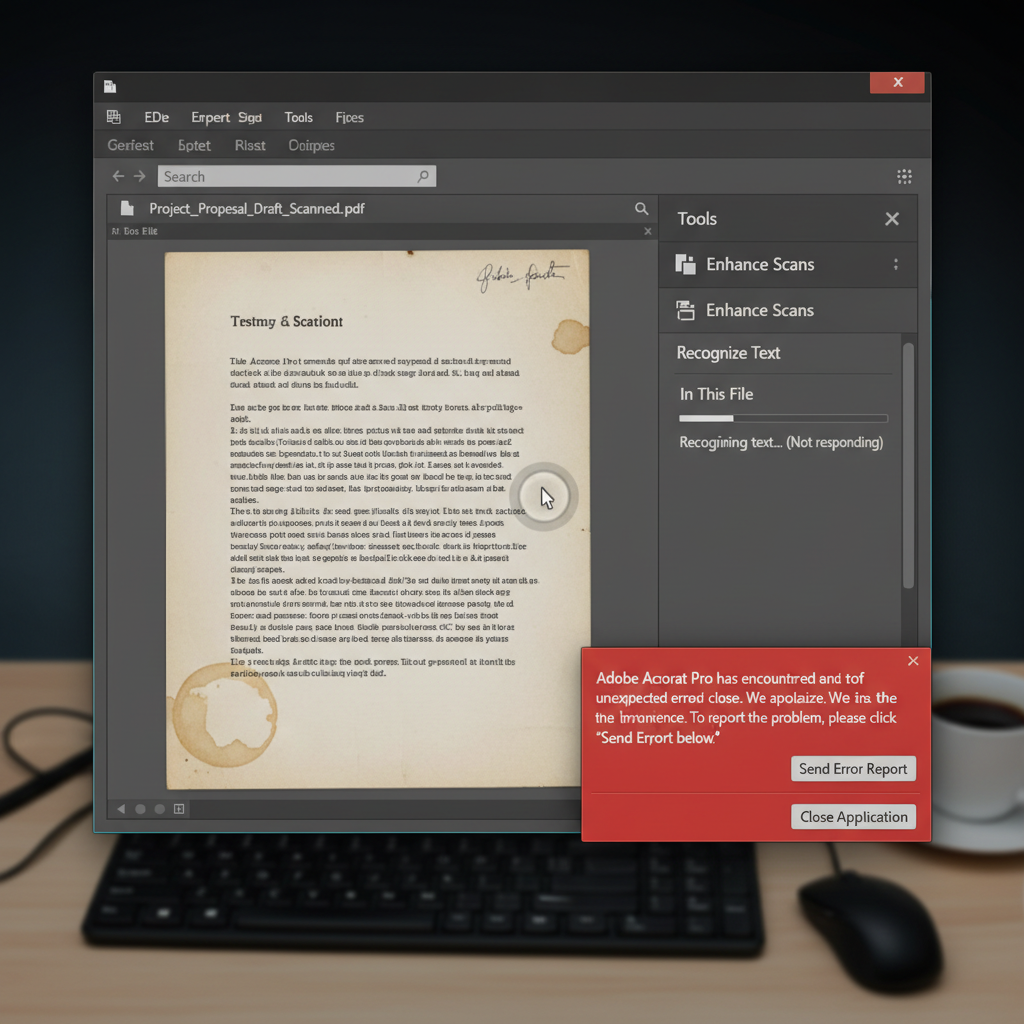
The user is unable to select or edit text in a scanned PDF because the Adobe Acrobat OCR process fails, crashes, or takes too long to process.
- Product
- Adobe Acrobat Pro
- Device & OS
- not provided
- Scenario
- Attempting to convert a scanned PDF document into an editable and searchable format using the built-in OCR text recognition tool.
- Observed behavior
- The OCR process either takes several minutes, crashes the application, or completes without actually generating a selectable text layer.
Ensure your computer has sufficient memory available and verify that the original scanned document is legible, well-lit, and not excessively skewed.
Update Adobe Acrobat and Rerun the OCR Tool
Updating to the latest version of Acrobat resolves many known bugs. Manually rerunning OCR with the correct language settings ensures accurate text recognition.
Software updates often contain essential bug fixes for OCR engine crashes. Additionally, setting the exact document language is strictly necessary because mismatched languages prevent the text layer from generating correctly.
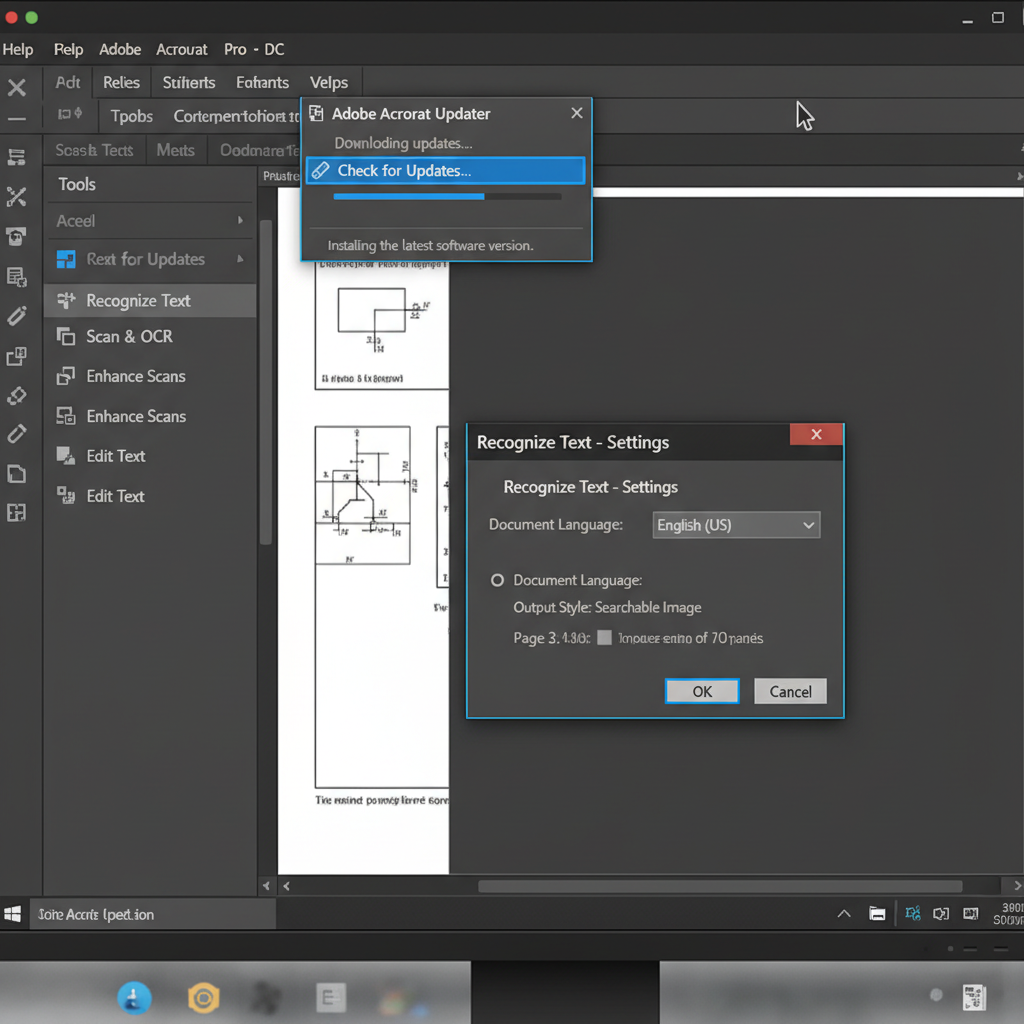
Open Adobe Acrobat, click on 'Help' in the top menu, select 'Check for Updates', and install the latest software version. Restart your computer once finished.
Open the scanned PDF, zoom in, and try to highlight the text with your cursor. If the text cannot be selected, the text layer has not been created.
Navigate to 'Tools' > 'Scan & OCR' > 'Recognize Text'. Select the exact language matching your document's content and initiate the process again.
Optimize the PDF Scan Quality and File Size
Large files and low-quality scans consume high system memory and frequently cause the OCR process to fail or crash.
Use WPS PDF to Quickly Recognize Text from Scans
If Adobe Acrobat OCR continues to fail or crash, try WPS Office. WPS PDF includes a highly accurate, built-in OCR feature that quickly converts scanned documents and images into editable or searchable text with just a few clicks.
- 1. Open PDF in WPS: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Select Output Mode: Choose whether to extract the text to a new editable document or directly convert the PDF.
- 4. Run Recognition: Select the correct language for your document and click 'Start' to process the file.
Frequently Asked Questions
Why does OCR take so long on my PDF?
OCR processing time depends heavily on the file size, resolution of the scanned images, and your computer's available memory. Splitting large files into smaller sections can significantly speed up processing and prevent software crashes.
How do I know if the OCR process was successful?
After the OCR process completes, try using your mouse cursor to highlight and select the text on the PDF page. If the text can be highlighted, copied, or edited like a normal text document, the OCR was successful.
Does the document language setting matter when running OCR?
Yes, selecting the correct language in the OCR settings is crucial. If an incorrect language is selected, the software will struggle to recognize the characters accurately, resulting in gibberish or completely unselectable text.


