



How to Perform OCR on Russian PDF Text with Cyrillic Characters

Question details
Users need to accurately extract and convert Russian text (Cyrillic characters) from a scanned or image-based PDF into an editable Word document.
- Product
- Adobe PDF Pack / Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Converting a scanned or image-based PDF file containing Russian text into an editable Word document format.
- Observed behavior
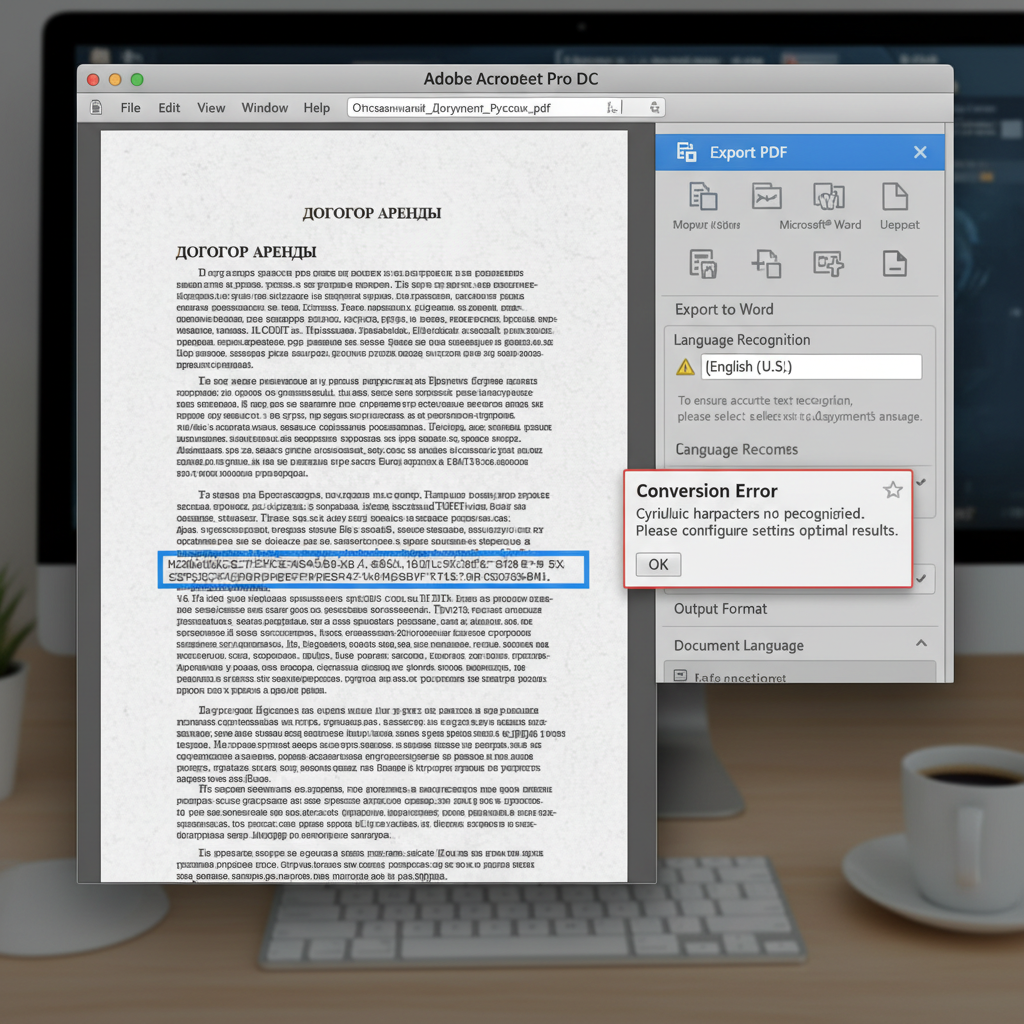
- Without proper language configuration, standard PDF conversion tools fail to recognize Cyrillic characters, resulting in unselectable text or garbled output when exported to Word.
Verify that your PDF editor includes Optical Character Recognition (OCR) capabilities and ensure you have the appropriate language packs installed, as standard English OCR will misinterpret Cyrillic characters.
Run OCR with Russian Language Settings in Adobe Acrobat
Configure the OCR engine to recognize Russian before exporting the PDF to Word to ensure Cyrillic characters map correctly.
Image-based PDFs require OCR to translate pixels into readable text. By manually changing the document language setting to Russian, you instruct the software to use the Cyrillic character set, preventing output errors during the Word conversion.
Open your document and attempt to highlight the text with your cursor. If the text cannot be selected, the PDF is scanned and requires OCR processing.
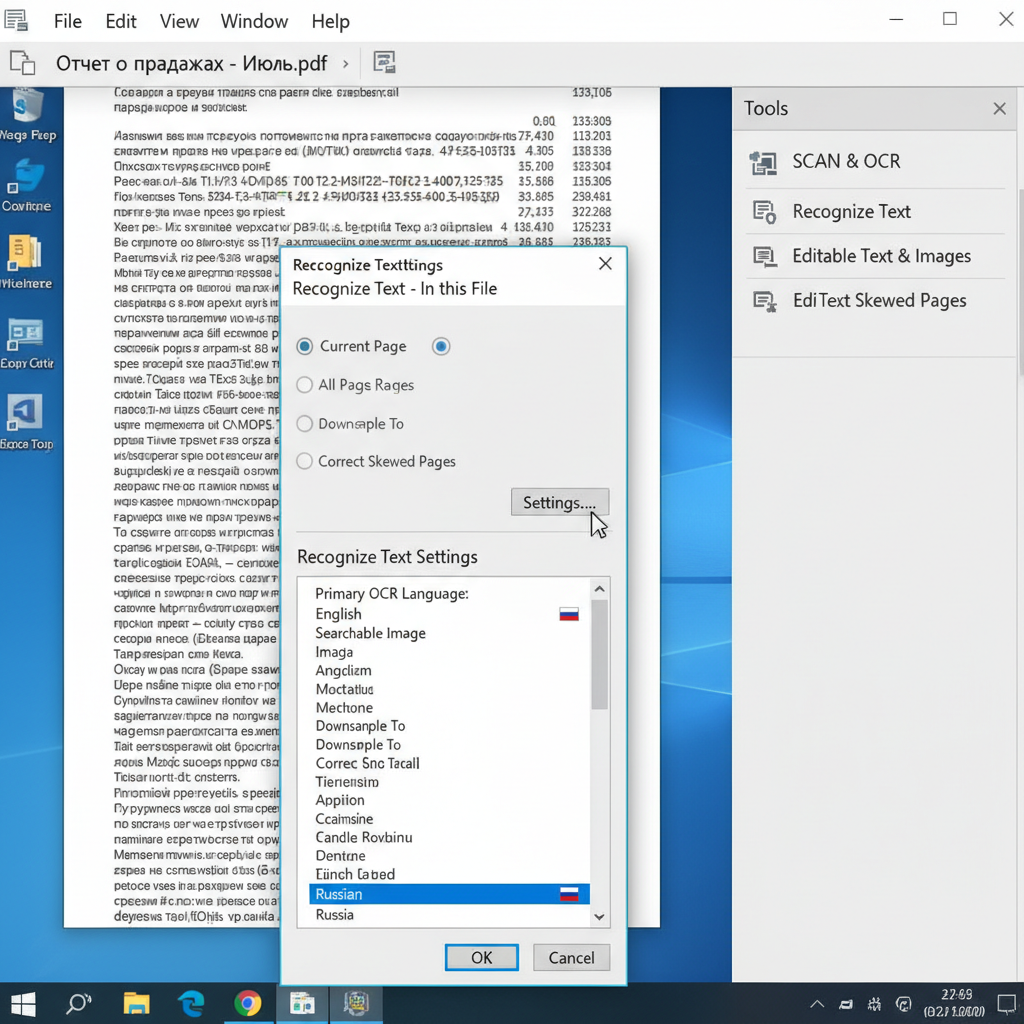
Navigate to the 'Tools' menu in Adobe Acrobat and select the 'Scan & OCR' or 'Recognize Text' option.
Click 'Recognize Text' and then select 'In this File'. Open the 'Settings' menu, choose 'Russian' from the Document Language dropdown list, and click 'OK' to start the recognition process.
Once the text is fully recognized, go to 'File', select 'Export To', choose 'Microsoft Word', and then click 'Word Document' to save your newly converted file.
Easily Extract Russian Text with WPS Office
WPS Office features a powerful, built-in OCR engine that accurately recognizes multiple languages, including Russian. It allows you to convert scanned PDFs into editable Word documents quickly and accurately, without the need for complex add-ons.
- 1. Open the PDF in WPS Office: Launch WPS Office and open your scanned Russian PDF document.
- 2. Activate the OCR tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Select Russian as the language: In the OCR settings prompt, ensure the recognition language is set to Russian so the engine properly identifies Cyrillic characters.
- 4. Convert to Word: Choose the option to extract the text to an editable Word document and save the final file to your local drive.
Frequently Asked Questions
Why do my Russian Cyrillic characters turn into gibberish when exported to Word?
This typically happens because the PDF is image-based and the software's OCR engine is defaulting to English. To fix this, you must explicitly set the OCR recognition language to Russian before exporting.
Do I need a special add-on to OCR Russian text?
Basic PDF readers cannot perform OCR. You will need a premium PDF editor like Adobe Acrobat Pro or a comprehensive software suite like WPS Office that features built-in multi-language OCR capabilities.
Can I perform OCR on a multi-language document containing both English and Russian?
Yes, many advanced OCR tools allow you to select multiple recognition languages. Be sure to check both English and Russian in the language settings before running the OCR process.


