



How to Translate a Scanned Swedish PDF Book into English
Question details
The user needs to translate a Swedish book that has been scanned and saved as a PDF into English, which requires converting the image-based document into searchable text.
- Product
- Adobe Acrobat / PDF Editors
- Device & OS
- not provided
- Scenario
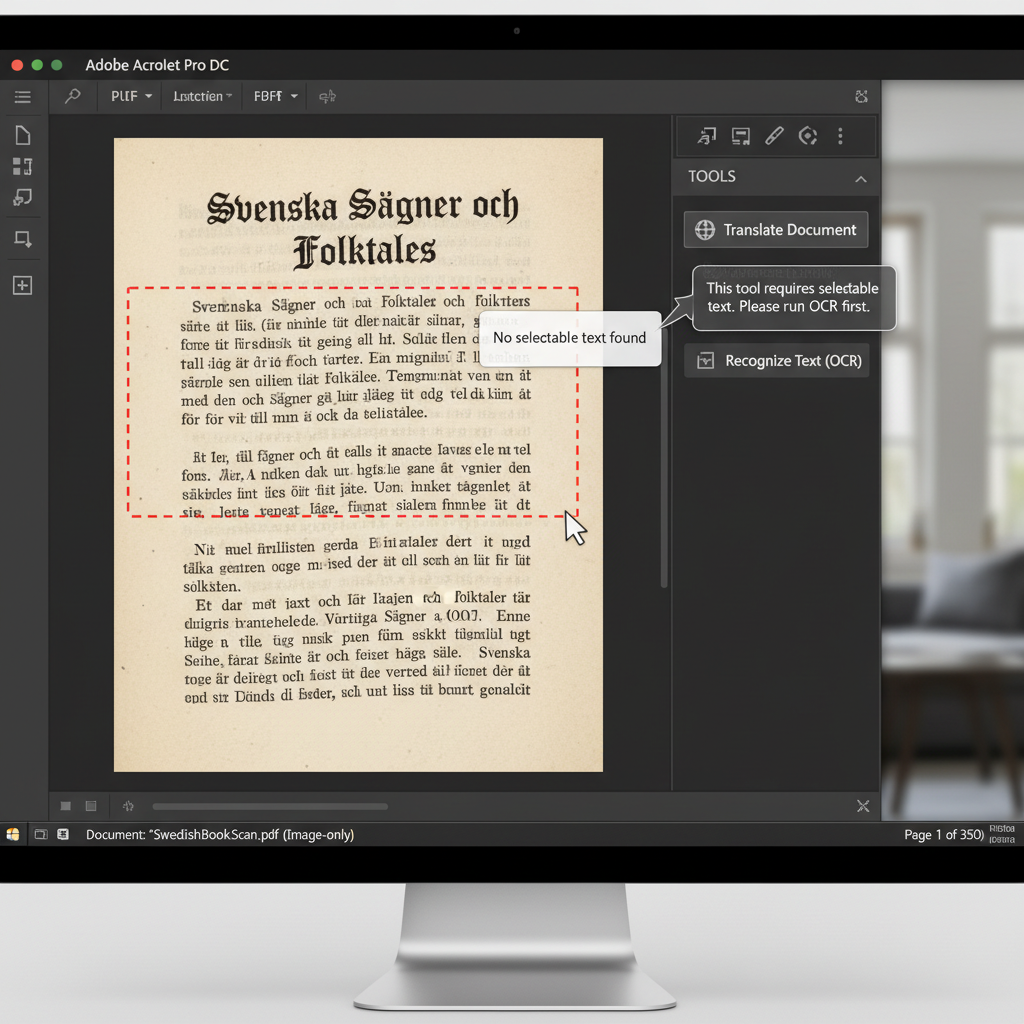
- Attempting to translate a scanned, image-only Swedish PDF document into English.
- Observed behavior
- Standard translation tools cannot process the document because the scanned PDF consists entirely of images without any selectable text.
Ensure you have a high-resolution version of the scanned PDF, as clear text significantly improves OCR accuracy for Swedish characters like å, ä, and ö.
Use Adobe Acrobat Scan & OCR for Text Extraction
Leverage Adobe Acrobat's built-in OCR capabilities to make the Swedish text selectable before applying a translation tool.
Because scanned books are essentially flat images, you must first use Optical Character Recognition (OCR) to convert those images into readable text. Once the text is selectable, it can be exported or translated directly.
Launch Adobe Acrobat and open your scanned Swedish PDF book.
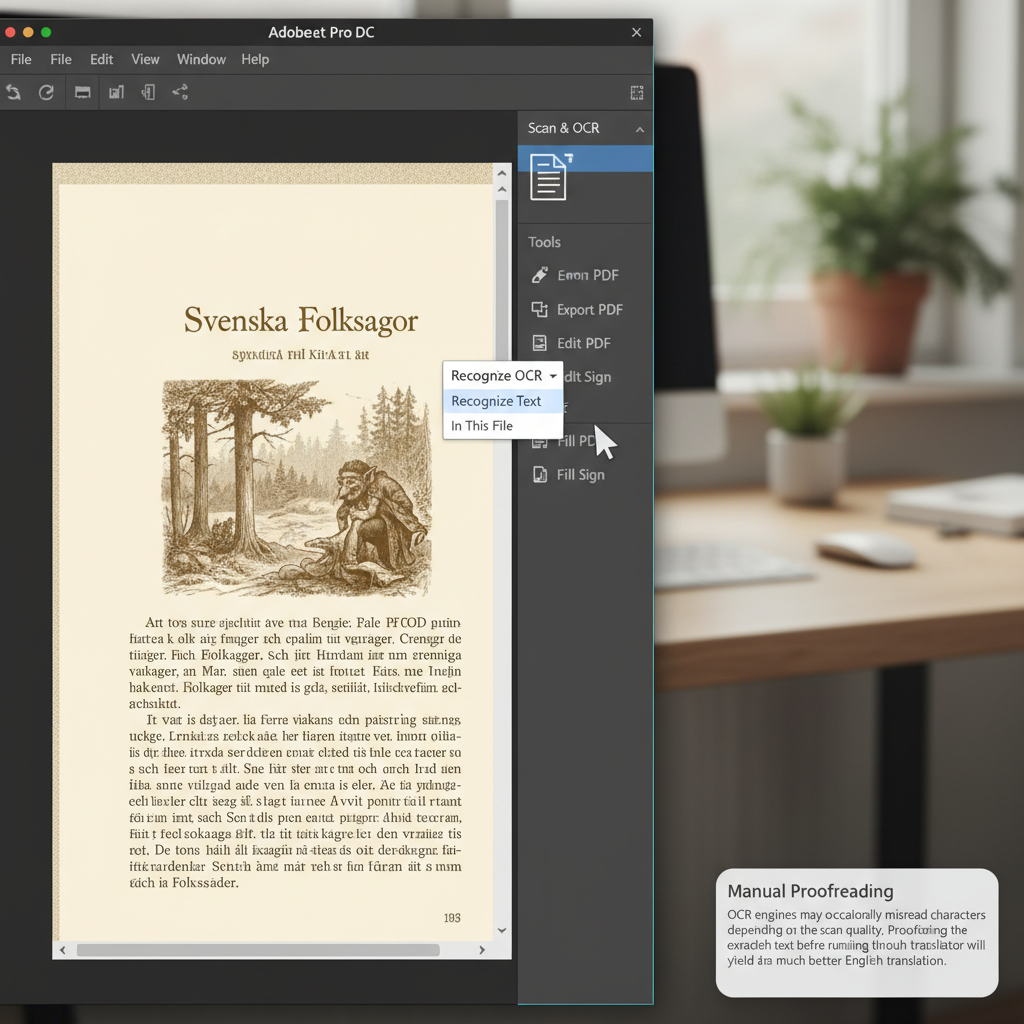
Navigate to the Tools menu and select 'Scan & OCR'. Choose 'Recognize Text' and ensure the recognition language is set to Swedish to capture special characters accurately.
If your Acrobat subscription and region support it, use the built-in translation feature. Otherwise, proceed to the next step.
Export the newly recognized text to Microsoft Word or plain text via 'File > Export To'. Upload this document to a trusted translation service like Google Translate or DeepL to convert the text to English.
Carefully review the English output. Scanned-book formatting, character names, and specialized terms often require manual correction after OCR and translation.
Use Free Online OCR and Translation Services
If you do not have an Adobe Acrobat subscription, you can use web-based OCR tools to extract the text and translate it.
Extract and Translate PDF Text with WPS Office
WPS Office provides a powerful, built-in OCR feature to quickly recognize text from scanned PDFs. You can convert the scanned book into an editable Word document and use the integrated translation tools to convert it from Swedish to English seamlessly.
- 1. Open the PDF in WPS Office: Launch WPS Office and open your scanned Swedish PDF document.
- 2. Apply OCR: Go to the 'Tools' tab and select 'OCR'. Choose 'Extract Text' or 'Convert to Word' to process the scanned images into editable text.
- 3. Translate to English: Once the document is converted into a Word format, navigate to the 'Review' tab, click 'Translate', and select Swedish to English to complete your translation.
Frequently Asked Questions
Why do I need to use OCR before translating my PDF?
Scanned PDFs are effectively digital photographs of book pages. Since they lack underlying text layers, standard translation tools cannot read or process the words. OCR (Optical Character Recognition) analyzes these images and creates actual, selectable text that a translator can understand.
Will OCR tools accurately recognize Swedish characters like å, ä, and ö?
Yes, most modern OCR engines can accurately recognize Swedish characters, but you must explicitly set 'Swedish' as the recognition language in your OCR software's settings before running the scan.
How can I keep the original book layout after translating it?
Maintaining precise formatting from a scanned book can be difficult. Your best option is to use the OCR tool to export the document directly into a Word file (.docx). This attempts to preserve paragraphs and image placement, which you can manually adjust after translating.


