



How to Calculate Questionnaire Subscale Statistics in Excel Pivot Tables

Question details
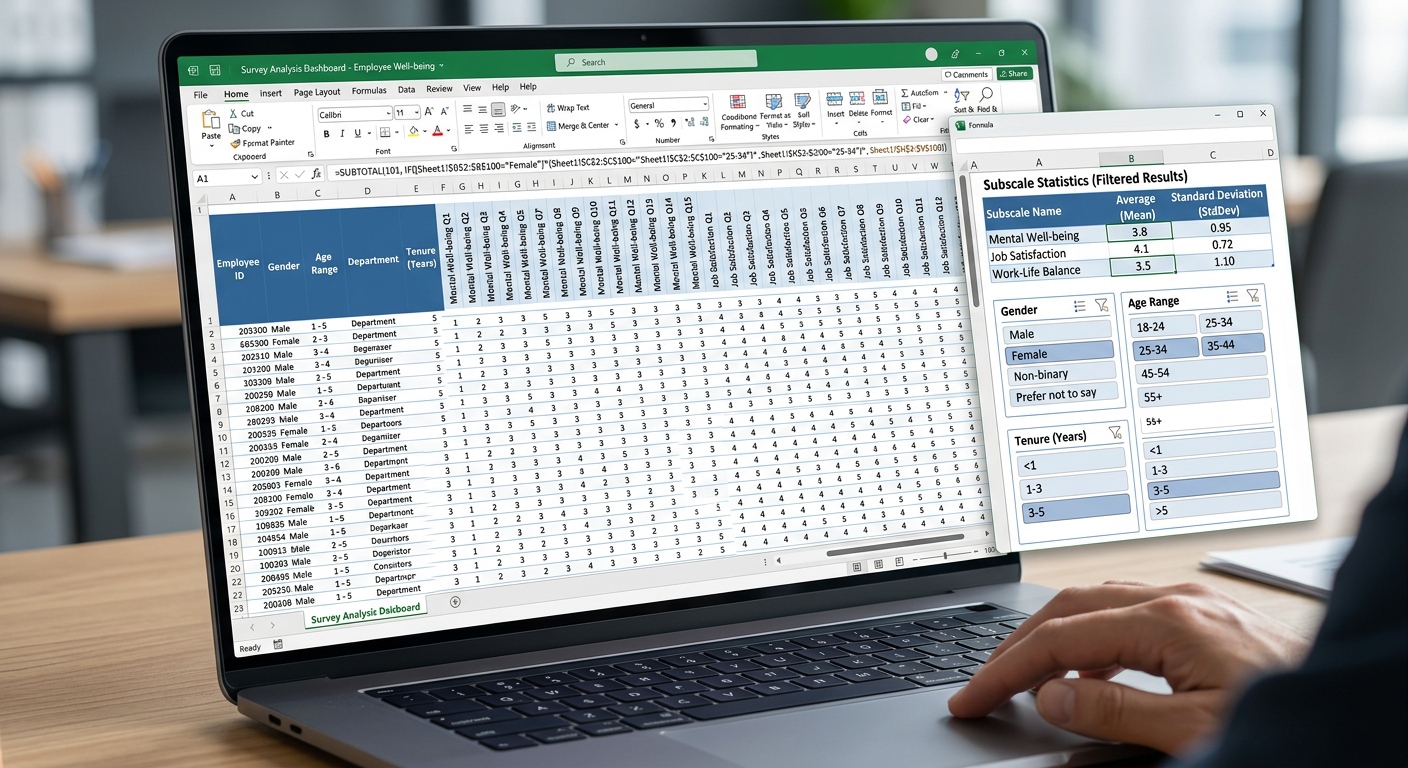
The user needs to calculate the average and standard deviation for multiple questionnaire subscales in Excel while keeping the ability to filter the results by demographic factors such as gender, age, and duration.
- Product
- Excel
- Device & OS
- not provided
- Scenario
- Analyzing survey data containing over 80 Likert-scale questions grouped into various subscales.
- Observed behavior
- Requires a dynamic data summarization method that calculates subscale averages and standard deviations based on user-selected demographic filters.
Ensure your survey data is formatted as an Excel Table (press Ctrl+T) and that all your Likert-scale responses are converted to numeric values (e.g., 1 to 5) rather than text strings.
Use Source Data Calculated Columns and a Pivot Table
Calculate individual respondent scores for each subscale directly in the source data table first, then summarize those calculated results using a Pivot Table to maintain full filtering capabilities.
Calculating standard deviation directly on grouped Pivot Table fields can yield mathematically inaccurate results for subscales. By adding helper columns to the source data, you calculate the individual respondent's score first, allowing the Pivot Table to correctly calculate the overall aggregate average and standard deviation for any filtered subgroup.
Navigate to the first empty column next to your survey data. Name the column header after your subscale (e.g., 'Subscale A').
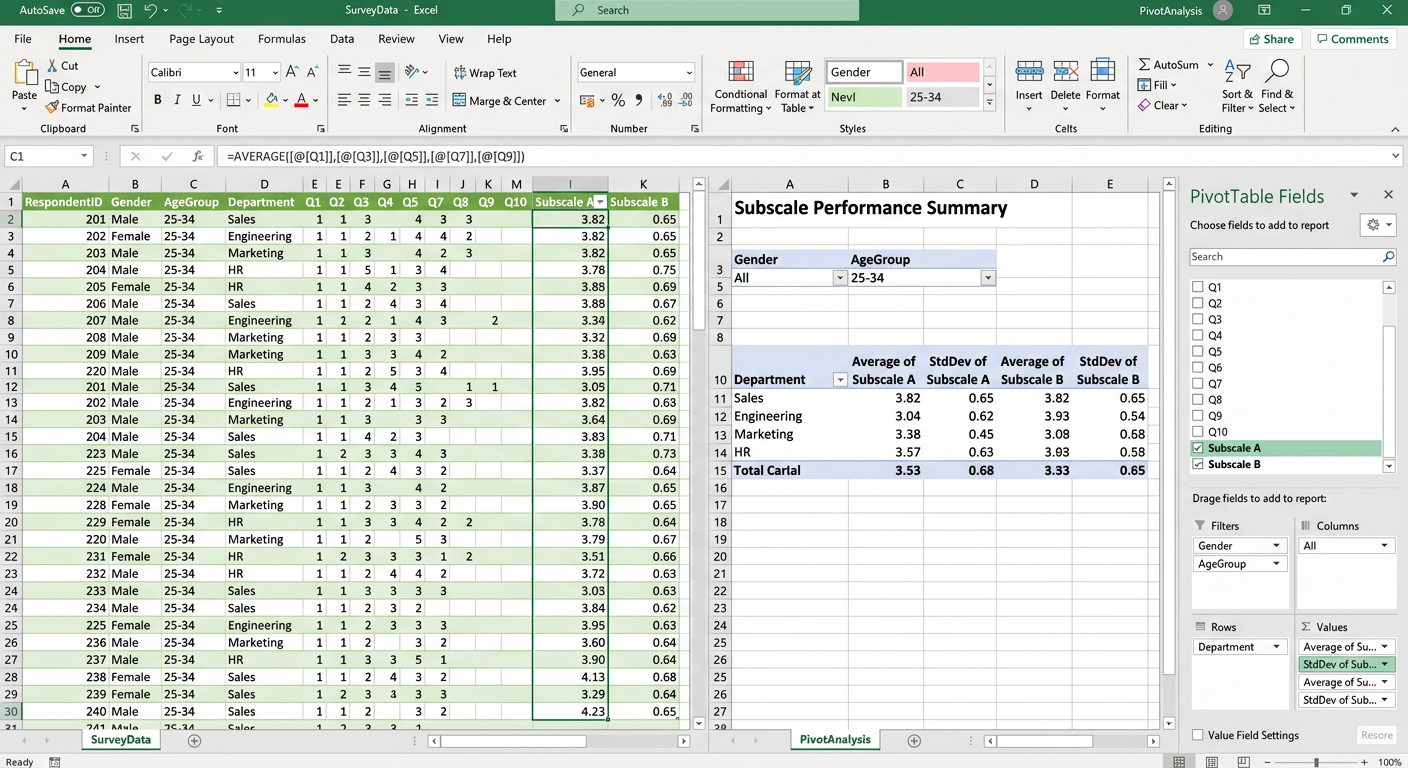
Enter the formula to average the specific questions belonging to that subscale. For example, use =AVERAGE([@[Question 1]],[@[Question 2]]) and press Enter. Repeat this process to create separate columns for all your subscales.
Click anywhere inside your data table, go to the 'Insert' tab on the ribbon, and click 'PivotTable'. Choose to place it on a New Worksheet and click 'OK'.
In the PivotTable Fields pane, drag your demographic fields (such as Gender, Age, and Duration) into the 'Filters' or 'Rows' areas depending on how you want to segment the data.
Drag your newly created 'Subscale A' field into the 'Values' area twice.
Click the first 'Subscale A' in the Values area, select 'Value Field Settings', choose 'Average', and click 'OK'. Click the second 'Subscale A', select 'Value Field Settings', scroll down to choose 'StdDev' (Standard Deviation), and click 'OK'.
Analyze Survey Data Easily with WPS Spreadsheet
WPS Spreadsheet offers powerful Pivot Table capabilities, allowing you to seamlessly calculate averages, standard deviations, and apply complex demographic filters to your survey data just like you would in Microsoft Excel.
- 1. Open Data: Launch WPS Spreadsheet and open your questionnaire dataset.
- 2. Calculate Subscales: Add a new column next to your data and use the =AVERAGE() function to group and calculate individual subscale scores.
- 3. Create Pivot Table: Highlight your data, navigate to the 'Insert' tab, and click 'PivotTable'.
- 4. Organize Demographics: Drag your desired filtering variables (like Age or Gender) into the Rows or Filters areas in the Pivot Table pane.
- 5. Summarize Values: Drag your subscale columns into the Values area, click 'Value Field Settings', and select 'Average' or 'StdDev' to get your final statistics.
Frequently Asked Questions
Can I group multiple Likert questions inside the Pivot Table without adding source columns?
While you can use Calculated Fields in a Pivot Table, calculating the Standard Deviation on an average of averages within the Pivot Table itself often yields mathematically incorrect results. Adding helper columns to the source data is required to ensure accurate statistical outputs.
Why does my Pivot Table show 'Count' instead of 'Average' by default?
When your source data contains blank cells, errors, or non-numeric text in the subscale columns, the Pivot Table defaults to summarizing by 'Count'. Ensure all data points in your calculated columns are numeric, then manually change the Value Field Settings to 'Average'.
How do I handle missing responses if I require a minimum number of answered questions per subscale?
You can use an IF statement combined with COUNT in your source data. For example, if a subscale has 5 questions and you require at least 4 answers, use a formula like: =IF(COUNT([@[Q1]],[@[Q2]],[@[Q3]],[@[Q4]],[@[Q5]])>=4, AVERAGE([@[Q1]],[@[Q2]],[@[Q3]],[@[Q4]],[@[Q5]]), "") to exclude respondents who didn't meet the threshold.


