



How to Compare Repeated PDF Header Data and Consolidate Columns in Power Query

Question details
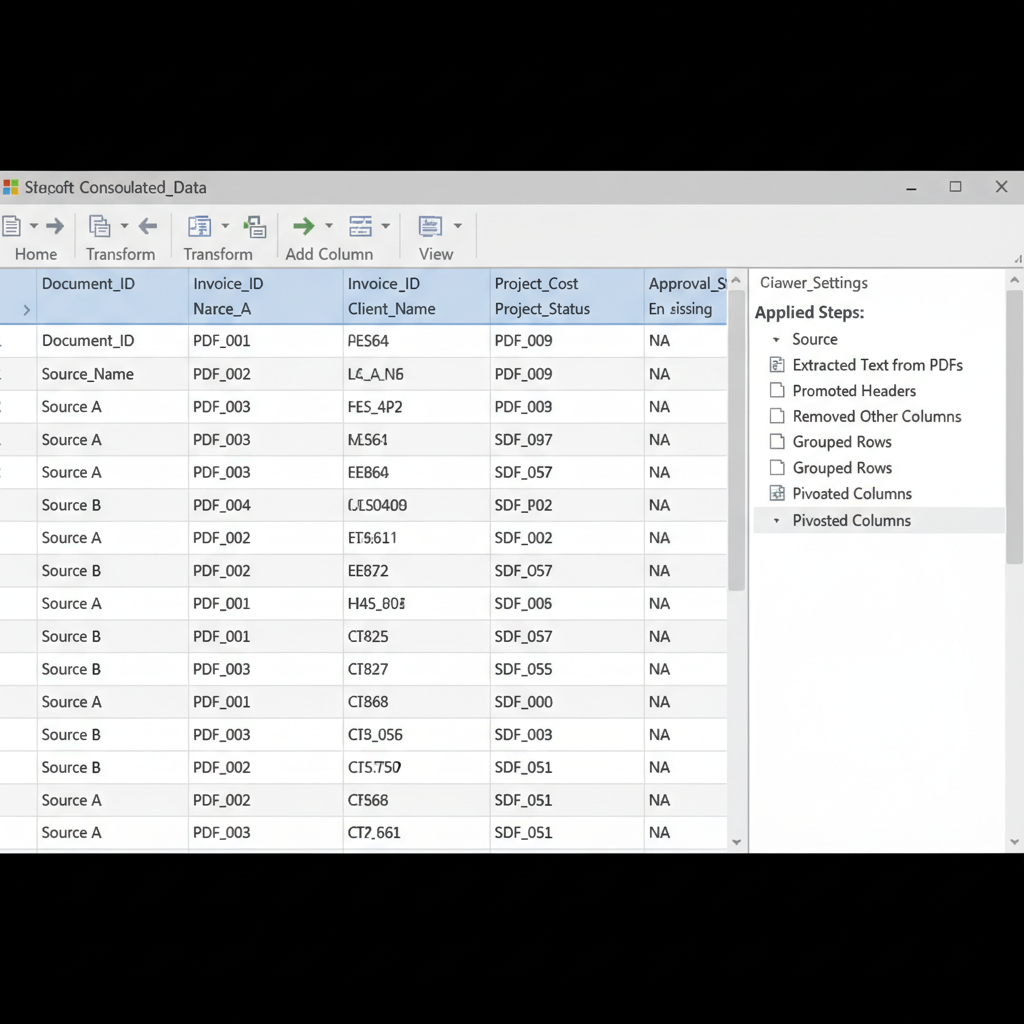
The user needs to verify matching values from repeated header data extracted from multiple PDFs and consolidate them into a two-column or pivoted table using Power Query.
- Product
- Excel
- Device & OS
- not provided
- Scenario
- Extracting and cleaning tabular data from multiple PDF files where identical header information is duplicated across columns.
- Observed behavior
- The extracted dataset contains redundant header columns such as IDs and source names, which need to be cleaned, deduplicated, and pivoted into a consolidated table structure.
Ensure that all your source PDF files have consistent table structures before importing them into Power Query to prevent column mismatch errors.
Clean Columns and Pivot Data Using Query Editor
Use the standard Power Query Editor interface to remove unnecessary identifier columns, deduplicate rows, and pivot the source data into consolidated columns.
This approach uses the graphical user interface of Power Query to clean up repeated PDF headers without needing to write complex code from scratch.
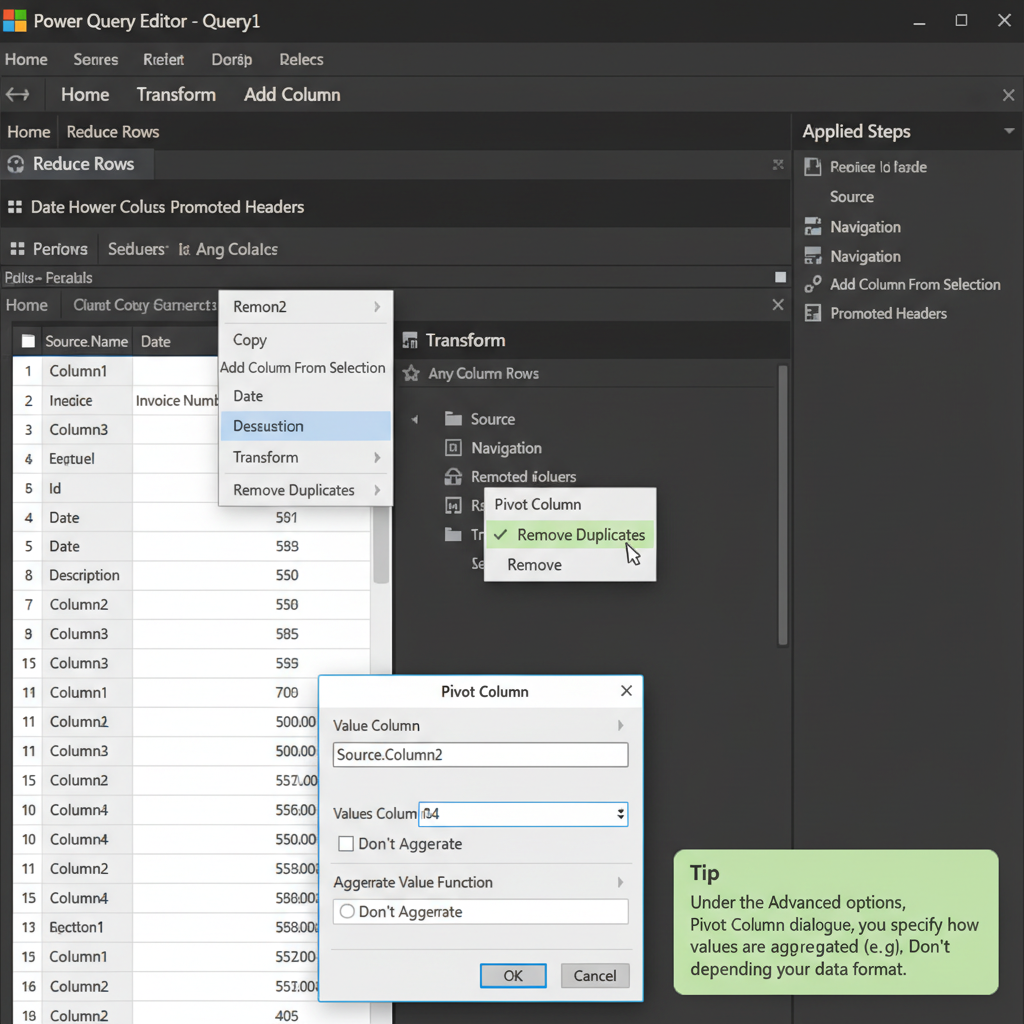
Open the Power Query Editor, locate the first two columns (such as 'Id'), right-click the column headers, and select 'Remove'.
Select the remaining columns that contain your extracted PDF data. Navigate to the 'Home' tab, click 'Remove Rows', and choose 'Remove Duplicates' to filter out the repeated headers.
Select the 'Source.Name' column. Go to the 'Transform' tab and click 'Pivot Column'. In the popup window, select 'Data.Column2' (or your target value column) as the Values Column, and click OK to consolidate the data.
Apply Custom M Code via Advanced Editor
Directly paste custom M code to automate the process of changing data types, removing columns, and pivoting the table.
Use WPS Spreadsheets for Fast Data Consolidation
While advanced Power Query M code is specific to Excel, WPS Office provides an incredibly lightweight and free alternative. With powerful native PivotTables, built-in PDF-to-Excel extraction, and excellent format compatibility, WPS Office makes handling document data seamless.
- 1. Download WPS Office: Install WPS Office for free to access robust Spreadsheets and premium PDF tools.
- 2. Extract PDF Data: Use the built-in PDF to Excel converter to extract your tabular data cleanly without writing complex queries.
- 3. Consolidate with PivotTables: Select your extracted data, navigate to the Insert tab, click PivotTable, and configure your rows and columns to consolidate the information.
Frequently Asked Questions
Can I extract data directly from multiple PDFs simultaneously?
Yes. In Power Query, you can select 'Get Data', then 'From File', and choose 'From Folder'. This allows you to import and combine multiple PDFs located in the same directory at once.
Why does Power Query duplicate my header columns during PDF extraction?
When extracting tables from multiple PDFs, Power Query reads each page's table header individually. If the tables are appended without filtering out the header rows from subsequent files, those headers will appear repeatedly in your dataset.
What does the Table.Pivot function do in M code?
The Table.Pivot function takes unique values from a specified attribute column (like 'Source.Name') and turns them into individual column headers, consolidating the corresponding values beneath them for a cleaner dataset.


