



How to Remove Duplicate Text from Adjacent Columns in Power Query
Question details
The user needs to remove or replace repeated text values with nulls in adjacent columns across individual rows in Power Query.
- Product
- Microsoft Excel (Power Query)
- Device & OS
- not provided
- Scenario
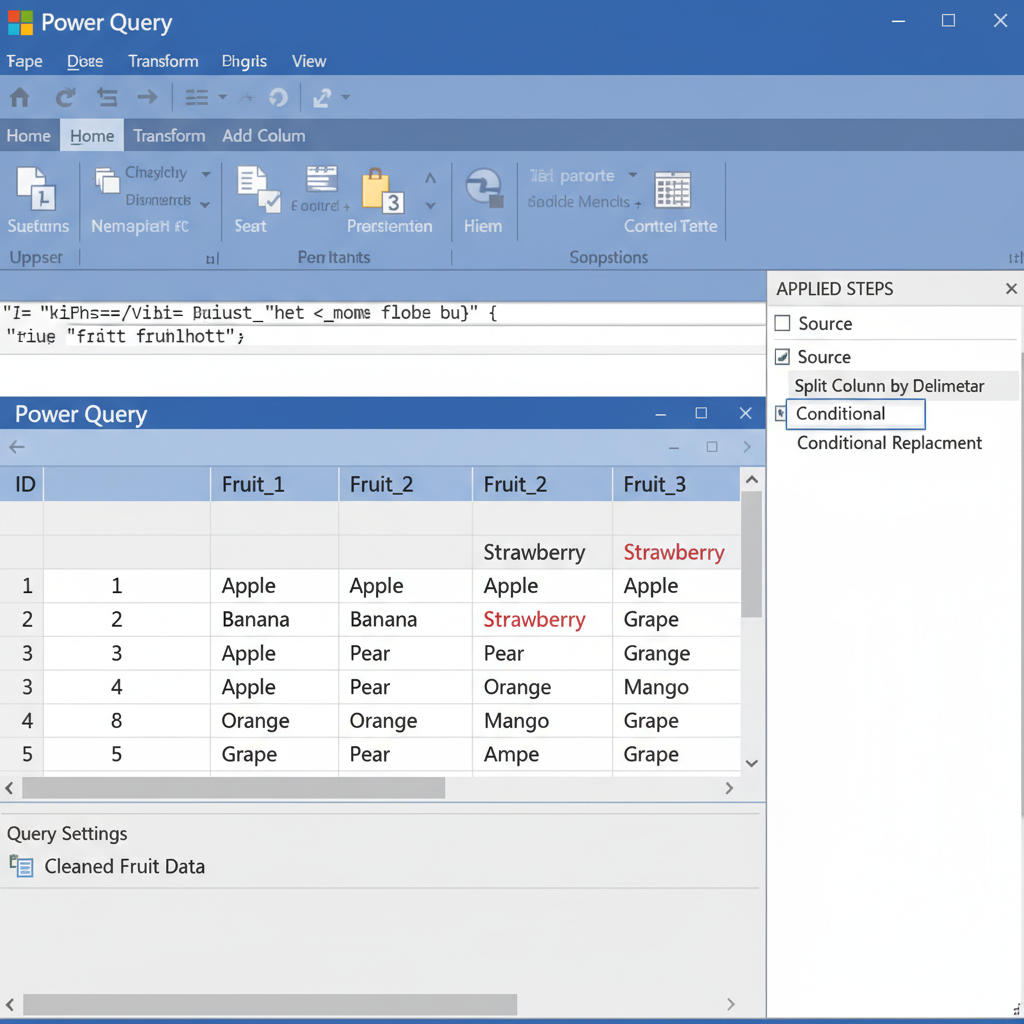
- Data has been split into multiple columns, resulting in duplicate values appearing side-by-side in adjacent columns across the same row. The goal is to clean the data by keeping only the distinct values and replacing adjacent duplicates with nulls.
- Observed behavior
- Duplicate values currently populate adjacent columns after a text split, whereas the desired output should display null values where the text repeats from the previous column.
Before applying custom transformations, ensure your source data columns are formatted as Text and clearly identify which adjacent columns need to be evaluated for duplicates.
Use Custom M Code and List.Distinct in Advanced Editor
Use a custom Power Query M script to evaluate rows as lists, extract distinct values, and replace duplicates with nulls dynamically.
This solution relies on generating a row record and applying the List.Distinct function. By stripping out duplicate values and padding the list with nulls, you maintain your column structure without repeated text.
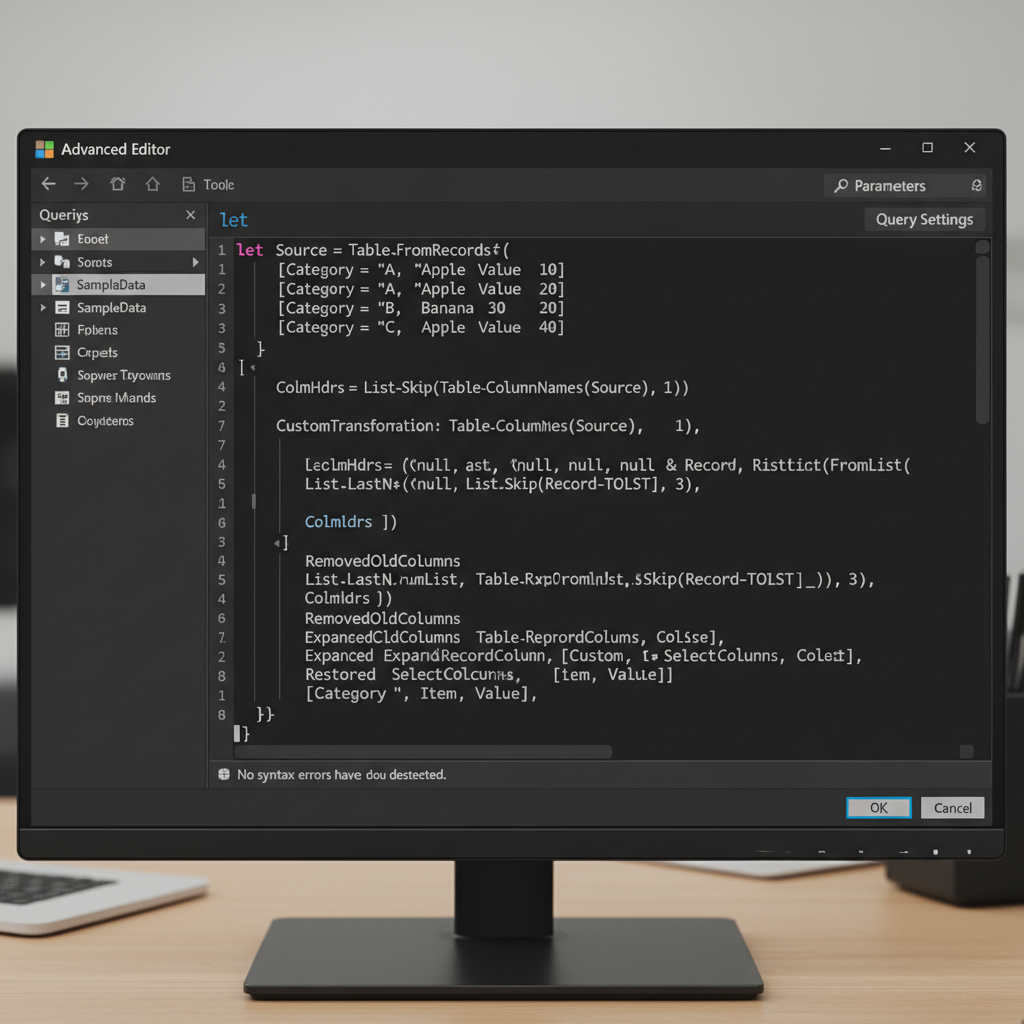
In the Power Query Editor, go to the Home tab and click on 'Advanced Editor' to view your current M code.
Create a variable for your column headers to skip the first column if necessary, using code like: ColmHdrs = List.Skip(Table.ColumnNames(Source), 1).
Add a new column that converts the row to a list, extracts distinct values, and fills the rest with nulls: Table.AddColumn(Source, "Custom", each Record.FromList(List.LastN({null, null, null} & List.Distinct(List.Skip(Record.ToList(_), 1)), 3), ColmHdrs)).
Use Table.RemoveColumns to delete the original duplicate-heavy columns, then use Table.ExpandRecordColumn to expand your new 'Custom' column back into individual adjacent columns.
Use the Conditional Column Feature (For Fewer Columns)
If you only have two or three adjacent columns to compare, you can use built-in conditional logic instead of writing complex M scripts.
Remove Adjacent Duplicates Fast using WPS Spreadsheet
If you want to avoid complex Power Query M scripts, you can quickly remove adjacent duplicate text using built-in IF formulas in WPS Spreadsheet. It provides a lightweight, highly compatible alternative for data cleaning without requiring coding knowledge.
- 1. Open Your Data: Launch WPS Spreadsheet and open the document containing the duplicate adjacent text.
- 2. Set Up an IF Formula: Insert a blank column next to your data. Enter the formula =IF(B2=A2, "", B2) to compare the adjacent cells.
- 3. Apply Across Rows: Click and drag the fill handle at the bottom-right of the cell to apply this logic across all necessary rows and columns.
- 4. Paste as Values: Select the newly generated data, copy it, and use 'Paste Special' > 'Values' over the original columns to finalize the cleanup.
Frequently Asked Questions
Why does Power Query return errors when replacing duplicates with nulls?
Errors usually occur due to inconsistent data types. Ensure that all adjacent columns being evaluated are strictly formatted as Text before you apply custom M code or List.Distinct functions.
How can I remove duplicate rows across the entire table instead of just adjacent cells?
To remove duplicate rows entirely, select all columns in the Power Query Editor, right-click any column header, and select 'Remove Duplicates'. This will delete the entire row if all selected cell values match another row.
Can I perform this cleanup without using Power Query?
Yes. You can use standard Excel or WPS Spreadsheet formulas, such as an IF statement (=IF(Col2=Col1, "", Col2)), in helper columns to evaluate adjacent cells and return blanks for duplicates.


