



How to Fix Variable File Paths for PDF Extraction in Power Automate Desktop

Question details
The user needs to dynamically extract PDF pages in Power Automate Desktop using variables for file paths without encountering file existence or extension errors.
- Product
- Power Automate Desktop
- Device & OS
- not provided
- Scenario
- Building automated workflows in Power Automate Desktop to process or extract pages from multiple PDF files using dynamic variables.
- Observed behavior
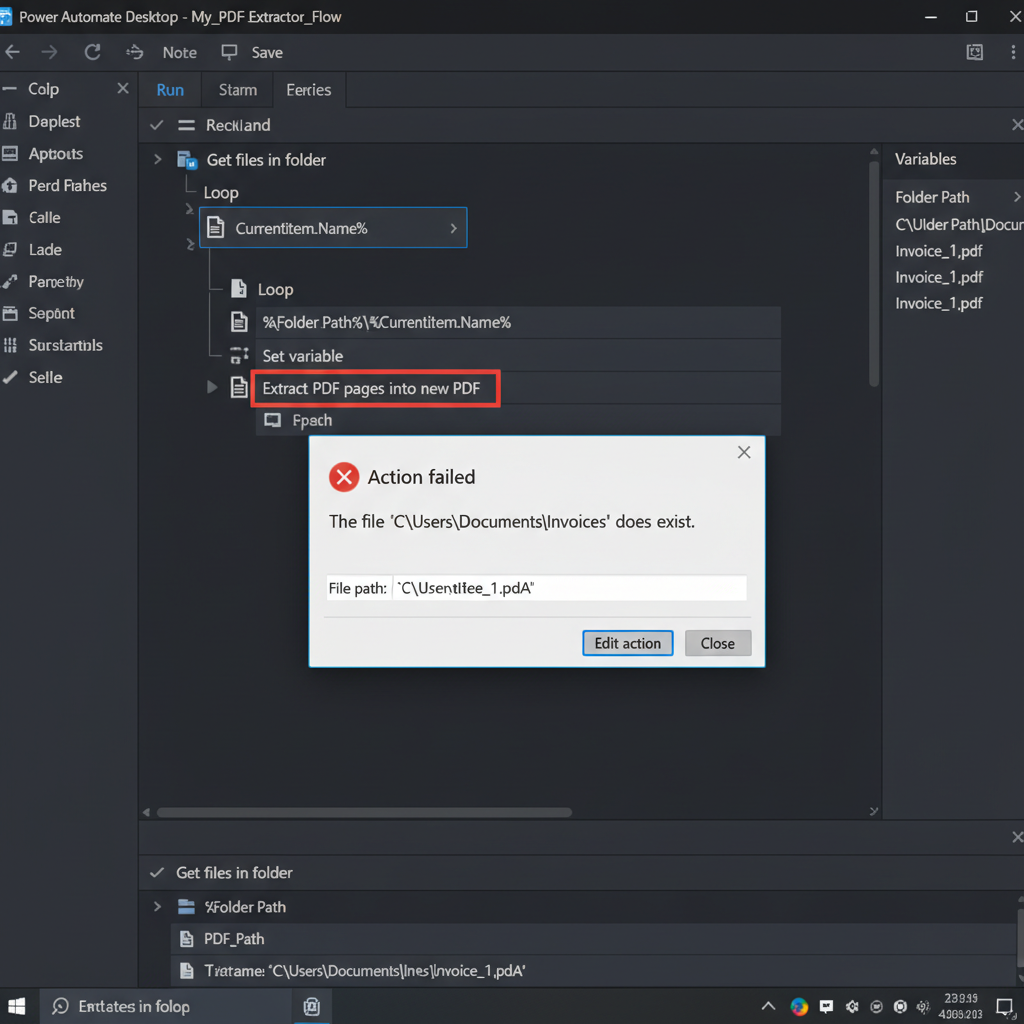
- The automation flow fails, reporting that the PDF does not exist. This is often caused by incorrectly combined folder and file name variables resulting in invalid extensions like .pdA instead of .pdf.
Verify that your base target folder and the original PDF files actually exist on your local drive, and ensure your user account has the necessary read and write permissions for that directory.
Construct and Validate the File Path in a Single Variable
Create a dedicated text variable that holds the fully constructed file path before passing it to the PDF extraction action to prevent inline formatting errors.
Errors during automated PDF extraction frequently occur when folder paths and file names are stitched together directly inside the action's input field. Combining them beforehand into a single variable ensures the path syntax and file extensions remain perfectly intact.
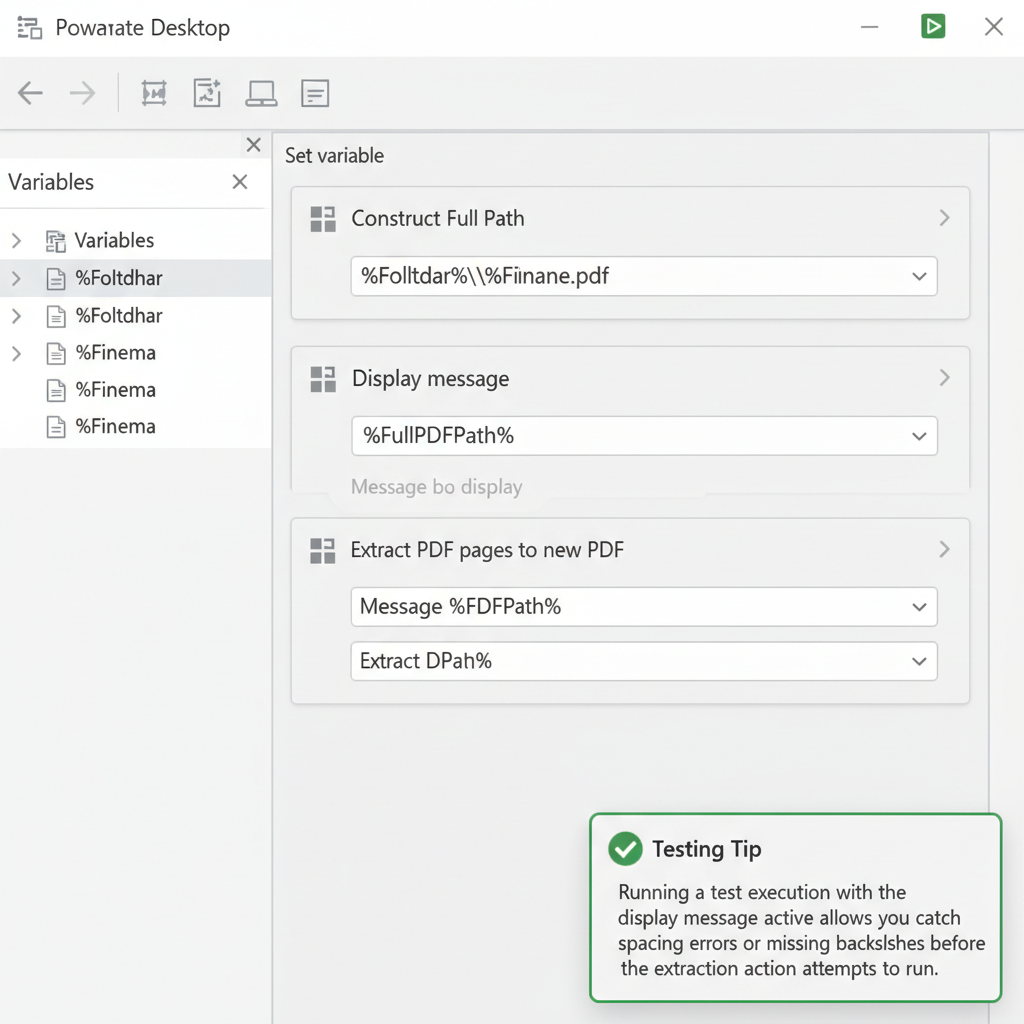
In your Power Automate Desktop flow, add a 'Set variable' action and name the new variable something clear, such as %FullPDFPath%.
In the variable value field, combine your existing folder variable and file name variable, ensuring you include a backslash. Format it as: %FolderPath%\%FileName%.pdf.
Insert a 'Display message' or 'Log message' action immediately after setting the variable to output %FullPDFPath%, allowing you to visually verify there are no typos (such as .pdA).
Open the 'Extract PDF pages to new PDF' action and replace the dynamic inline path with your verified %FullPDFPath% variable.
Extract PDF Pages Manually and Quickly with WPS Office
If setting up automated variables becomes too complex or you only need to process specific files on the fly, WPS PDF provides an intuitive, visual interface to extract, split, and manage PDF pages in just a few clicks.
- 1. Open your PDF: Launch WPS Office and open the PDF document you want to extract pages from.
- 2. Navigate to the Page tools: Click on the 'Page' tab located in the top navigation ribbon to reveal page management options.
- 3. Select Extract Page: Click the 'Extract Page' button from the toolbar menu to open the extraction dialog box.
- 4. Choose your pages: Select the specific pages, continuous ranges, or custom page numbers you wish to isolate.
- 5. Extract and save: Click 'Extract' to instantly create a new PDF containing your selected pages, then save it to your desired folder.
Frequently Asked Questions
Why does Power Automate Desktop change my PDF extension to .pdA?
This is almost always caused by a typo in the string manipulation, a misplaced wildcard, or an incorrect text replacement action running on your file name variable prior to extraction. Verifying the string via a display action helps locate the exact step causing the typo.
Can I use wildcard characters like an asterisk (*) in the file path for PDF extraction?
No, the 'Extract PDF pages to new PDF' action requires a specific, absolute file path. If you need to process multiple files, use a 'Get files in folder' action to loop through them, passing each file's absolute path dynamically.
How do I correctly insert a path separator when combining variables?
When combining a folder path and a file name in Power Automate, ensure you explicitly type a backslash (\) between the two variable names if the folder path variable does not already end with one. For example: %TargetFolder%\%DocumentName%.pdf.


