



Fix OCR Language Limitations When Converting Scanned PDFs

Question details
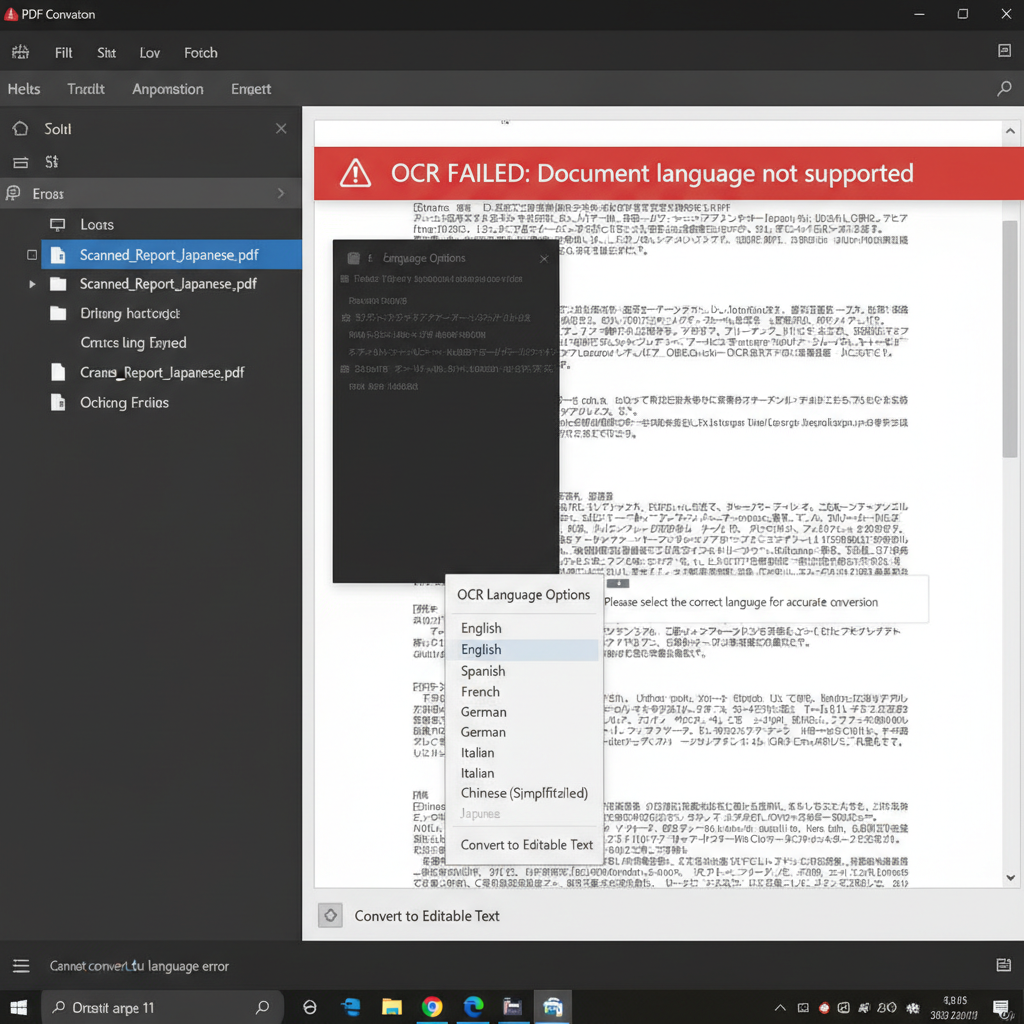
Users experience incorrect text exports when converting scanned PDFs because the available OCR language options do not include the expected document language.
- Product
- PDF Conversion Software
- Device & OS
- not provided
- Scenario
- Converting scanned PDFs or ODF files to editable text formats using Optical Character Recognition (OCR).
- Observed behavior
- The exported document contains incorrect or unrecognizable text because the PDF tool's OCR engine does not support or recognize the specific language of the scanned image.
Verify the original language of your scanned document and confirm whether your current PDF conversion service supports OCR for that specific language.
Upgrade to a Professional PDF Tool with Broader OCR Language Support
Basic PDF export services typically support a limited number of OCR languages. Upgrading to a professional PDF editor expands language compatibility for accurate text recognition.
When selecting OCR to recognize scanned PDF images, basic web or export services might support as few as seven languages. Professional desktop applications generally include advanced OCR engines that can recognize over 40 languages.
Check if your PDF actually contains scanned images. If the PDF is a natively created document with text layers, you do not need OCR, and multiple languages are naturally supported during a standard export.
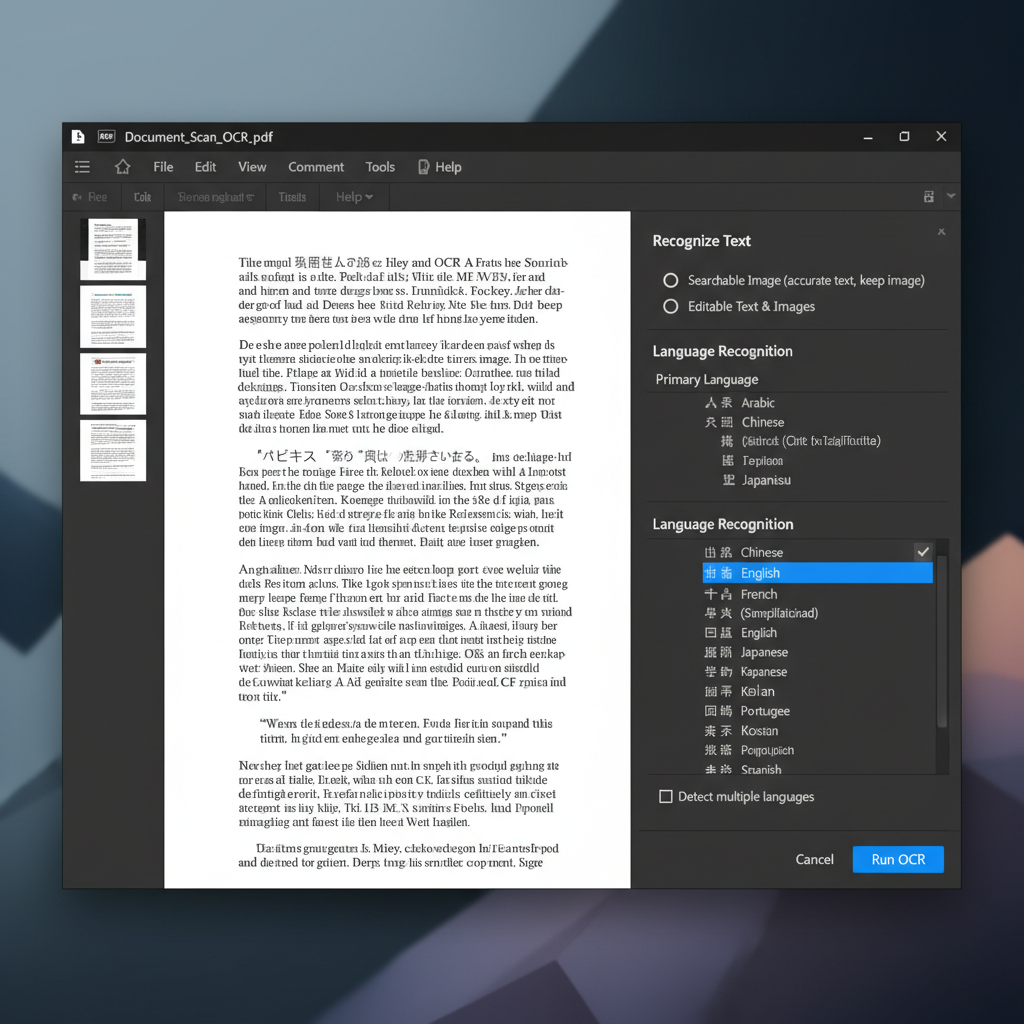
Open your PDF converter's OCR settings to see the list of available languages. If your required language is missing, you are using a limited OCR service.
Switch to a more advanced PDF editor, such as WPS Office PDF or Acrobat Pro, which provides extended OCR language packs.
Before initiating the conversion in your upgraded software, access the OCR settings and manually select the language that matches the text in your scanned document.
Extract Text Accurately with WPS PDF OCR
WPS Office provides a powerful PDF tool with robust OCR (Optical Character Recognition) capabilities, supporting multiple languages to accurately convert your scanned PDFs into fully editable documents.
- 1. Open the scanned PDF: Launch WPS Office and open the scanned PDF document you want to convert.
- 2. Access the OCR feature: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button to open the extraction tool.
- 3. Configure language settings: In the OCR dialog box, look for the language selection menu and set it to match the primary language of your scanned text.
- 4. Extract and save: Click 'Extract Text' or 'Convert to Word' to process the image. Once completed, save the newly generated editable file.
Frequently Asked Questions
Why is my converted PDF showing random or garbled characters?
This usually occurs when the OCR engine attempts to recognize text using the wrong language dictionary. Always ensure you select the correct document language in your OCR settings prior to starting the conversion.
Does OCR language support matter for standard, non-scanned PDFs?
No. Standard PDFs containing real digital text layers do not require OCR for conversion. Language limitations typically only apply when the software needs to visually recognize text from scanned images.
How many languages do standard OCR tools support?
Basic PDF export services might support only primary languages (e.g., around 7 languages). Professional PDF editors and dedicated OCR software generally support over 40 languages for accurate scanned image recognition.


