



How to Fix Incorrect OCR Text When Exporting Scanned PDFs to Word
Question details
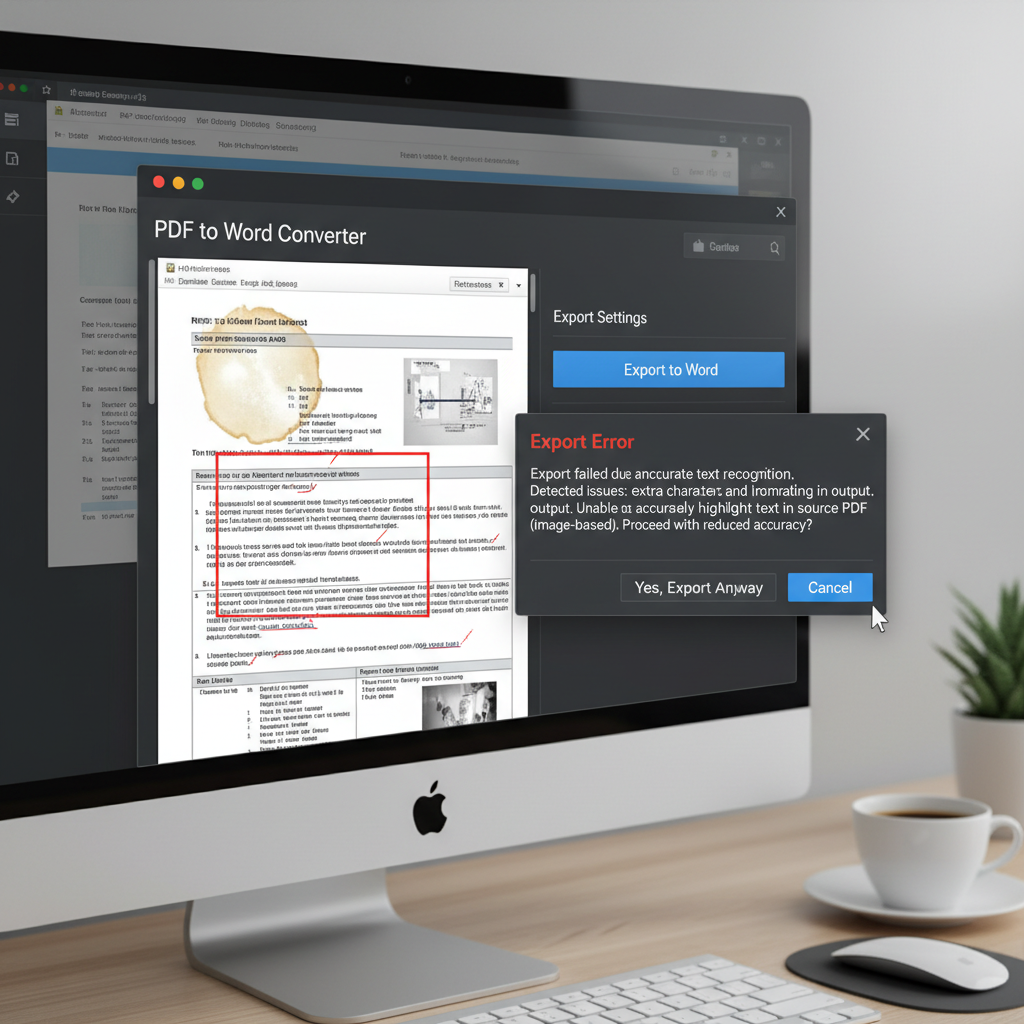
The user experiences inaccurate text recognition, highlighting issues, and random extra characters when trying to export a scanned PDF to a Word document.
- Product
- PDF to Word Converter
- Device & OS
- not provided
- Scenario
- Attempting to highlight text or export a scanned image-based PDF document to an editable Word format.
- Observed behavior
- Extra or incorrect characters appear in the exported Word document, and text cannot be accurately highlighted in the PDF because the content is recognized as an image rather than text.
Ensure your scanned PDF is clear, well-lit, and aligned straight, as low-resolution or heavily skewed images can significantly reduce the accuracy of Optical Character Recognition (OCR).
Apply Optical Character Recognition (OCR) Before Exporting
Convert the image-based scanned text into editable and selectable text using an OCR tool before attempting to export or highlight the document.
When dealing with scanned documents, the text is essentially a flat image. Standard text selection and conversion tools cannot read it properly without first processing it through OCR.
Running OCR generates a hidden text layer over the image, allowing the software to accurately map and export characters to Word.
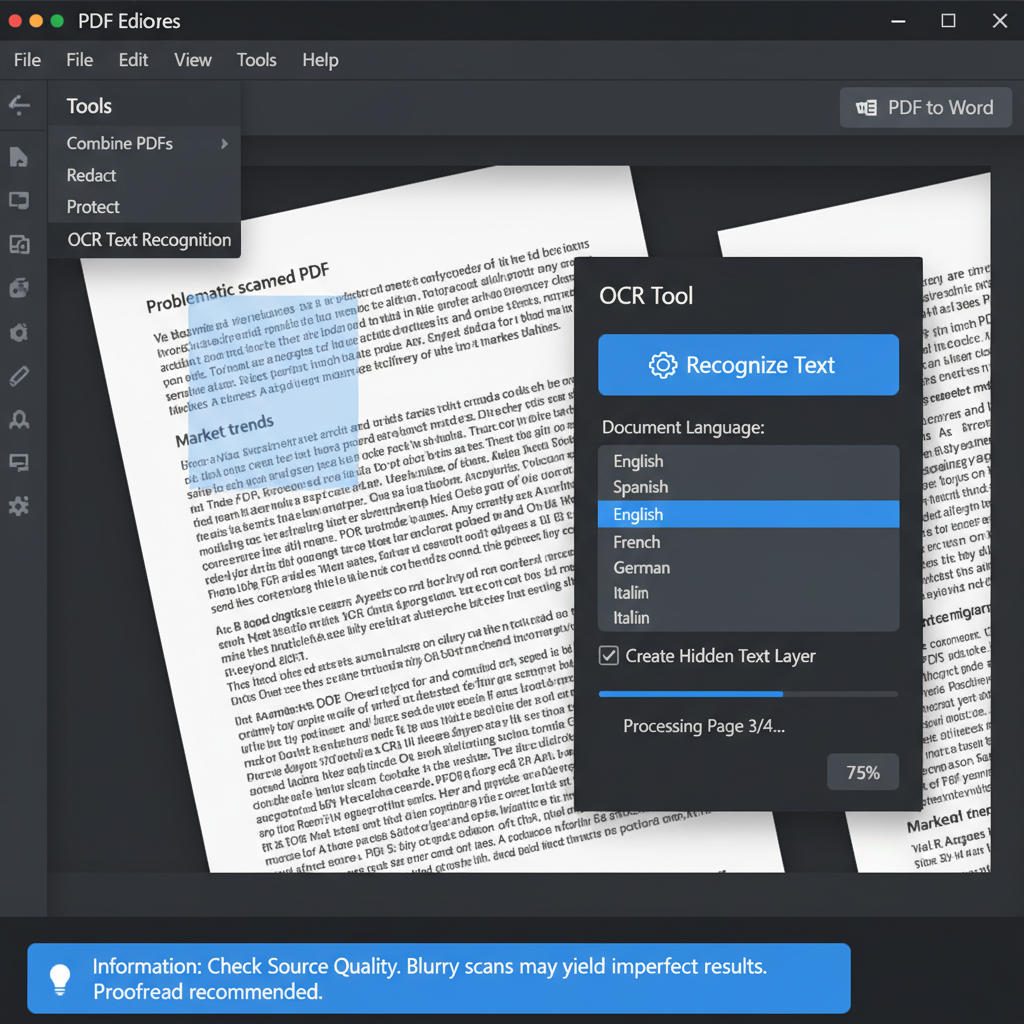
Launch a capable PDF editor that includes built-in OCR features and open the problematic scanned PDF.
Navigate to the 'Tools' or 'OCR' menu in your PDF software and select the option to recognize or extract text.
Choose the exact language of the document's text in the OCR settings to ensure high accuracy and prevent weird symbols from appearing.
Wait for the OCR process to complete, verify that you can now highlight text properly, and then use the 'PDF to Word' tool to export the document.
Contact Support for Manual Processing
If the OCR tool fails to recognize the text correctly despite good image quality, the document might require advanced manual processing by technical support.
Use WPS Office to Accurately OCR and Convert Scanned PDFs
WPS Office provides a highly accurate, built-in OCR feature that easily converts scanned image-based PDFs into editable Word documents without jumbling the text or generating random symbols.
- 1. Open the PDF: Launch WPS Office and click on the 'PDF' tab to open your scanned document in the WPS PDF editor.
- 2. Access OCR tools: Click on 'OCR' in the top toolbar or select 'PDF to Word' from the Tools menu.
- 3. Configure OCR settings: Ensure the OCR toggle is enabled in the conversion prompt and verify that the correct document language is selected.
- 4. Convert the file: Click 'Start' to process the document. WPS Office will accurately recognize the text and save your newly editable Word file.
Frequently Asked Questions
Why does my exported Word document have weird symbols instead of text?
This happens when a PDF converter tries to extract text from an image-based scanned document without utilizing Optical Character Recognition (OCR). The software misinterprets the image pixels as random characters because it cannot 'read' the image.
Does the quality of the scan affect OCR accuracy?
Yes. Low resolution, skewed angles, shadows, watermarks, or faint text will drastically reduce OCR accuracy, leading to misspelled words, missed formatting, or unrecognized characters in the final Word document.
Can I highlight text in a scanned PDF without running OCR?
No, because a scanned PDF is essentially a single flat photograph of a page. You must run OCR to generate a hidden layer of readable text over the image before any PDF reader will allow you to select or highlight individual words.
Why is it important to select the correct language before running OCR?
OCR engines use language-specific dictionaries and character maps to identify letters. If the wrong language is selected, the software will try to match the shapes to the wrong alphabet, resulting in highly inaccurate text and random symbols.


