

How to Keep OCR Text Hidden When Deskewing Scanned PDFs

Question details
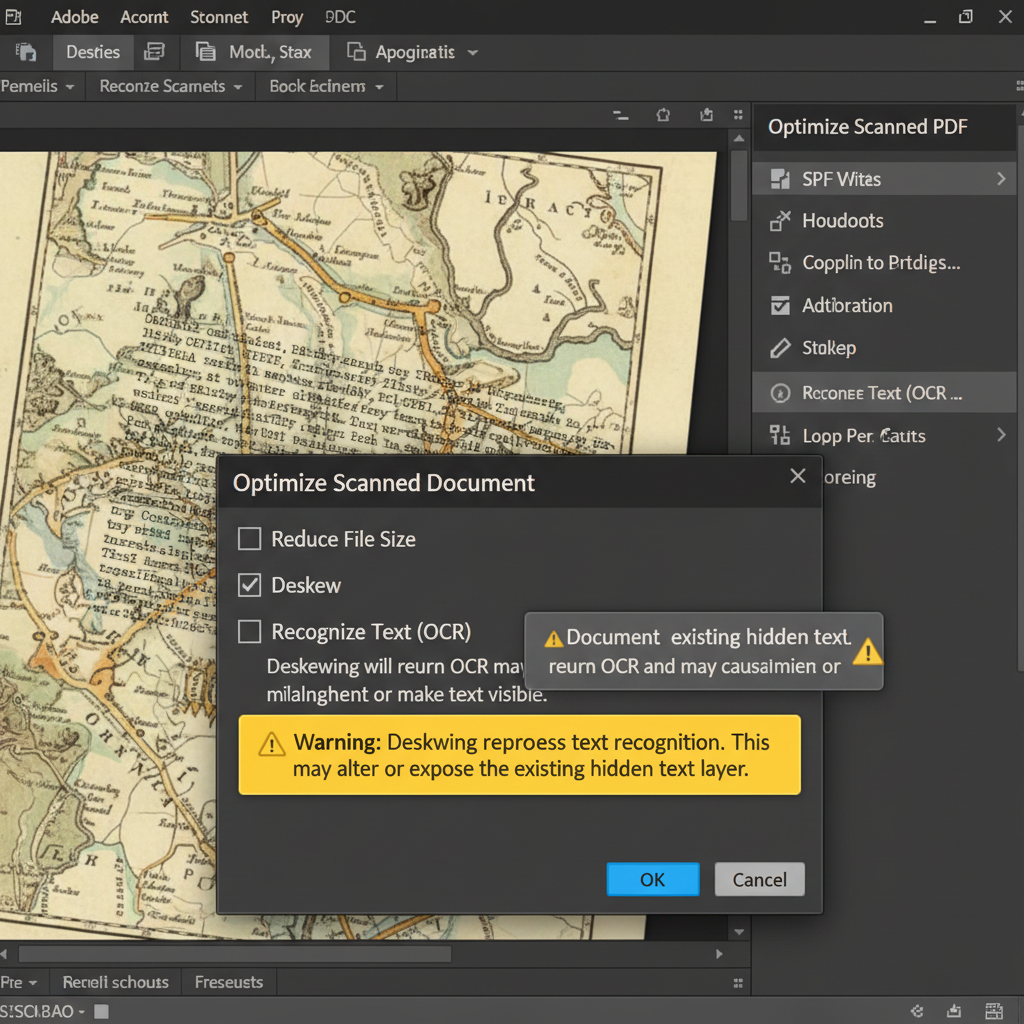
The user wants to deskew a scanned PDF without making the hidden OCR text layer visible over the page image.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Optimizing or deskewing a scanned PDF that already contains a hidden OCR text layer.
- Observed behavior
- Deskewing the document automatically triggers the OCR process, which either misaligns the hidden text layer or exposes it visibly over the scanned image.
Before deskewing your PDF, make a copy of the original file. Deskewing physically rotates the page image, which may alter the alignment of existing hidden text layers, so testing on a duplicate ensures you do not lose search accuracy.
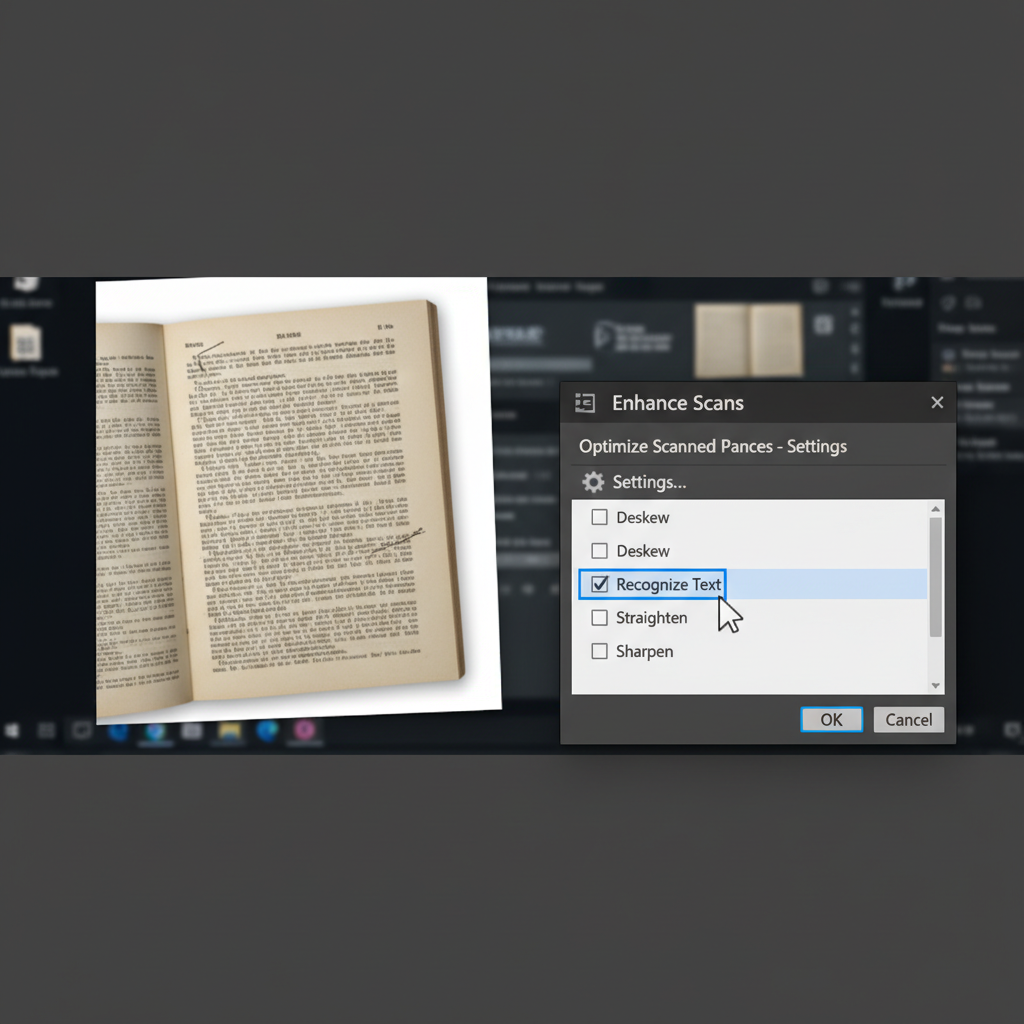
Disable 'Recognize Text' in Optimize Scanned Pages
Prevent Acrobat from automatically running OCR during the deskew process to keep the existing text layer hidden.
Acrobat links deskewing and OCR because the hidden text layer must remain perfectly aligned with the visual image. By default, running optimization will re-OCR the document, potentially making text visible. You can bypass this by adjusting the optimization settings.
Launch Adobe Acrobat Standard or Pro and open your scanned PDF document. Navigate to the 'Enhance Scans' or 'Optimize Scanned Pages' tool from the right-hand pane.
Click on the settings or options icon for the scanned page optimization process to open the detailed configuration window.
In the settings window, locate the 'Recognize Text' option and uncheck it. This ensures the software only straightens the image without running a new OCR pass.
Click 'OK' to apply the deskew. Afterward, try selecting text on the page to ensure the hidden layer is still functioning correctly.
Easily Process Scanned PDFs and OCR with WPS PDF
Avoid complicated alignment issues by using WPS PDF to manage your scanned documents. WPS PDF offers a robust built-in OCR tool that accurately extracts text from images while maintaining the original layout, giving you full control over searchable text layers and document editing.
- 1. Open the Scanned PDF: Launch WPS Office and open your scanned PDF document in the WPS PDF editor.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and select 'OCR' from the available options.
- 3. Configure OCR Settings: Choose whether you want to extract text directly or convert the document into a fully searchable PDF.
- 4. Process the Document: Adjust the page range and language settings, then click 'Recognize' to process your document accurately without unwanted visual artifacts.

Frequently Asked Questions
Why does OCR text become visible after deskewing?
In many PDF editors like Adobe Acrobat, deskewing rotates the image to straighten it. To keep the text selectable, the software often runs OCR again by default. If the settings are not configured properly, this new text layer might overlay visibly on top of the original scanned image.
Can I deskew a PDF without running OCR at all?
Yes. When using PDF optimization tools, you can usually dive into the settings and uncheck 'Recognize Text' or 'OCR' to only apply visual deskewing without altering or adding to the hidden text layer.
Will deskewing ruin the text selection of a previously OCR'd document?
It can. Because deskewing changes the physical angle of the scanned image, the existing hidden text layer might no longer match the visual words perfectly, making highlighting and selecting text slightly misaligned.
How do I fix misaligned OCR text in a scanned PDF?
If the hidden text is misaligned after deskewing, the best approach is to clear the existing OCR data entirely and run a fresh OCR pass on the newly deskewed document so the text layer maps perfectly to the straightened image.


