

How to Keep Scanned Images Visible After Acrobat OCR

Question details
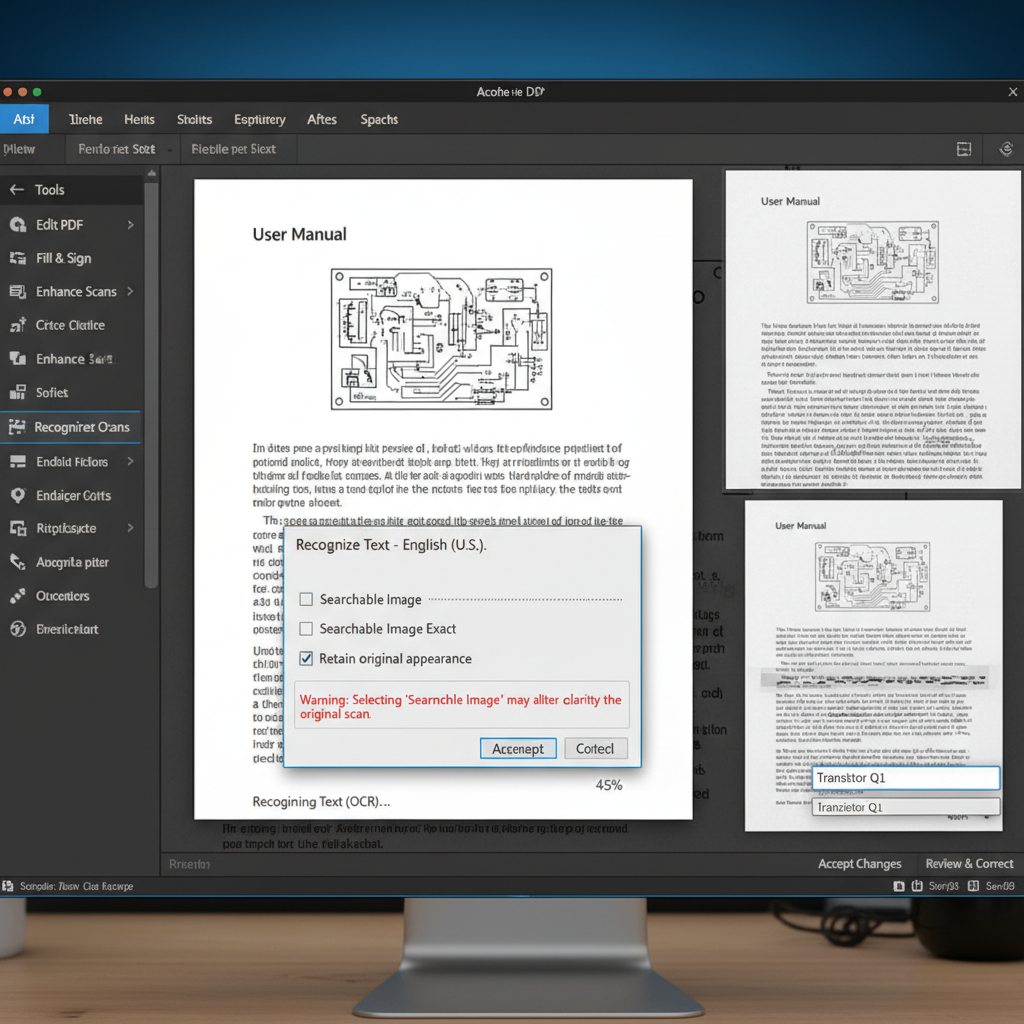
The user needs to make a scanned PDF searchable via OCR without degrading the clarity and appearance of the original scanned page.
- Product
- Adobe Acrobat DC
- Device & OS
- not provided
- Scenario
- Running OCR on a scanned document to enable text search and copying while retaining the exact original visual layout and scan quality.
- Observed behavior
- After running OCR, the scanned page image becomes visually unclear, the layout changes, and the recognized text is inaccurate.
Ensure your original scan is of high quality. Scanning at a minimum of 300 ppi and saving as a low-compression format (like TIF or high-quality JPEG) significantly improves OCR accuracy and image clarity.
Use the Searchable Image (Exact) OCR Setting
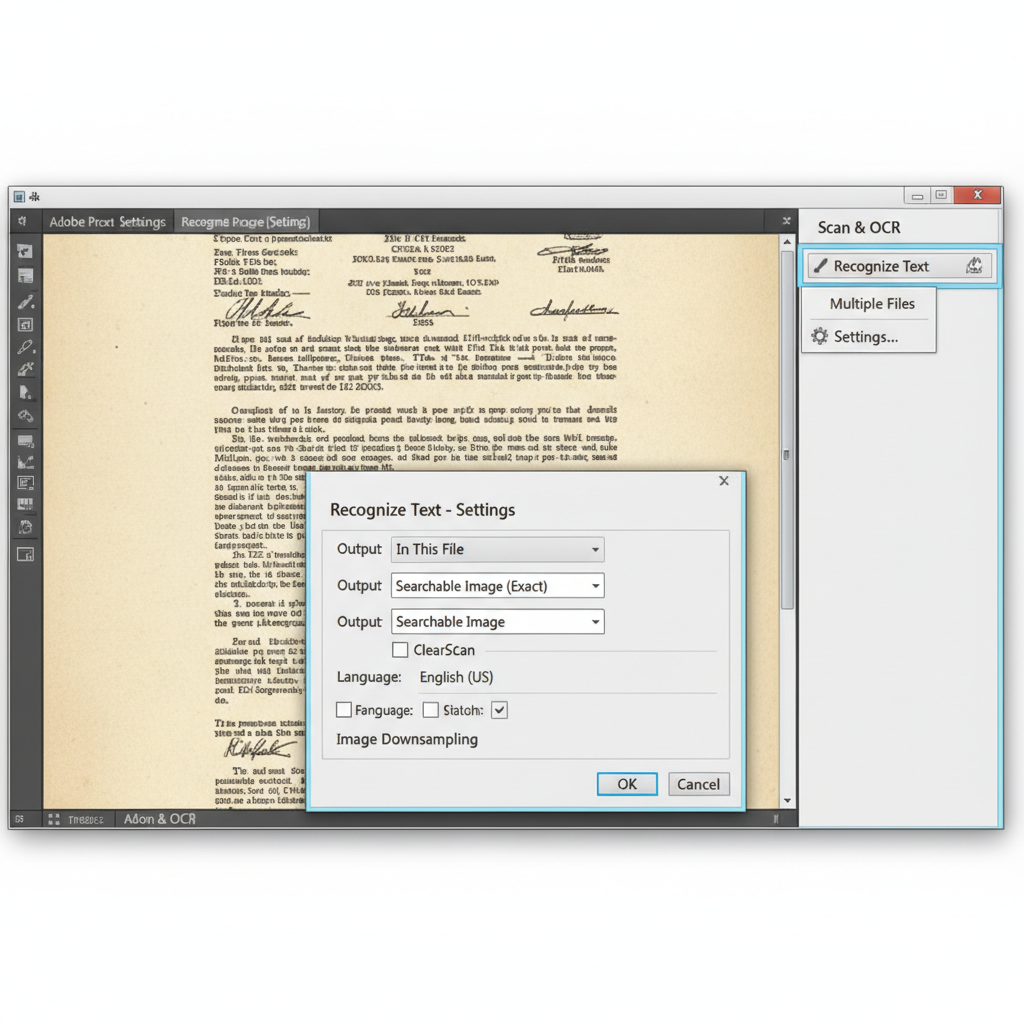
Changing the OCR style to "Searchable Image (Exact)" retains the original scanned image perfectly while adding an invisible layer of searchable text on top.
Acrobat offers three OCR processing styles: Searchable Image, Searchable Image (Exact), and Clear Scan. While Clear Scan attempts to replace original text with customized fonts to reduce file size, it can severely degrade the visual quality of complex or lower-quality scans.
Choosing Searchable Image (Exact) bypasses image alteration, keeping the visual presentation untouched. It solely builds an invisible text layer, making it ideal for legal documents, historical archives, or documents where visual fidelity is critical.
Open your scanned document in Adobe Acrobat DC. Navigate to the right-hand pane and select the 'Scan & OCR' tool. If it is not visible, find it under the 'Tools' tab at the top left.
In the Scan & OCR toolbar, click on 'Recognize Text' and then choose 'In This File' from the dropdown menu.
Click the 'Settings' gear icon. In the Settings dialog box, locate the 'Output' or 'OCR Style' dropdown menu and select 'Searchable Image (Exact)'.
Click 'OK' to save your settings, then click the 'Recognize Text' button to process the document. Your image will remain perfectly clear while becoming searchable.
Extract and Search Text Easily with WPS PDF OCR
WPS Office provides a highly accurate, built-in OCR feature that instantly recognizes text in scanned PDFs while preserving the original layout. It is a lightweight and efficient solution for managing all your document digitization needs.
- 1. Open Your Scanned PDF: Launch WPS Office and open your scanned PDF file using the WPS PDF viewer.
- 2. Launch the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button to open the text recognition panel.
- 3. Select Output Preferences: Choose whether you want to extract the text directly, convert it to a searchable PDF, or convert it to a Word document.
- 4. Process the Document: Confirm your document's language settings and click 'Start' or 'Extract' to complete the high-fidelity OCR process.
Frequently Asked Questions
Why does standard OCR ruin the formatting of my scanned document?
Standard OCR settings (like Acrobat's ClearScan) attempt to reconstruct the font and smooth out the background to reduce file size. If the original scan is dark, dirty, or uses a complex layout, the software may guess incorrectly, resulting in degraded formatting and warped text.
What is the best resolution for scanning documents before using OCR?
A minimum of 300 ppi (pixels per inch) is strongly recommended for standard text documents. If the document features very small fonts or complex details, scanning at 600 ppi will significantly improve OCR recognition accuracy.
Does file compression affect OCR text recognition?
Yes. High-compression formats (like heavily compressed JPEGs) introduce artifacts and blurriness around text edges, confusing the OCR engine. Saving your scans as lossless TIF files or low-compression JPEGs yields much better results.
Can OCR accurately recognize all letter combinations?
While highly accurate, OCR can struggle with certain kerning and letter combinations on low-quality scans. For example, a lowercase 'r' and 'i' placed closely together might be mistakenly recognized as an 'n'. High contrast and higher scanning resolutions minimize these errors.


