

How to Enable Automatic OCR for Scanned PDFs in Adobe Acrobat

Question details
The user needs to enable automatic Optical Character Recognition (OCR) to convert scanned PDF images into editable and selectable text.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
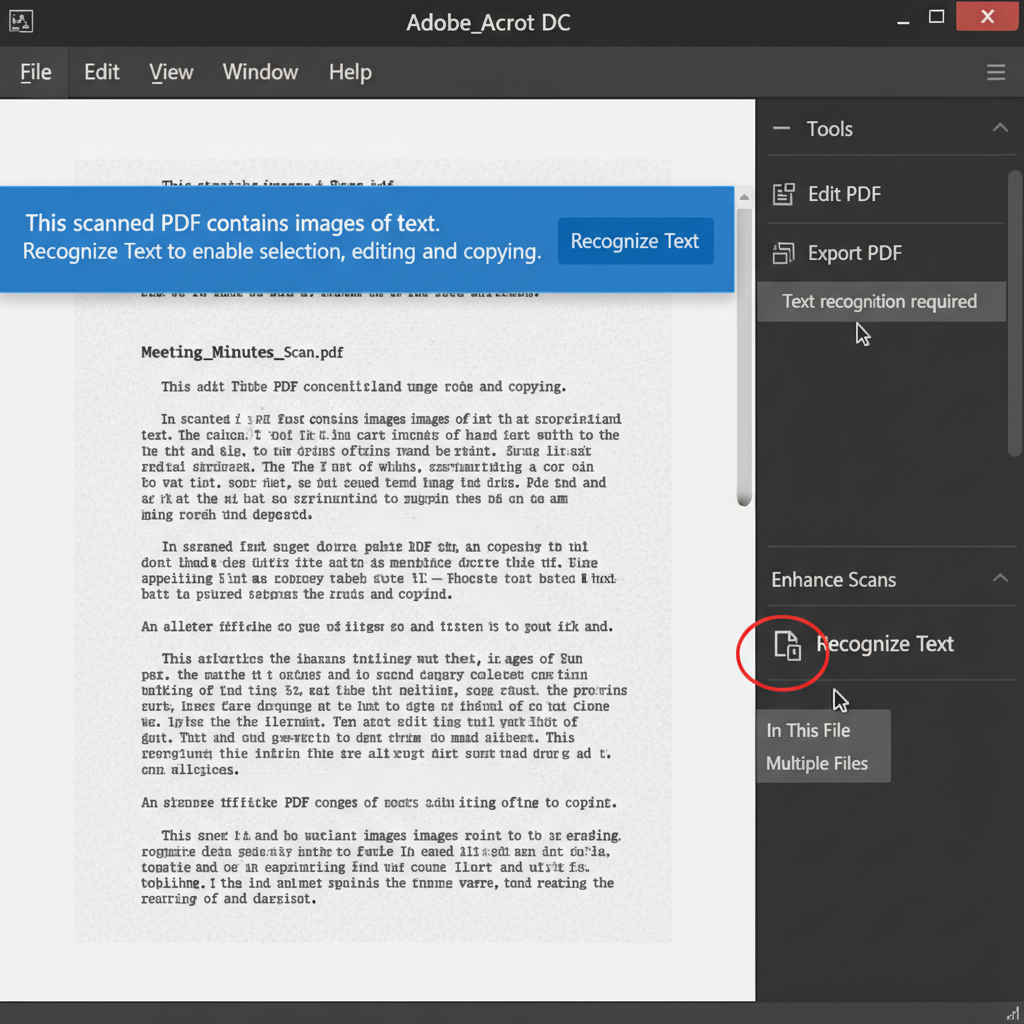
- Opening a scanned PDF document that behaves like a static image, preventing the user from editing, copying, or searching the text.
- Observed behavior
- The PDF opens without automatically running text recognition, requiring manual configuration of scanned document settings to make the text editable.
Ensure you are using a paid version of Adobe Acrobat (Standard or Pro), as the free Adobe Acrobat Reader does not support editing scanned PDFs or running OCR.
Use the Scanned Documents Settings to Run OCR
Access the built-in text recognition tools in Adobe Acrobat to manually trigger OCR and define your editing preferences.
When opening a scanned document for editing, Adobe Acrobat provides specific options to detect and convert image-based text into editable content. Configuring these settings ensures the text is recognized accurately in the correct language.
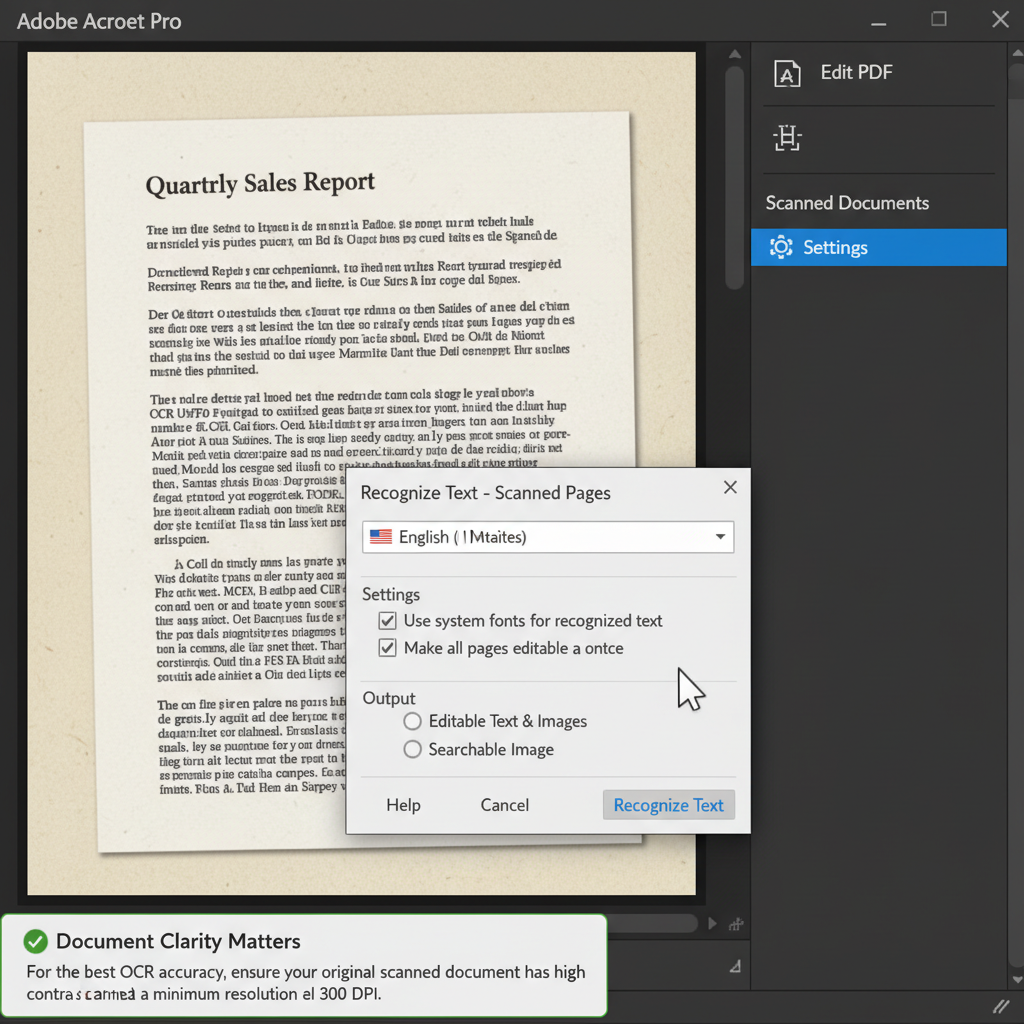
Launch Adobe Acrobat and open your scanned PDF. Click on the 'Edit PDF' tool in the right-hand pane to activate editing mode.
In the right pane, locate the 'Scanned Documents' section. Click on 'Settings' (often represented by a gear icon) to open the OCR configuration menu.
Select the correct OCR language that matches your document's text, choose whether to use system fonts, and opt to make all pages editable at once if needed.
Click on 'Recognize Text' to apply the OCR process. You can switch between 'text-to-image' and 'image-to-text' modes based on how you want the document to be edited.
Easily Extract and Edit Text from Scanned PDFs with WPS Office
WPS PDF offers a robust and user-friendly built-in OCR feature. If you want a lightweight and highly efficient way to convert scanned PDFs into editable text without complex settings, WPS Office provides an excellent solution.
- 1. Open the Scanned Document: Launch WPS Office, navigate to the PDF module, and open your scanned PDF file.
- 2. Select the OCR Tool: Click on the 'Tools' tab on the top navigation ribbon, then select 'OCR'.
- 3. Choose Extraction Mode: Select whether you want to extract the text directly to your clipboard or convert the entire scanned document into an editable Word file.
- 4. Review and Save: Wait a few seconds for the text recognition to complete, review the converted text, and save the new document to your local drive.

Frequently Asked Questions
Why is Adobe Acrobat not automatically recognizing text in my PDF?
If automatic OCR is disabled or failing, the document might be locked, low quality, or the 'Recognize Text' setting may be turned off in your preferences. You can manually trigger it by going to 'Edit PDF' and selecting 'Recognize Text' under the Scanned Documents pane.
What is the difference between text-to-image and image-to-text modes in Acrobat?
'Text-to-image' keeps the visual appearance of the original scan while making the text searchable and selectable underneath. 'Image-to-text' completely converts the scanned characters into digital, editable fonts, replacing the original image.
Can I perform OCR on a PDF using the free Adobe Reader?
No, the free Adobe Acrobat Reader does not include OCR capabilities. You need a paid subscription to Acrobat Standard or Pro, or you can use a capable alternative like WPS Office which offers PDF OCR tools.
How do I change the OCR language for better text recognition?
Before running OCR, open the 'Scanned Documents' section in the right pane, click on 'Settings', and choose the appropriate language from the OCR language dropdown menu. This helps the engine correctly identify specific characters and accents.


