



How to Change Text Recognition (OCR) Language in Adobe Acrobat
Question details
The user wants to know how to adjust the language settings used for text recognition (OCR) when converting a scanned PDF or image into editable text.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Performing Optical Character Recognition (OCR) on a scanned document where the default language does not match the document's text.
- Observed behavior
- The user needs to locate and modify the OCR language setting to ensure accurate text conversion but does not know where to find the option in the software or online service.
Verify that your document is a scanned image or non-editable PDF, and ensure you are using a version of Acrobat (such as Acrobat Pro) that includes full OCR functionality.
Change OCR Language in Adobe Acrobat Desktop App
Use the Scan & OCR tool in the desktop version of Adobe Acrobat to manually select the correct document language before running text recognition.
Adobe Acrobat relies on accurate language settings to correctly interpret characters during OCR. Setting the language to match your document's primary text will prevent garbled output and recognition errors.
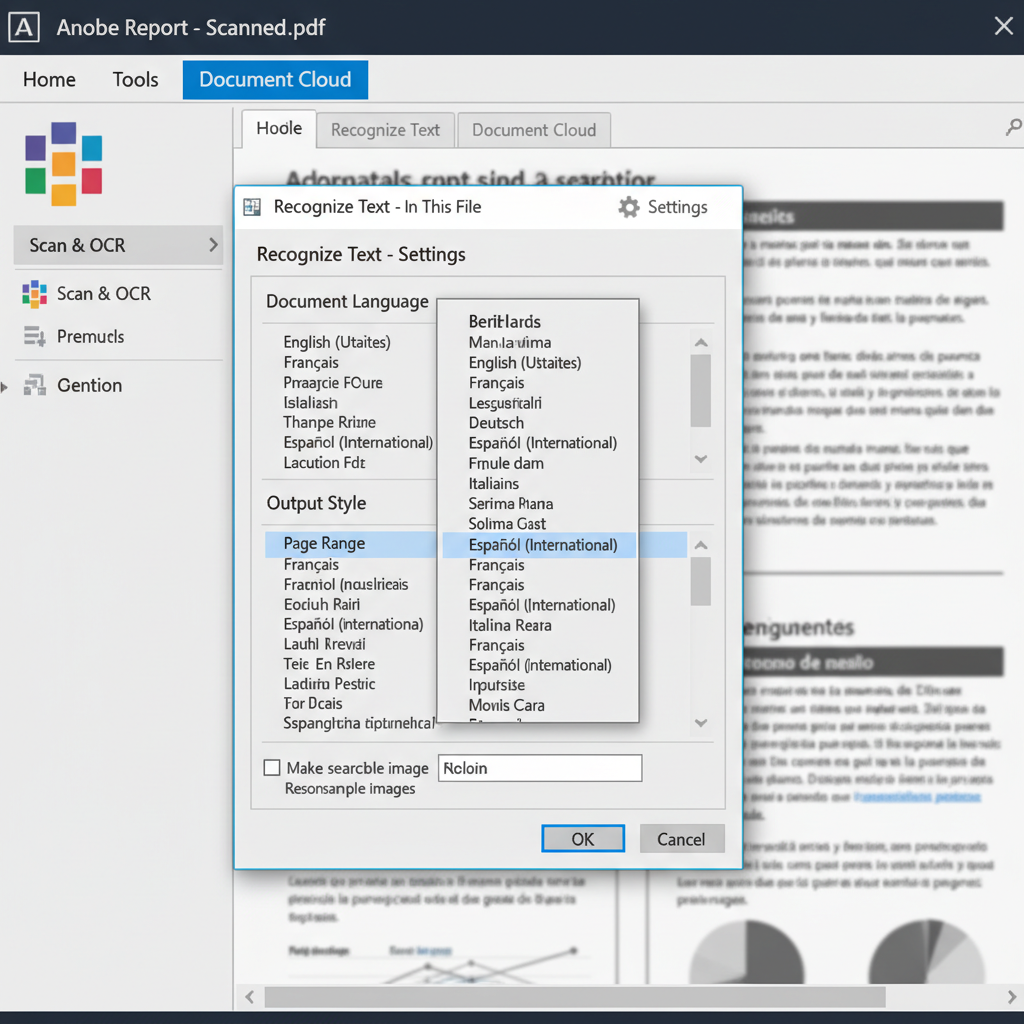
Launch Adobe Acrobat and open your scanned PDF. Navigate to the 'Tools' tab and select 'Scan & OCR'.
In the secondary toolbar, click on 'Recognize Text' and then select 'In This File' from the drop-down menu.
Click the 'Settings' gear icon that appears next to the Recognize Text options to open the configuration window.
Under the 'Document Language' section, click the drop-down menu and choose the language that matches your document's text. Click 'OK' to save.
Click the 'Recognize Text' button to process the document using the newly selected language.
Change OCR Language Settings for Adobe Online Services
For users utilizing Adobe's web-based PDF services, language recognition is often handled automatically based on browser locale or account settings.
Extract and Edit Text Easily with WPS PDF OCR
WPS Office includes a robust PDF editor equipped with advanced OCR (Optical Character Recognition) technology. You can easily extract text from scanned documents and explicitly select your preferred recognition language for highly accurate results.
- 1. Open your PDF: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Choose extraction settings: In the OCR dialog box, choose your desired output format, such as Extract Text or Convert to Word.
- 4. Select the recognition language: Click the 'Language' option to select the correct language matching your document's text, then click 'Start' to process the file.
- 5. Save or edit: Once the OCR process is complete, you can freely edit, save, or export your newly converted text document.
Frequently Asked Questions
Why is my PDF text recognition producing gibberish or incorrect symbols?
This usually happens when the OCR engine's selected language does not match the actual language printed in the scanned document. Ensuring the correct language is selected in your OCR settings before recognizing the text will significantly improve accuracy.
Can I recognize multiple languages at once in Acrobat OCR?
Standard OCR tools are generally optimized to process a single primary language per recognition pass. If your document contains multiple languages, it is recommended to select the language that appears most frequently in the text.
Is OCR text recognition free to use in Adobe Acrobat?
OCR capabilities are part of the premium features included in paid Adobe Acrobat Pro or Standard subscriptions. Free users utilizing Adobe Acrobat Reader can view and comment on PDFs but cannot perform OCR text extraction or conversion.


