



How to Convert Scanned Documents to Searchable PDFs with OCR
Question details
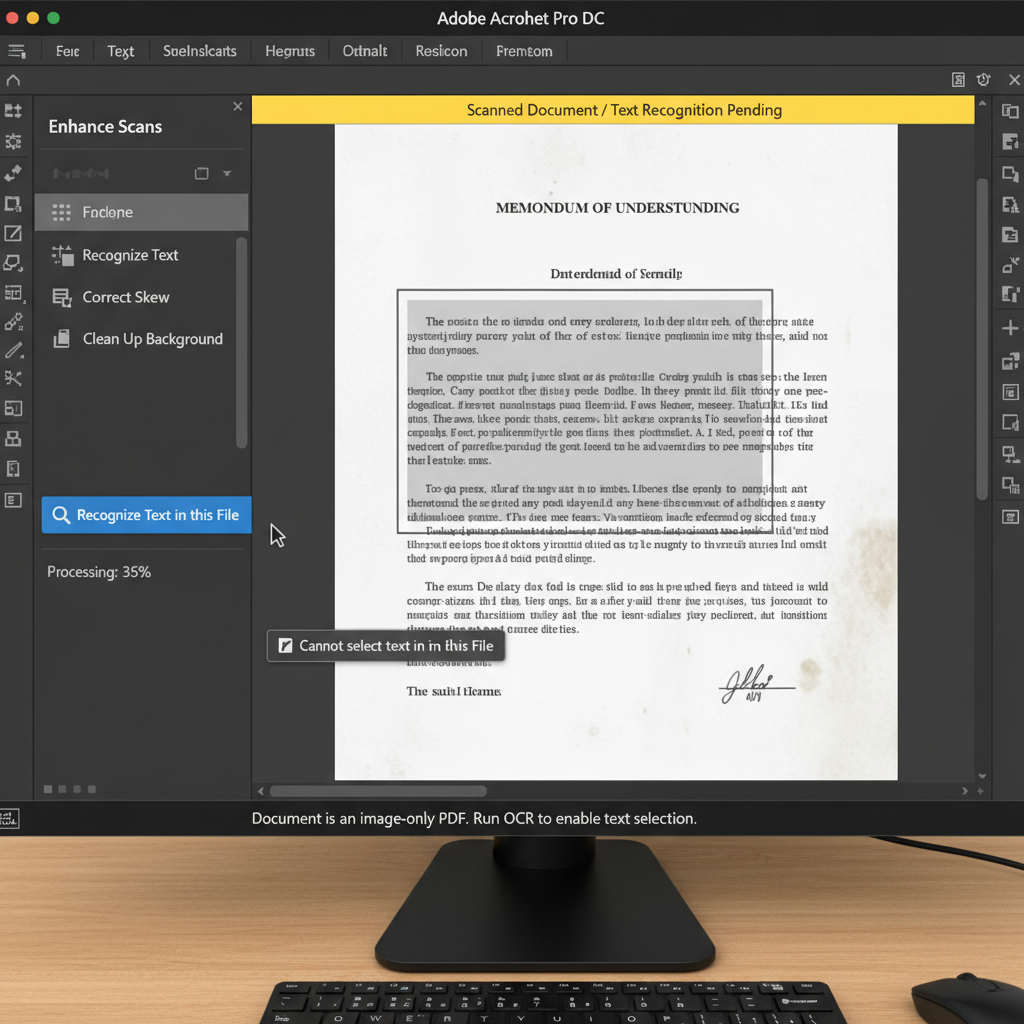
The user needs to convert a scanned image or document into a searchable and selectable PDF using Optical Character Recognition (OCR).
- Product
- Adobe Acrobat DC
- Device & OS
- not provided
- Scenario
- Working with scanned documents where the text needs to be extracted, searched, or selected for editing and sharing.
- Observed behavior
- The scanned document behaves as a flat image, meaning text cannot be highlighted, searched, or copied until OCR is applied.
Ensure your scanned document is clear and has good contrast; high-quality, straight scans yield the most accurate OCR text recognition results.
Use Adobe Acrobat DC to Run OCR
Adobe Acrobat provides built-in OCR capabilities to recognize and extract text in scanned files.
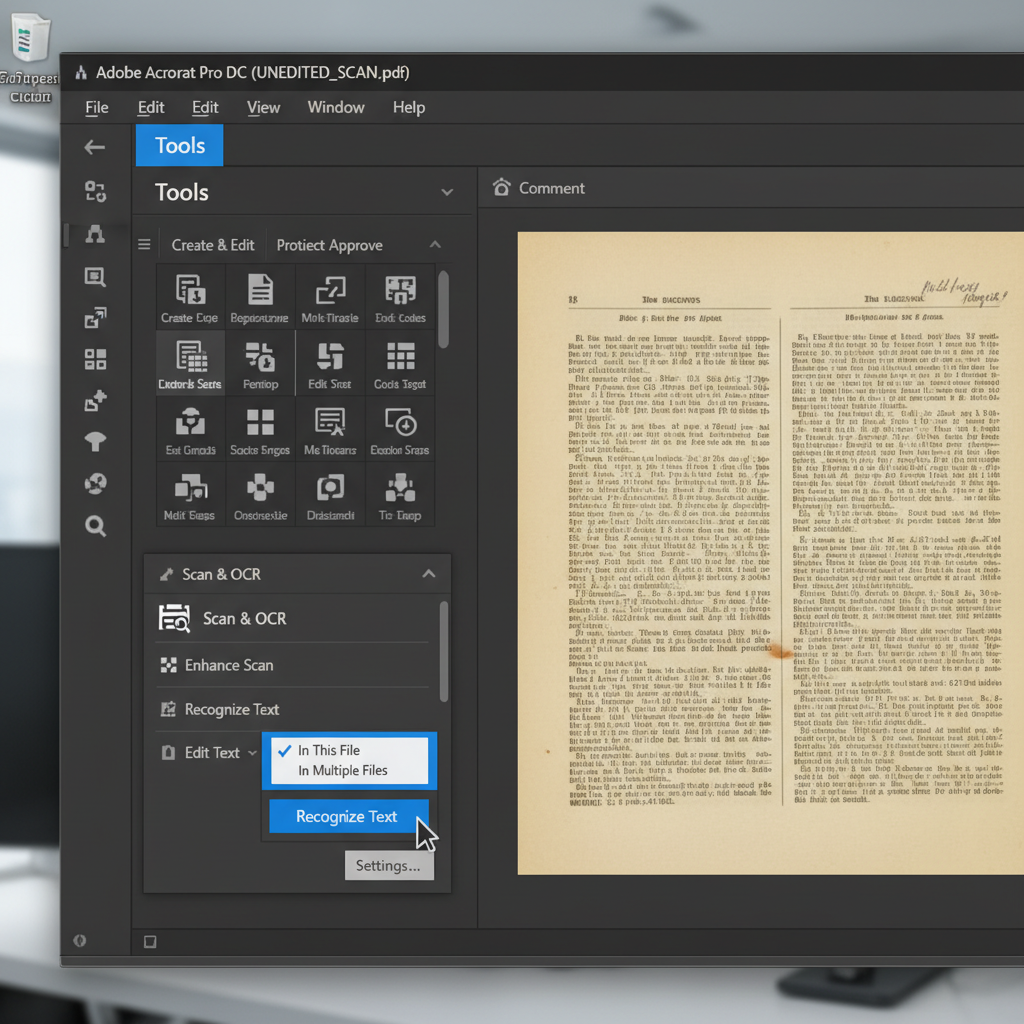
By utilizing the 'Scan & OCR' tool in Adobe Acrobat DC, you can make the text in flat images fully searchable and selectable. Adobe does not specify a fixed file-size limit for this process, but a stable internet connection is recommended for large files.
Launch Adobe Acrobat DC and open the scanned PDF file that you want to convert.
Navigate to the 'Tools' menu at the top of the window and select 'Scan & OCR'.
Click on 'Recognize Text' in the secondary toolbar, and then choose 'In This File'.
Click the 'Recognize Text' button to start the OCR process. Once complete, search for a word to verify success, then save your newly searchable PDF.
Convert Scanned PDFs to Searchable Text Easily with WPS Office
WPS Office features a robust PDF editor equipped with highly accurate OCR technology. You can quickly turn scanned images and documents into searchable, editable text formats without relying on heavy or expensive software.
- 1. Open WPS PDF: Launch WPS Office and open your scanned PDF document in the PDF tab.
- 2. Locate the OCR feature: Click on the 'Tools' tab in the top ribbon and select the 'OCR' button.
- 3. Configure OCR settings: Choose your document's language and select whether you want to extract the text to a document or keep it as a searchable PDF.
- 4. Start conversion: Click 'Confirm' or 'Start' to begin the recognition process, then save your newly searchable file once it finishes.
Frequently Asked Questions
Why is the OCR text recognition inaccurate on my scanned PDF?
Inaccurate OCR is usually caused by low-resolution scans, blurry text, handwriting, or poor background contrast. Scanning your documents clearly at 300 DPI or higher yields the most accurate results.
Is there a page limit for converting scanned PDFs using OCR?
While most premium PDF tools like Adobe Acrobat or WPS Office do not have a strict fixed page limit, very large documents will take longer to process and may consume significant system memory.
Can I edit the text after applying OCR to a scanned PDF?
Yes. If you choose to export the OCR results to a Word document or an editable PDF format, you can freely modify, delete, or add new text just like a standard document.
Does OCR support multiple languages in a single document?
Advanced OCR tools allow you to select multiple languages before starting the scan. Ensure you check the appropriate language settings in your software to accurately recognize all text present in the document.


