

How to Convert TIFF or Scanned PDF to Searchable OCR PDF

Question details
The user needs to convert a TIFF image file or a scanned (image-based) PDF into a searchable PDF where the text can be selected, searched, and copied.
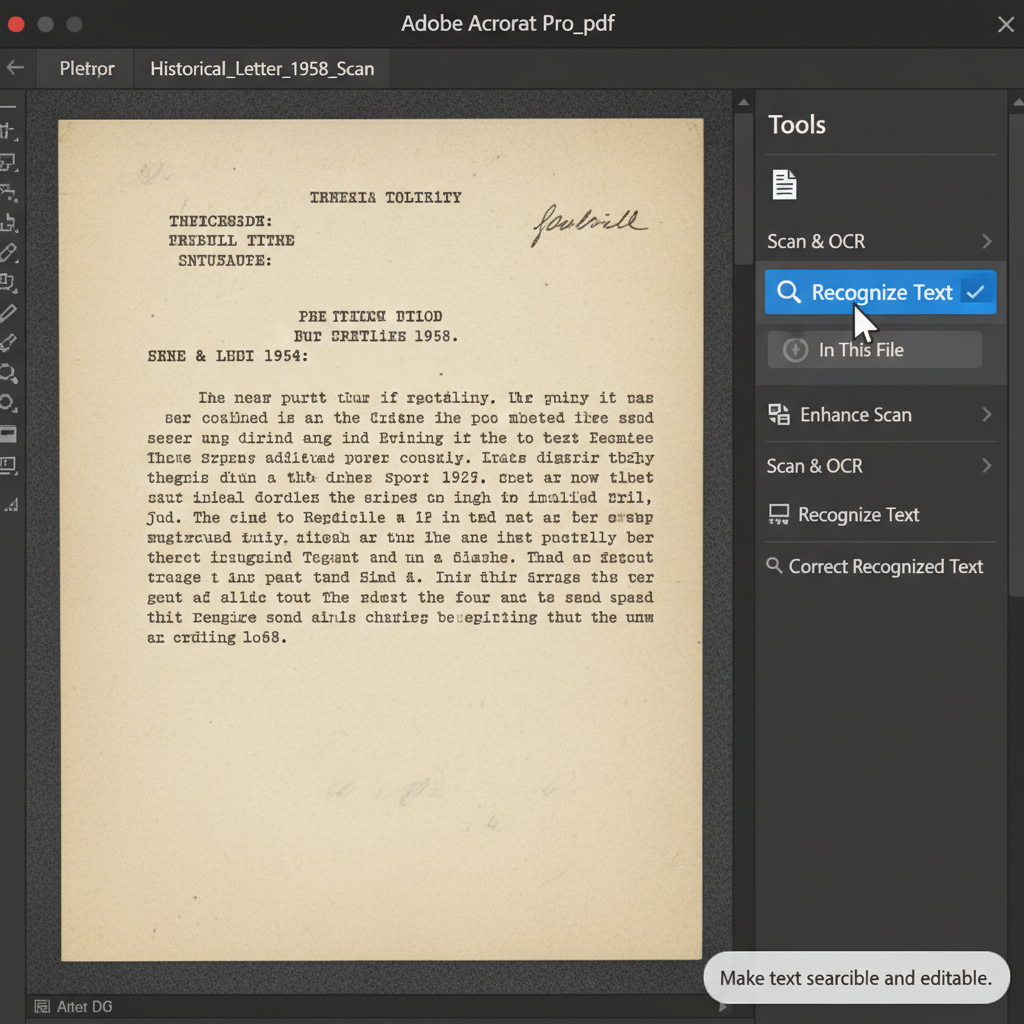
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Archiving documents, extracting text, or making image-based documents searchable for digital workflows.
- Observed behavior
- The user has an image-based file (TIFF or scanned PDF) that currently does not allow text selection or searching, requiring OCR technology to recognize the text.
Ensure that your scanned document or TIFF image is clear and has sufficient resolution (typically 300 DPI or higher) for the Optical Character Recognition (OCR) engine to accurately detect and convert the text.
Use Adobe Acrobat's Scan & OCR Tool
Use the built-in OCR feature in Adobe Acrobat to recognize text in your scanned PDFs or TIFF files.
By processing your scanned documents or TIFF images through Adobe Acrobat's OCR tool, a hidden layer of recognized text is overlaid onto the original image, making the entire document selectable and searchable.
Open Adobe Acrobat. If you are starting with a TIFF file, go to Tools > Create PDF, select your TIFF file, and generate a standard PDF. If starting with a scanned PDF, simply open the file in Acrobat.
Navigate to the right-hand pane or the Tools menu and select the 'Scan & OCR' option.
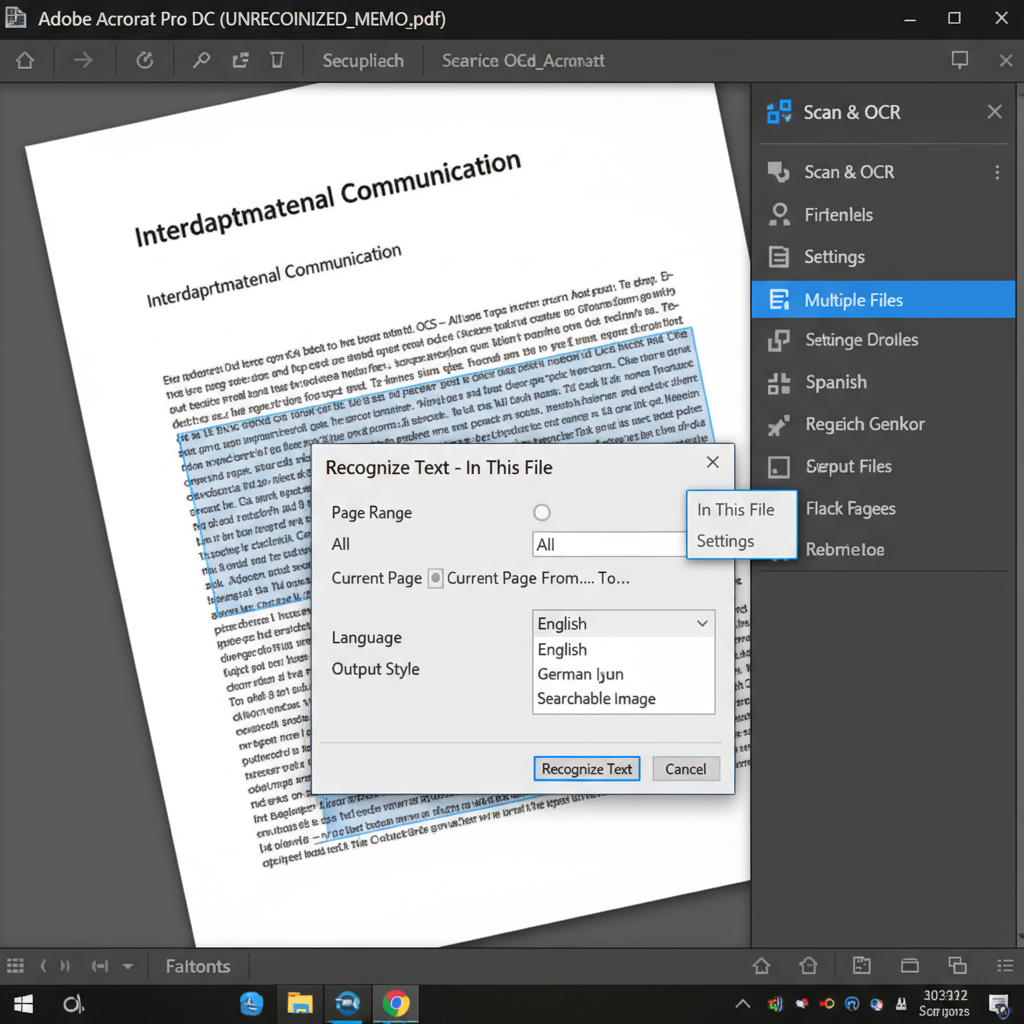
Click on 'Recognize Text' and choose 'In This File' from the dropdown. Select the correct language of the document and specify the page range you wish to process.
Click the 'Recognize Text' button to start the process. Once the text has been successfully recognized, save your newly searchable PDF file to your local drive.
Make Scanned PDFs Searchable with WPS PDF
WPS Office provides a powerful, built-in OCR tool within its PDF editor, allowing you to quickly extract text from scanned documents and images or convert them into fully searchable and editable PDFs.
- 1. Open the File in WPS PDF: Launch WPS Office and open your scanned PDF or converted image file.
- 2. Launch the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Select Recognition Mode: Choose whether you want to extract the text to a plain document or convert the current file into a 'Searchable PDF'.
- 4. Process and Save: Confirm your language settings, click 'Recognize' to complete the text extraction, and save your searchable file.

Frequently Asked Questions
What is a searchable PDF?
A searchable PDF is a document that contains two layers: an image layer of the original scanned document and a hidden text layer created by OCR technology, allowing you to highlight, search, and copy the text as if it were a standard text document.
Why is the OCR output inaccurate or missing text?
OCR accuracy heavily depends on the quality of the original image. Low-resolution scans, blurry text, handwriting, or complex document backgrounds can result in poor recognition. For best results, ensure your source file is scanned clearly at 300 DPI or higher.
Can I convert a TIFF directly to a searchable PDF without converting it first?
Most professional PDF editors require you to first convert or import the TIFF image into a standard PDF format before applying the OCR tool to generate the searchable text layer.
Is it possible to edit the text after running OCR?
Yes, if you use a full-featured PDF editor like Adobe Acrobat or WPS PDF, you can switch from a searchable PDF mode to an editable PDF mode to correct text mistakes or adjust formatting directly within the document.


