

How to Create a Searchable Two-Layer PDF from Scanned Images Programmatically
Question details
The user wants to automate the process of converting scanned images or non-searchable PDFs into searchable two-layer PDFs (visible image layer with a hidden OCR text layer) using programmatic methods rather than manual GUI software.
- Product
- Device & OS
- not provided
- Scenario
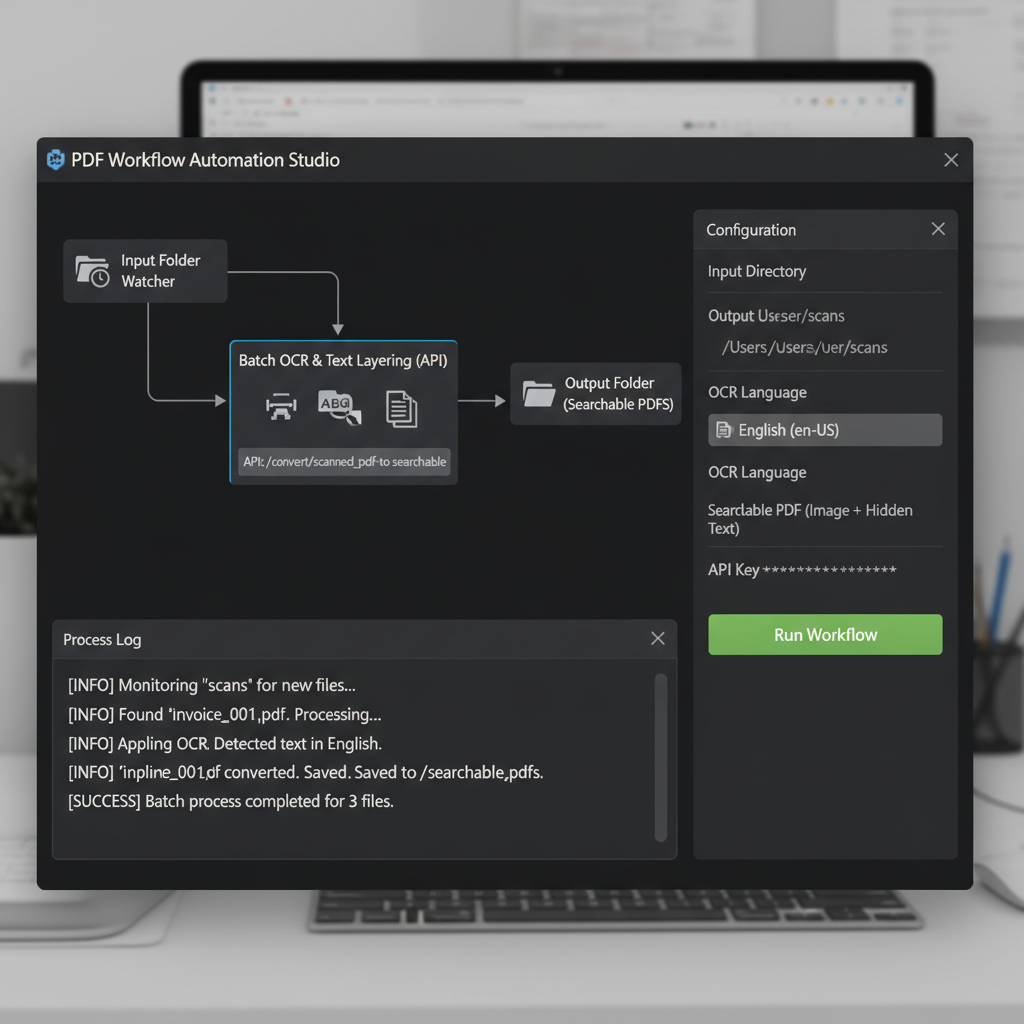
- Developing an automated workflow or script to batch process scanned documents into searchable PDFs with selectable text accurately overlaying the original image.
- Observed behavior
- Seeking a programmatic solution or API to apply Optical Character Recognition (OCR) and generate a hidden text layer over page images, mimicking the interactive functionality of Adobe Acrobat.
Before implementing a programmatic OCR solution, ensure you have registered for the necessary API credentials (such as Adobe PDF Services) or have installed required open-source libraries like Tesseract OCR on your development environment.
Automate PDF OCR Using Adobe PDF Services API
Use a robust, commercial API designed specifically for PDF manipulation to accurately overlay OCR text on scanned images.
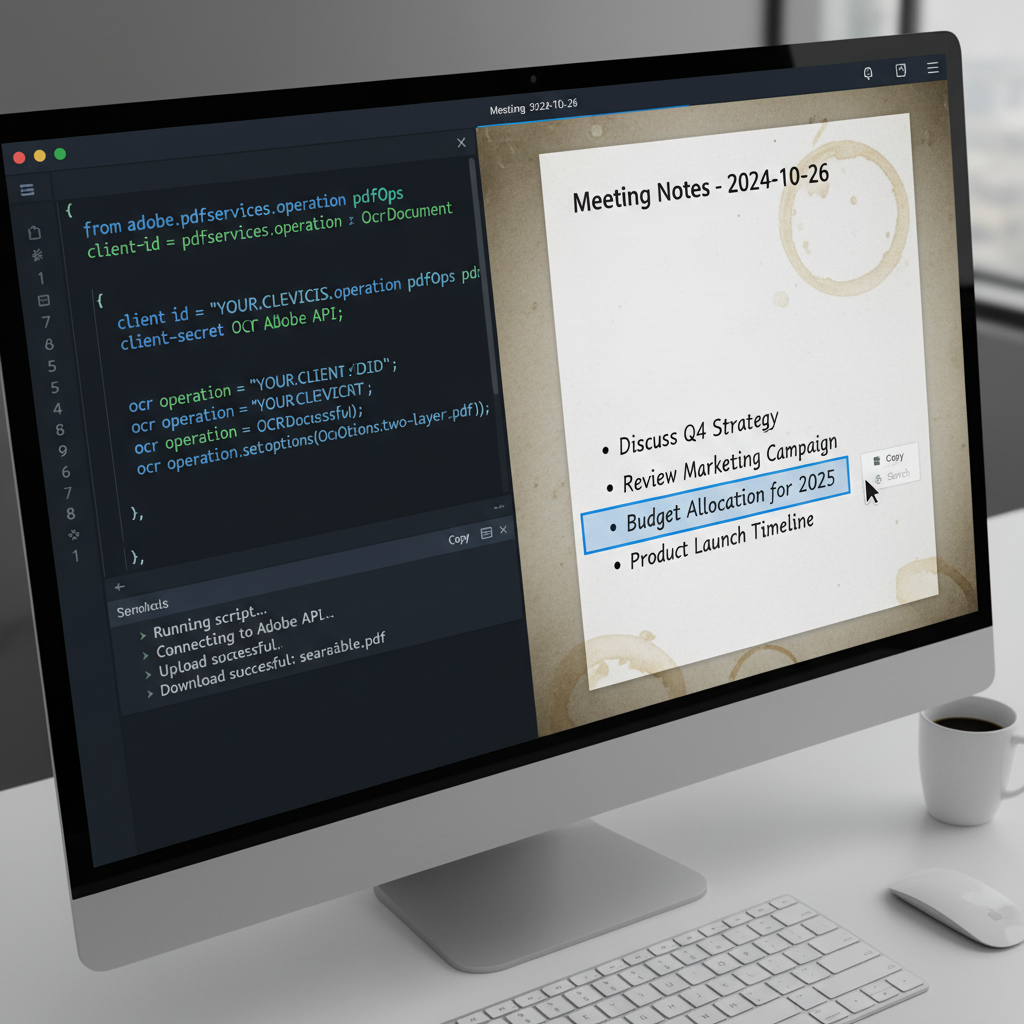
Adobe provides cloud-based APIs capable of converting scanned documents into searchable PDFs automatically. This approach guarantees high-quality OCR and creates a standard two-layer PDF where the original image remains intact while the text becomes selectable and searchable.
Register for Adobe PDF Services API on the Adobe Developer Console to obtain your Client ID and Client Secret.
Install the corresponding Adobe PDF Services SDK for your programming language, such as Node.js, Python, or Java, using your package manager.
Write a script that authenticates using your credentials, creates an execution context, and calls the OCR endpoint by passing your scanned PDF or image.
Set the OCR options in your code to ensure the output creates a hidden text layer directly over the source image (two-layer PDF format).
Run the API call, download the resulting searchable PDF to your local directory, and open it to validate that the text extraction and overlay are correct.
Build a Custom OCR Script using Python and Tesseract
A free, open-source alternative for developers comfortable with Python and managing local OCR engines.
Create Searchable PDFs Instantly with WPS Office
While programmatic solutions are great for automation, building and maintaining OCR scripts can be complex and time-consuming. If you simply need to convert scanned documents or images into fully searchable two-layer PDFs without writing code, WPS Office offers a built-in, highly accurate OCR tool that works directly on your desktop.
- 1. Open your scanned document: Launch WPS Office and open your scanned image or non-searchable PDF using the built-in WPS PDF editor.
- 2. Activate the OCR feature: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button to initialize the text recognition tool.
- 3. Convert to a searchable PDF: Select 'Searchable PDF' as your output format and click 'Convert' to instantly generate a two-layer document where text can be copied and searched.
Frequently Asked Questions
What is a two-layer PDF?
A two-layer PDF consists of the original scanned image as the visible background layer, and a transparent, hidden text layer created by OCR on top of it. This allows the document to look exactly like the original scan while enabling users to search, highlight, and copy text.
Can I use Adobe Acrobat to automate OCR?
Adobe Acrobat Pro includes an Action Wizard that allows batch processing of OCR tasks interactively on your desktop. However, for true server-side or headless programmatic automation, you cannot use the Acrobat desktop application; you must use an API like Adobe PDF Services.
Why is my OCR text not aligning with the original image?
Misalignment occurs when the OCR engine's output coordinates do not perfectly match the source image scaling or resolution. Using dedicated PDF APIs or ensuring your OCR library maps bounding box coordinates accurately is necessary to fix this issue.
Are there free programmatic OCR solutions available?
Yes, open-source engines like Tesseract OCR can generate searchable PDFs programmatically for free. However, they may require more manual configuration, dependency management, and coding compared to commercial plug-and-play APIs.


