

How to Make PDFs Searchable with OCR in Adobe Acrobat
Question details
The user needs to know how to convert a scanned, image-only PDF into a searchable document using OCR features.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
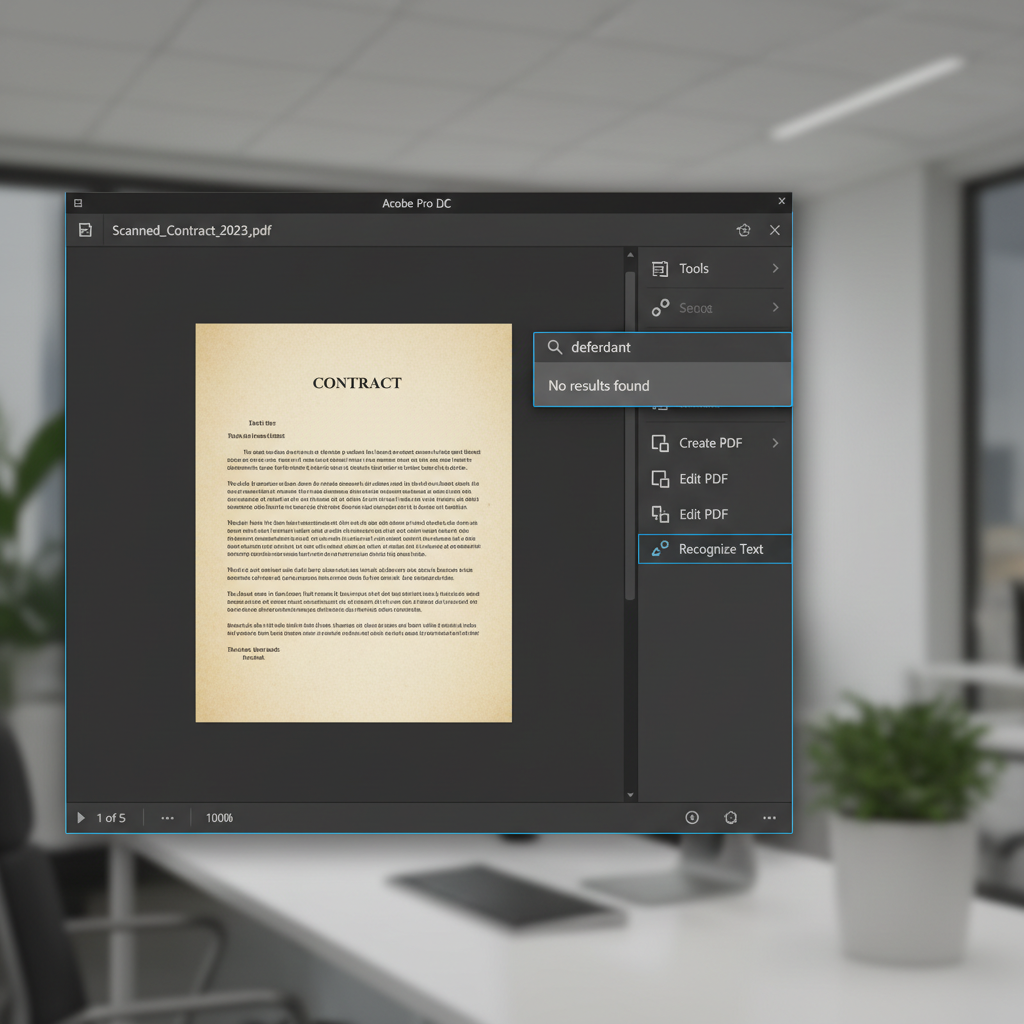
- Attempting to search for specific text within a scanned PDF document.
- Observed behavior
- The search function yields no results because the PDF is treated as a flat image and lacks a readable text layer.
Ensure you have Adobe Acrobat Standard or Pro installed, as the free Adobe Acrobat Reader does not include the built-in OCR (Optical Character Recognition) tool required for this process.
Use the Scan & OCR Tool in Adobe Acrobat
Run Acrobat's built-in Text Recognition feature to analyze the image and generate a readable text layer.
By default, scanned documents are saved as image files without a readable text layer. Saving a file as a PDF does not automatically recognize text. To make the document searchable, you must process the file using Optical Character Recognition (OCR).
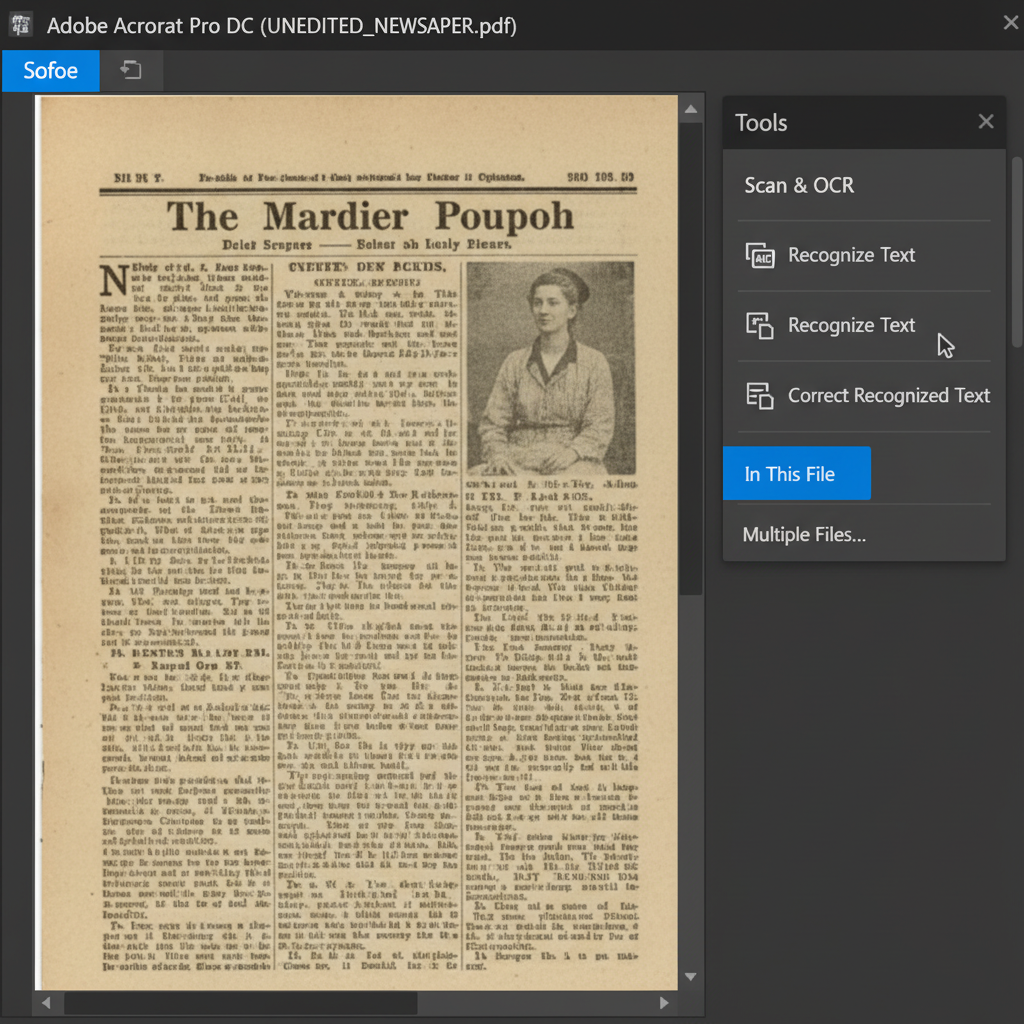
Open your image-only PDF in Adobe Acrobat. Go to the 'Tools' pane on the right side and select 'Scan & OCR' (older versions may label this as 'Enhance Scans').
In the secondary toolbar, click on 'Recognize Text' and select 'In This File' from the drop-down menu.
Choose the correct document language and click the 'Recognize Text' button. Acrobat will scan the pages and convert the images into searchable text.
Once the OCR process is complete, go to 'File' > 'Save' to overwrite the document with the newly added text layer, or select 'Save As' to create a new searchable PDF file.
Make PDFs Searchable Easily with WPS Office
WPS Office provides a highly accurate, built-in OCR tool to instantly convert scanned PDFs and images into fully editable and searchable documents.
- 1. Open your PDF: Launch WPS Office and open your scanned or image-based PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Select Output Format: Choose your desired extraction method, such as 'Extract Text' or convert the document into a 'Searchable PDF'.
- 4. Process and Save: Click 'Confirm' to let WPS Office process the text recognition, then save your newly searchable file.
Frequently Asked Questions
Why can't I search text in my PDF?
If your PDF was created by scanning a physical document, it is essentially a flat image of the page. Without a text layer created via an OCR (Optical Character Recognition) process, search functions cannot detect the words.
Does using 'Save As' make a PDF searchable?
No, simply saving or renaming an image-based PDF does not make it searchable. You must actively run an OCR or Text Recognition process to analyze the image and generate a searchable text layer.
Can I batch process multiple PDFs for text recognition?
Yes, in Adobe Acrobat Pro, you can use the Action Wizard tool to set up a batch process that automatically runs text recognition on multiple scanned PDFs located in a specific folder.
Is OCR available in the free Adobe Acrobat Reader?
No, the OCR feature is a premium tool available only in paid versions like Adobe Acrobat Standard or Pro. However, feature-rich alternatives like WPS Office also offer robust PDF OCR capabilities.


