

How to Make a PDF Searchable with OCR in Adobe Acrobat
Question details
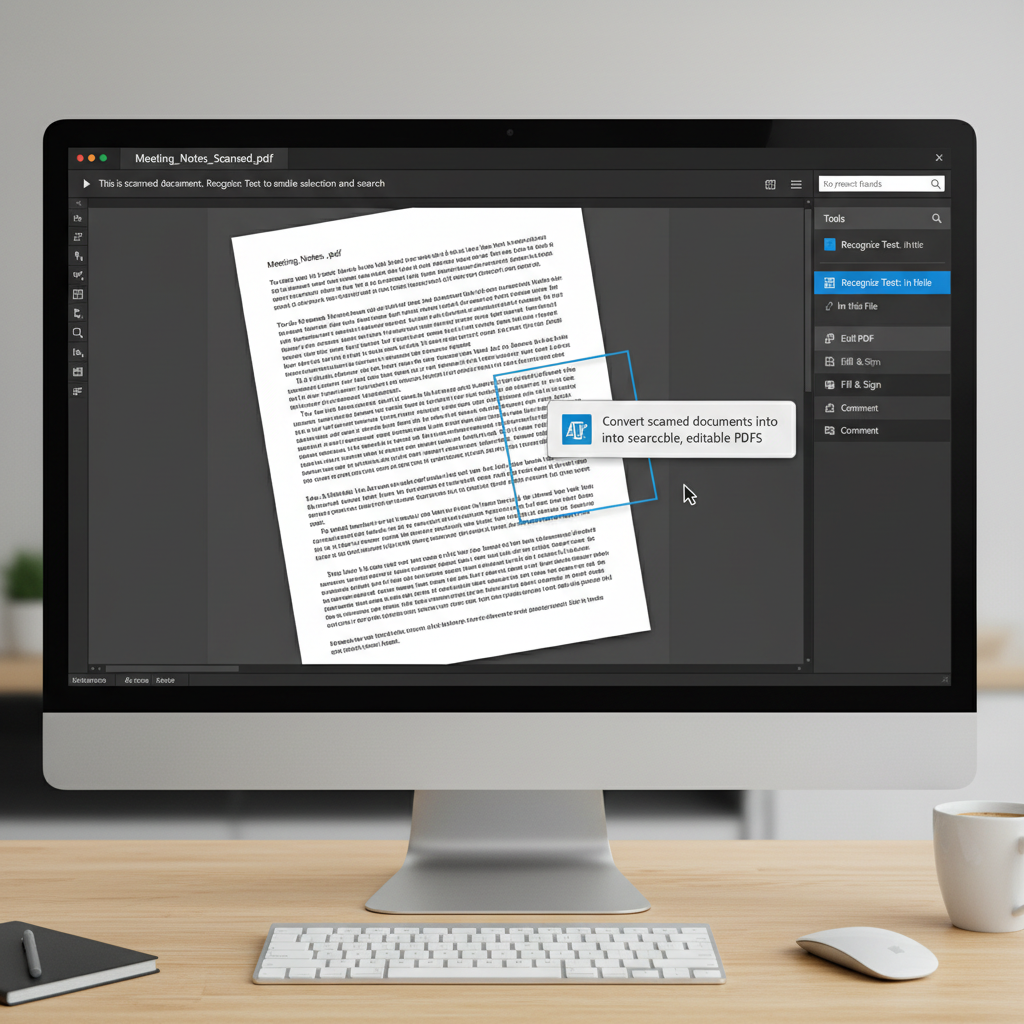
The user needs to convert a scanned, image-based PDF into a searchable document using Optical Character Recognition (OCR) in Adobe Acrobat without exporting it to Microsoft Word.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Working with scanned or image-based PDF documents that have skewed pages and lack selectable or searchable text.
- Observed behavior
- The document behaves like an image, preventing the user from highlighting or searching for specific words, and pages appear skewed from the scanning process.
Ensure your scanned PDF document is clear and readable, as high-quality, high-contrast scans yield the most accurate Optical Character Recognition (OCR) results.
Use Acrobat's Text Recognition Tool
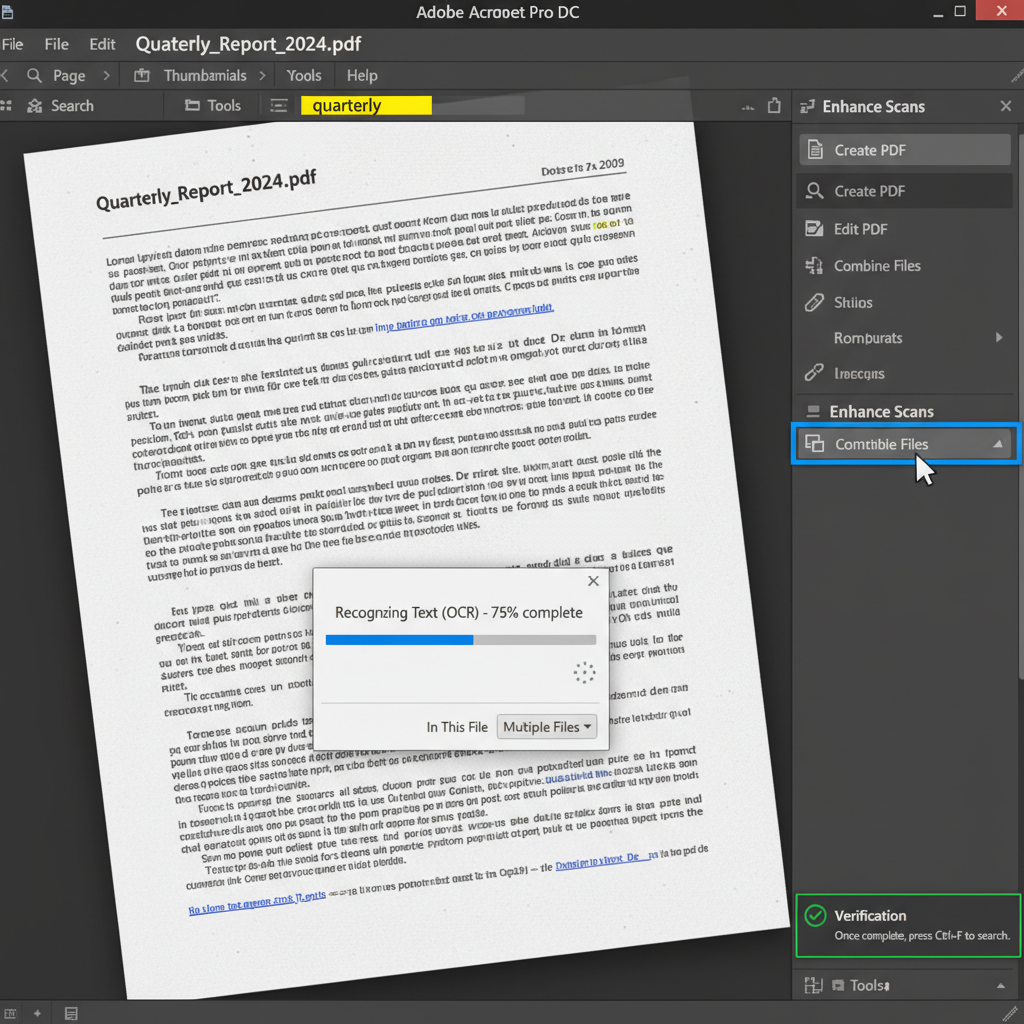
This is the standard, built-in method to apply OCR in Acrobat, which automatically creates a hidden searchable text layer and corrects skewed pages.
Adobe Acrobat includes a powerful built-in OCR feature that scans the image-based text in your document and matches it to system fonts. This process allows you to search, highlight, and copy text while keeping the original layout completely intact.
Launch Adobe Acrobat and open the specific scanned PDF file you wish to process.
Go to the right-hand pane or the top menu, select 'Tools', and then click on 'Text Recognition'.
Select the 'In This File' option. Acrobat will automatically begin analyzing the document, straightening skewed pages, and applying a searchable text layer to the images.
Make Your Scanned PDFs Searchable with WPS Office
If you don't have Adobe Acrobat, WPS PDF provides an excellent, highly accurate built-in OCR tool. It quickly recognizes text from scanned pages, straightening them out and making them fully searchable and editable while seamlessly preserving the original document's layout.
- 1. Open your PDF in WPS: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR feature: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Select your extraction mode: Choose the option to make the document searchable or to extract the text directly into an editable format.
- 4. Start the recognition process: Confirm your document's language settings and click 'Start' to process the PDF.

Frequently Asked Questions
Why is my PDF still not searchable after running OCR?
This usually happens if the original scan resolution was too low (below 300 DPI), the text was handwritten, or the document contained complex, dark backgrounds that prevented the OCR engine from correctly distinguishing the letters.
Can I edit the text after running OCR on a scanned PDF?
Yes, if you select the OCR option that converts the file into an editable document, you can modify the text directly. However, if you simply chose to make the PDF 'searchable', the text operates as a hidden layer behind the original image, allowing selection but not direct editing.
How do I ensure the OCR recognizes specific languages?
Before initiating the text recognition process, check the OCR settings or 'Primary OCR Language' dropdown in your PDF editor. Select the language that matches the contents of your document to guarantee the highest accuracy, especially for documents containing special characters or accents.


