

How to Recognize and Edit Text on Image-Based PDF Pages
Question details
The user needs to edit or select text within a PDF that is composed of scanned images rather than selectable text elements.
- Product
- Adobe Acrobat Pro DC
- Device & OS
- not provided
- Scenario
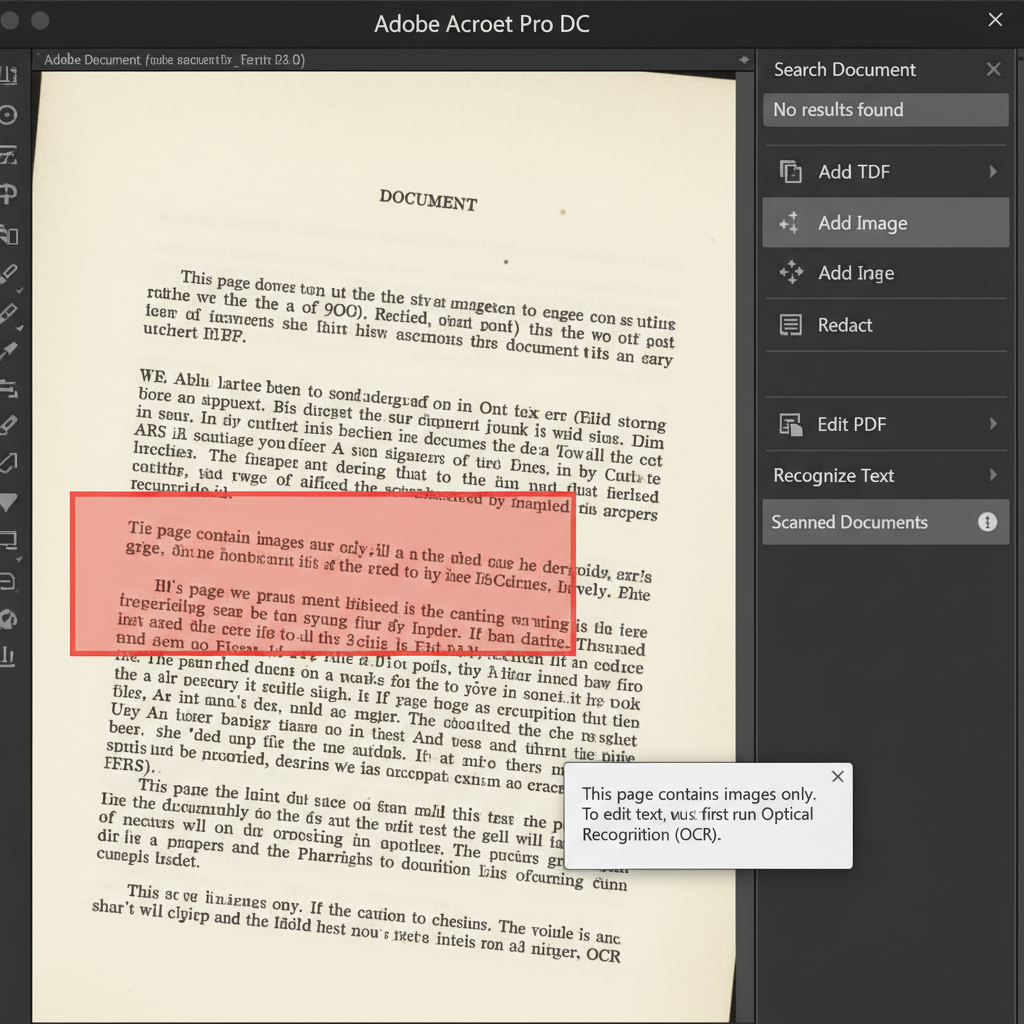
- Attempting to edit text, search content, or use the Recognize Text tool on a PDF file created from scanned documents.
- Observed behavior
- The text cannot be selected or edited because the PDF consists only of image layers, and the text recognition option may appear disabled or unavailable.
Ensure that your PDF file is not secured with editing restrictions, as permissions limitations will disable text recognition and editing tools.
Use Scan & OCR in Adobe Acrobat Pro DC
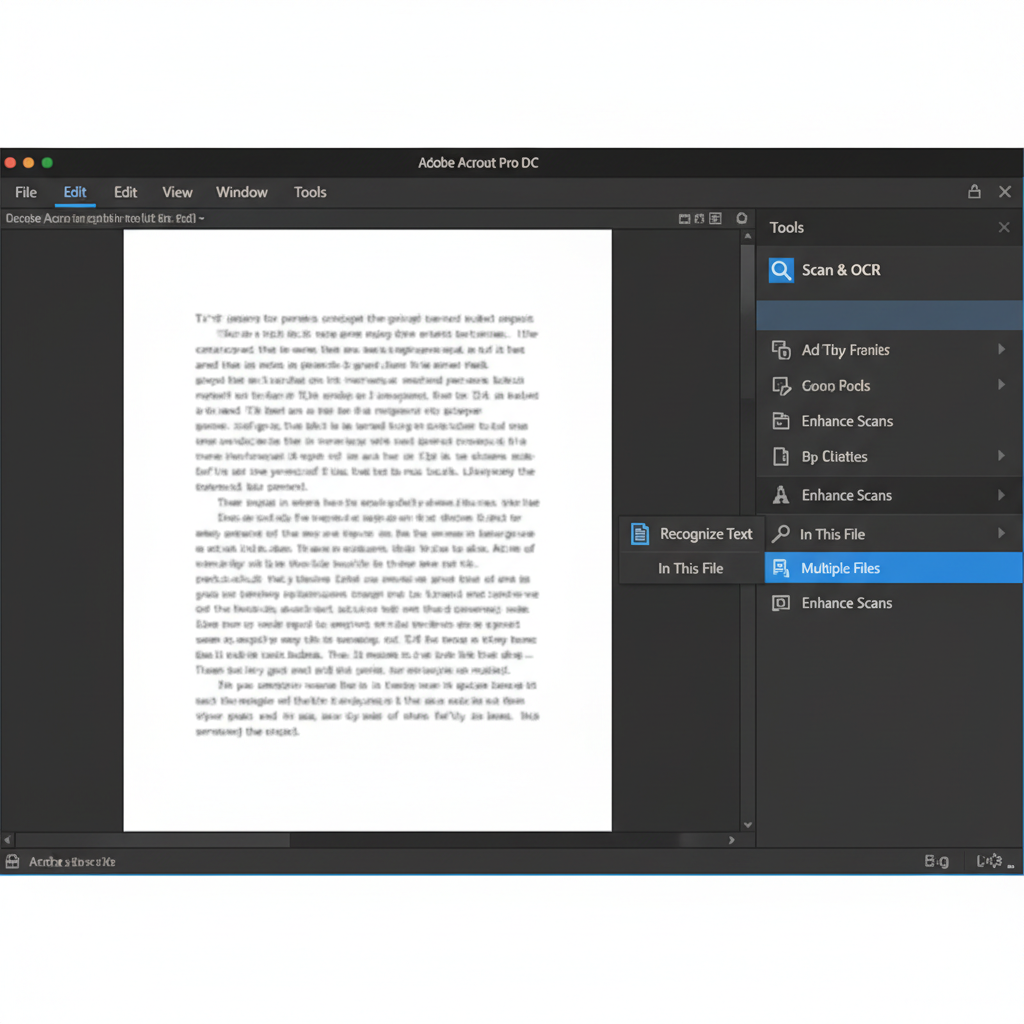
Run Adobe Acrobat's built-in OCR (Optical Character Recognition) tool to convert scanned images into selectable and editable text.
To edit an image-based PDF, you must first convert the image into text using OCR. This feature scans the shapes in the image and translates them into searchable text characters. Note that the accuracy of the conversion heavily depends on the clarity of the original scanned image.
Launch Adobe Acrobat Pro DC on your computer and open the image-based PDF document you want to edit.
Navigate to the right-hand tools pane or the Tools tab at the top, and select 'Scan & OCR'. Under the menu that appears, click 'Recognize Text' and then select 'In This File'.
Choose the primary language of the document and the specific page range you want to process. Click the 'Recognize Text' button to run the OCR process.
Extract and Edit Text from Scanned PDFs with WPS Office
WPS Office features a powerful built-in OCR tool in its PDF editor, allowing you to instantly convert scanned images and image-based PDFs into fully editable and searchable text.
- 1. Open your PDF in WPS Office: Launch WPS Office and open the scanned or image-based PDF file you need to edit.
- 2. Launch the OCR Tool: Go to the 'Tools' tab on the top ribbon and click on 'OCR'. The software will prompt you to select the language and the pages to scan.
- 3. Extract or Convert to Editable Format: Choose whether to extract the text directly or convert the scanned PDF into an editable Word document, then proceed to make your required text edits.

Frequently Asked Questions
Why is the Recognize Text option disabled in my PDF editor?
The text recognition command is typically disabled if the PDF file is secured with a permissions password restricting document changes, or if you are using a free PDF viewer that lacks OCR functionality.
How can I improve OCR accuracy on my scanned PDFs?
To get the best OCR results, ensure the original scan is of high quality (at least 300 DPI), properly aligned without skewed pages, and free from smudges, handwriting, or dark shadows.
Can I convert an image-based PDF directly into a Word document?
Yes, many modern PDF editors with OCR capabilities, including WPS Office, allow you to recognize the text in an image-based PDF and export it directly as an editable Microsoft Word document.


