

How to OCR a PDF Form Without Losing Fillable Fields

Question details
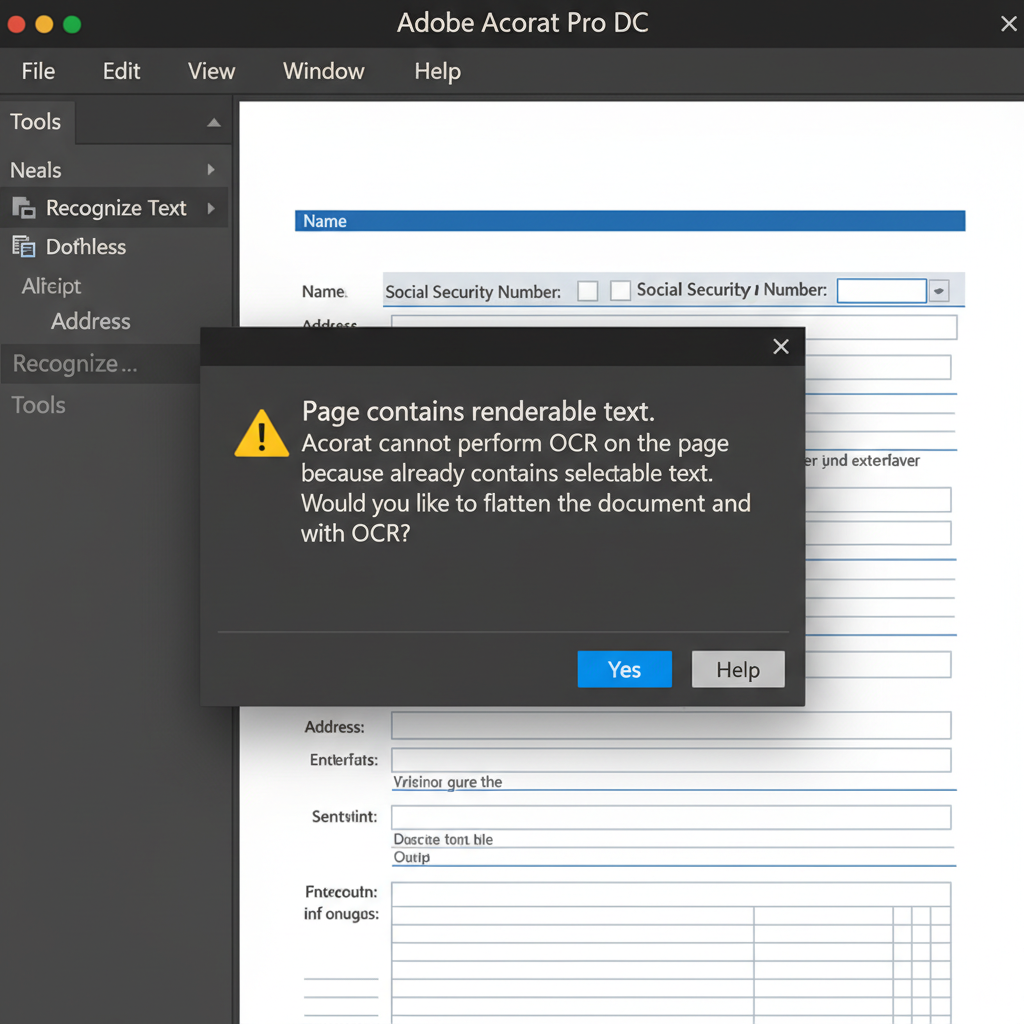
The user needs to perform OCR on a PDF form to make text searchable without destroying or losing the interactive fillable fields, while bypassing the 'renderable text' error in Adobe Acrobat.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to run OCR (Recognize Text) on a PDF form that already contains digital form fields, causing the software to throw an error or flatten the fields.
- Observed behavior
- Acrobat returns a 'page contains renderable text' error and refuses to run OCR, or the process flattens the document and removes the interactive form fields.
Always save a backup copy of your original interactive PDF form before attempting OCR or flattening the document, as fillable fields cannot be easily restored once permanently flattened.
Use a Flattened Copy for OCR and Restore Fields
Since OCR engines cannot process pages that already contain renderable text or active fields, you must flatten the document for OCR processing and recreate the fields afterward.
Acrobat's OCR engine is designed exclusively for scanned images. If your PDF form contains live digital text (renderable text) or active interactive fields, the software will return an error preventing the OCR process.
To resolve this, you need to create a flattened, image-based version of the PDF for the OCR engine to process, and then overlay the interactive form fields onto the newly searchable document.
Open your original PDF form, go to 'File' > 'Print', and select 'Microsoft Print to PDF' or 'Adobe PDF' as your printer. This generates a flattened, image-based copy of your document without interactive fields.
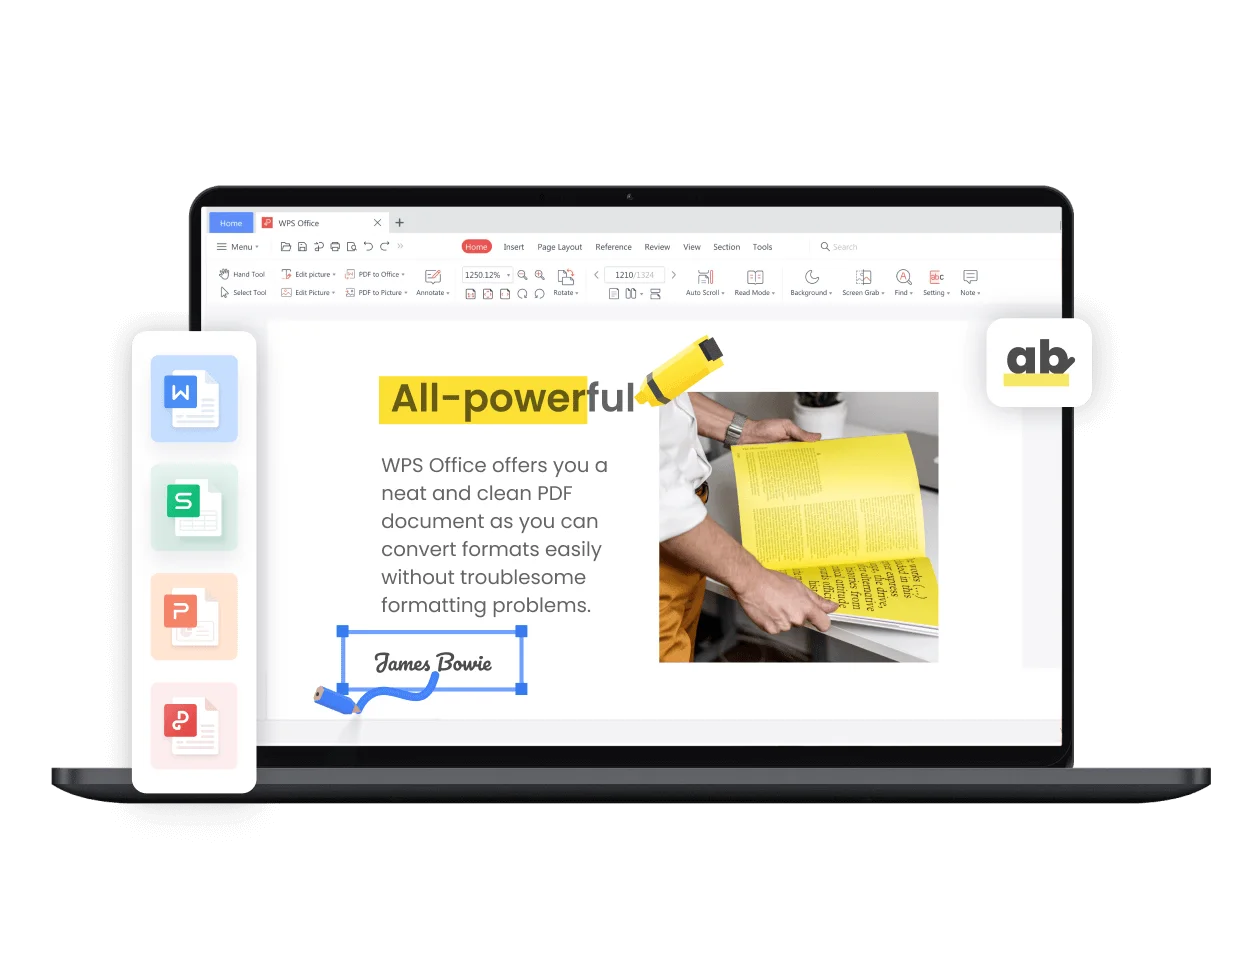
Open the newly saved flattened PDF in Acrobat. Navigate to 'Tools' > 'Scan & OCR' and click 'Recognize Text' > 'In This File' to make the text fully searchable.
Go to 'Tools' > 'Prepare Form'. Acrobat will automatically detect and place fillable fields over the recognized text. You can manually adjust or copy-paste specific fields from your backup file if needed.
Edit and OCR PDF Forms Effortlessly with WPS Office
WPS Office features a powerful built-in PDF editor that handles OCR and fillable forms with ease. You can extract text from scanned documents, convert them to editable formats, and seamlessly manage interactive form fields without complex Acrobat workarounds.
- 1. Open your PDF in WPS: Launch WPS Office and open your scanned or interactive PDF document from the home screen.
- 2. Use the OCR feature: Navigate to the 'Tools' tab and click the 'OCR' button to accurately extract text or make the document searchable.
- 3. Manage Form Fields: Switch to the 'Form' tab to fill, edit, or highlight interactive fields securely without losing their original formatting properties.
Frequently Asked Questions
Why does Acrobat say 'page contains renderable text' during OCR?
This error occurs when the PDF page already contains digital, highlightable text or active form fields. Acrobat's OCR engine is designed to only process pure images or scanned pages that have no existing text layers.
Can I OCR a document and keep the existing form fields intact?
Directly running OCR on a document with live form fields usually causes software conflicts. You must typically run OCR on a base image of the document first, and then overlay or recreate the fillable form fields afterward.
Does printing to PDF remove my fillable fields?
Yes, using the 'Print to PDF' function flattens the document. It converts all interactive form fields and digital text into a single static image layer, which is useful for bypassing OCR errors but requires the fields to be recreated later.


