

How to Convert Scanned PDFs to Searchable TXT Files in Adobe Acrobat

Question details
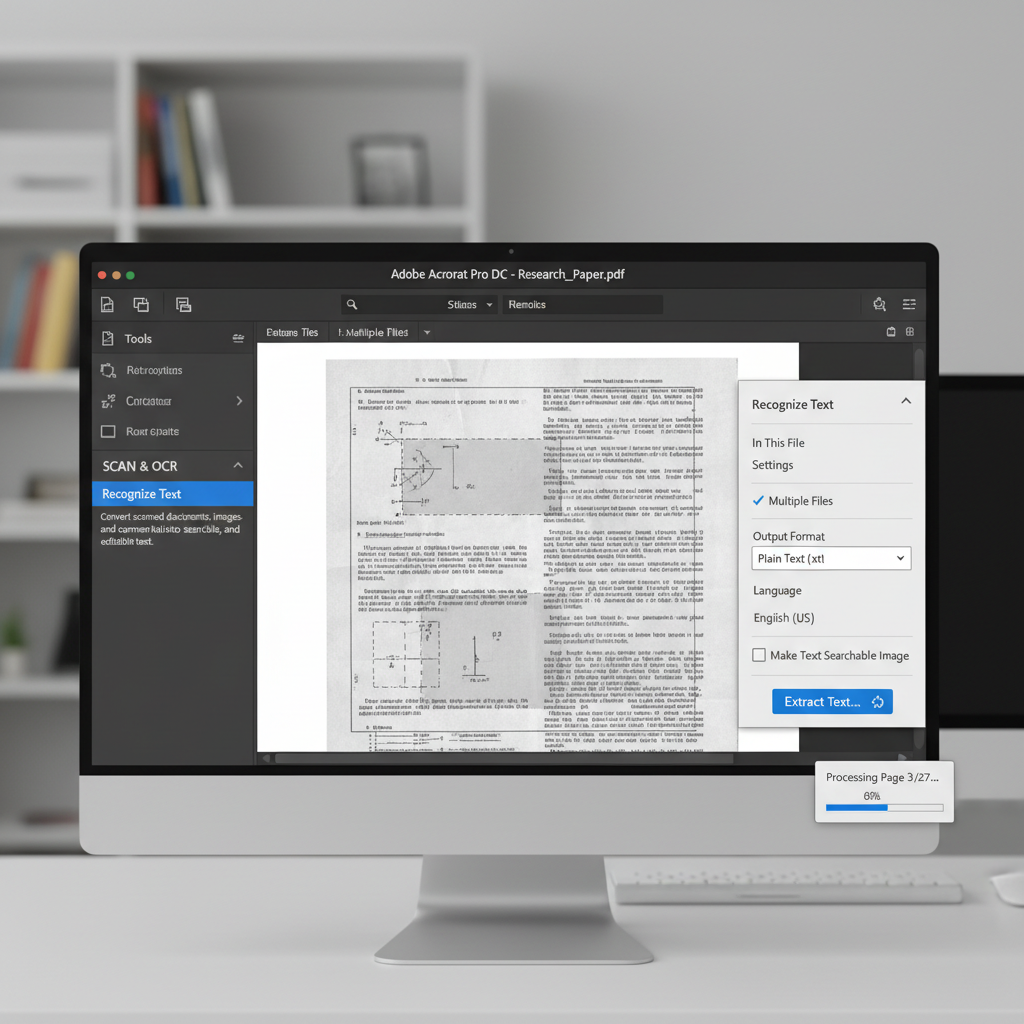
The user needs to digitize scanned PDF documents and export their contents as searchable plain text files.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Digitizing research documents for data analysis and text scraping.
- Observed behavior
- Requires a workflow to process scanned (image-based) PDFs through OCR and save the extracted data directly into a TXT format.
Ensure that your scanned PDF documents are clear and legible, as the visual quality of the original scan heavily impacts the accuracy of the Optical Character Recognition (OCR) extraction.
Use Acrobat Export PDF Tool with OCR
Utilize Adobe Acrobat's built-in OCR capabilities to automatically recognize text from images and export it directly to a TXT file.
Adobe Acrobat Pro DC includes an automated OCR engine that triggers when you attempt to export a scanned PDF into a text-based format.
Because OCR is not perfect, highly complex layouts or faded text might not convert flawlessly, making a post-conversion review essential.
Launch Adobe Acrobat Pro DC and open the scanned PDF research document you wish to convert.
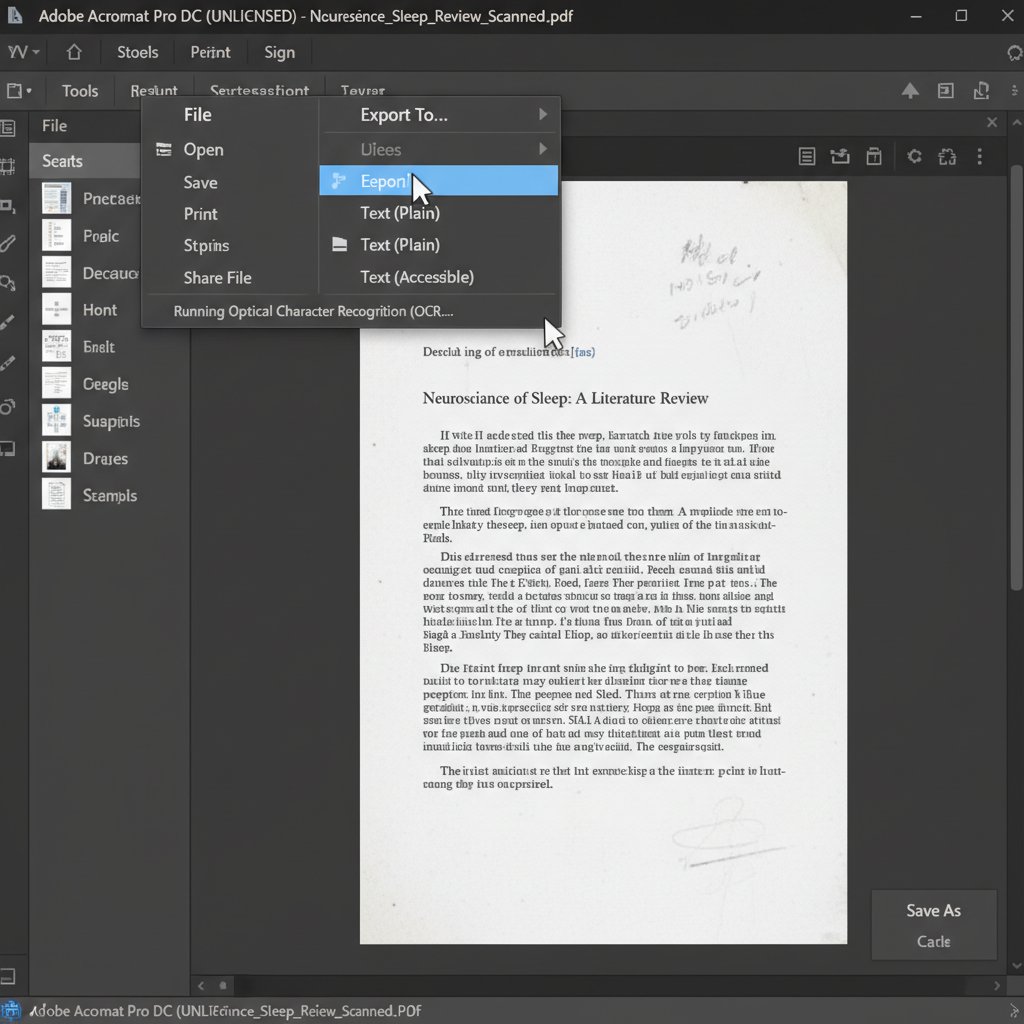
Click on the 'File' menu located in the upper-left corner of the Acrobat interface.
Choose 'Export To' from the dropdown list, then select 'Text (Plain)' or 'Text (Accessible)' depending on your data scraping requirements.
Choose a destination folder and click 'Save'. Acrobat will run OCR automatically. Open the resulting TXT file to review and correct any potential recognition errors.
Extract Text from Scanned PDFs Instantly with WPS Office
WPS Office provides powerful PDF editing and conversion tools, including advanced OCR technology that easily recognizes text in scanned documents and exports them to editable formats for data extraction.
- 1. Open the PDF in WPS Office: Launch WPS Office and open your scanned PDF document in the PDF viewer.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' or 'PDF to Text' button.
- 3. Configure Extraction Settings: Select the specific pages you need to extract and choose TXT or Document as your desired output format.
- 4. Convert and Save: Click the 'Convert' button. WPS Office will process the image-based text and generate an accurate text file for your data scraping needs.

Frequently Asked Questions
Why does my exported TXT file contain random characters or gibberish?
This usually happens when the OCR engine misinterprets unclear text, faded ink, watermarks, or complex layouts in the original scanned document. Improving the contrast and clarity of the scan before running OCR can resolve this issue.
Can I convert only specific pages of a scanned PDF to text?
Yes, when exporting the document via File > Export To in Adobe Acrobat, you can specify a precise page range in the export settings dialog box instead of processing the entire document.
Does extracting text to a TXT file preserve my document's layout?
No, exporting to plain text (TXT) strips away all formatting, images, font styles, and table structures, leaving only the raw text strings. If you need to keep the visual layout intact, export the scanned PDF to a Word (.docx) document instead.
Is OCR required to extract text from all PDF files?
No, OCR (Optical Character Recognition) is only necessary for scanned documents or image-based PDFs where the text is fundamentally a picture. For standard, digitally created PDFs, you can directly highlight, copy, or export the text without needing OCR.


