

How to Fix Messy OCR Text When Optimizing Scanned PDFs
Question details
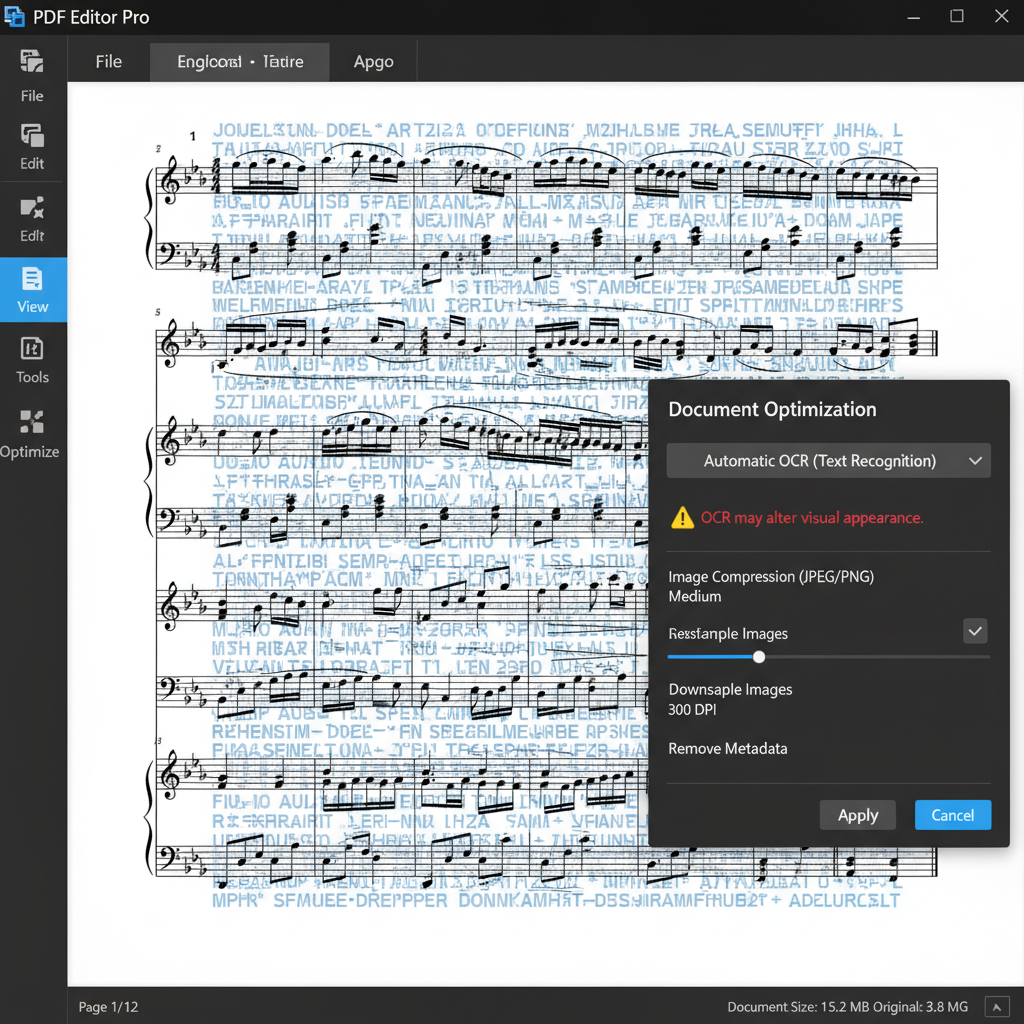
The user needs to prevent their PDF software from automatically applying OCR and creating misaligned text when optimizing scanned documents.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Optimizing scanned PDFs, such as music scores, to reduce file size without altering their visual appearance.
- Observed behavior
- The software's automatic OCR misinterprets the scanned images, overlaying messy, misaligned text on top of the original content and making it difficult to read.
Ensure your PDF editor is updated to the latest version, as recent patches often resolve OCR alignment bugs and improve text recognition handling.
Disable Automatic Text Recognition During Optimization
Adjust your PDF optimizer settings to prevent the software from running OCR automatically on complex scanned images.
When optimizing scanned documents, many advanced PDF editors automatically attempt to make the text searchable. For documents with complex layouts like music scores or intricate diagrams, this can result in messy, misaligned text layers. Disabling this automatic feature ensures your file is optimized without altering its appearance.
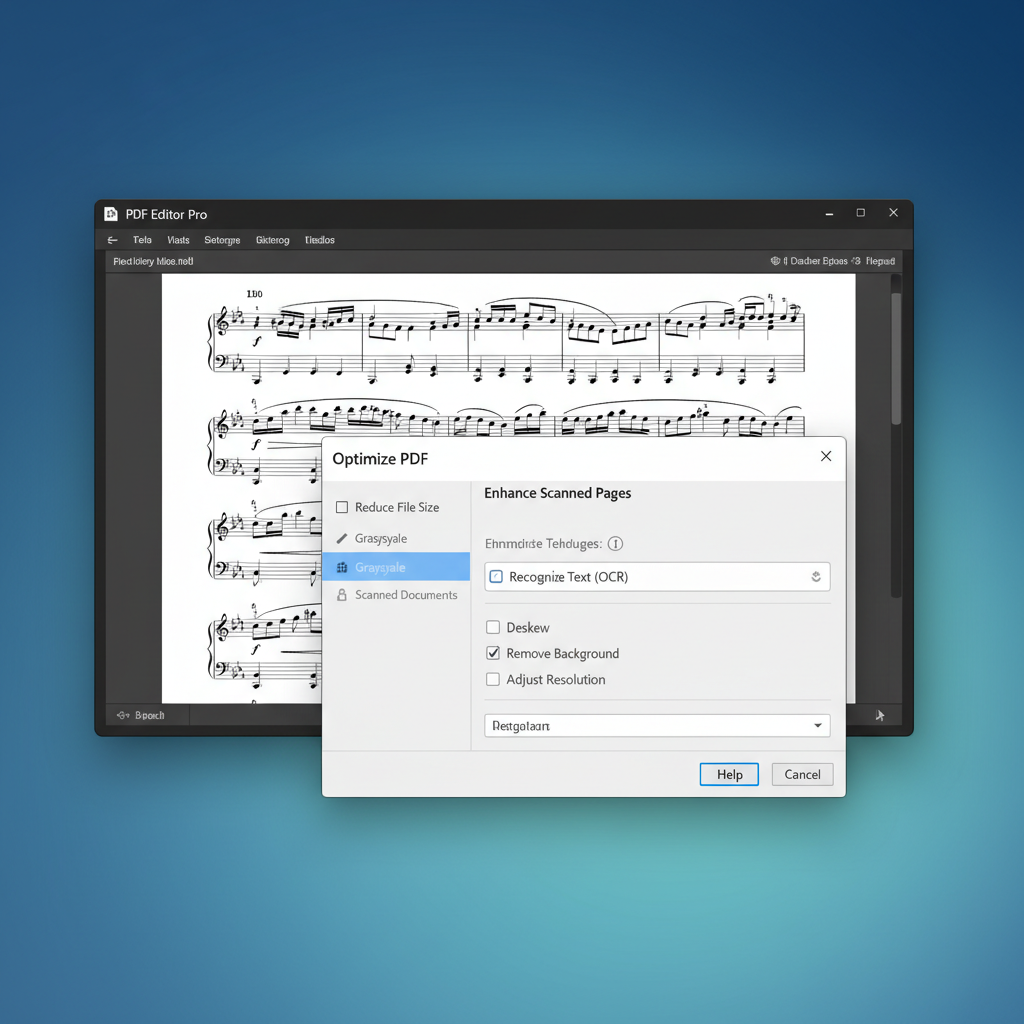
Open your scanned PDF document in your PDF editor, navigate to the 'Tools' menu, and select 'Optimize PDF' or 'Enhance Scans'.
Click on the 'Enhance' or 'Scanned Pages' option in the top toolbar to reveal the specific settings for processing scanned files.
Locate the 'Recognize Text' option or checkbox in the enhancement settings menu and uncheck it to disable automatic OCR.
Click 'OK' to apply your new settings, then save your optimized document. The file size will be reduced while keeping the original image layout intact.
Export as an Image-Only PDF
If you do not need searchable text, exporting the document as an image-only PDF ensures no OCR text layer is generated at all.
Optimize Scanned PDFs Safely Using WPS Office
WPS Office provides a powerful, built-in PDF editor that allows you to compress and manage scanned documents easily. You can optimize file sizes without being forced into automatic, messy OCR overlays, keeping your music scores and image-heavy documents pristine.
- 1. Open Your Scanned PDF: Download and open WPS Office, then click on 'PDF Edit' to load your scanned document into the workspace.
- 2. Access the Compress Tool: Navigate to the 'Tools' tab on the top ribbon and select 'Compress' to open the file size reduction menu.
- 3. Select Compression Level: Choose your desired compression level (such as HD, Normal, or Common) to balance file size and visual quality without enabling text recognition.
- 4. Compress and Save: Click the 'Compress' button to optimize the file instantly. The result is a smaller PDF that retains its original appearance perfectly.
Frequently Asked Questions
Why does optimizing my scanned PDF make the text look messy?
Some PDF editors automatically run Optical Character Recognition (OCR) during the optimization process to make the document searchable. If the original image has complex layouts like music scores or artistic fonts, the software may misinterpret the shapes and overlay incorrect, misaligned text on top of the image.
Can I remove unwanted OCR text from an already optimized PDF?
Yes, in many advanced PDF editors, you can select the 'Edit PDF' tool, click on the unwanted text boxes generated by the OCR process, and delete them manually. Alternatively, it is often faster to revert to the original scanned file and optimize it again with OCR settings disabled.
Is OCR always applied when reducing a PDF's file size?
No, OCR is an optional feature. Most modern PDF editors allow you to compress and optimize the document's file size independently of text recognition. You simply need to ensure the 'Recognize Text' setting is turned off before starting the compression process.


