

How to Configure Acrobat OCR Settings for Searchable Image PDFs
Question details
The user wants to understand how to correctly configure Adobe Acrobat OCR settings to create Searchable Image PDFs without losing image quality, and how different OCR options function.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Converting scanned documents or images to searchable PDFs using Acrobat's OCR feature while balancing file size and text or image clarity.
- Observed behavior
- By default, settings like Searchable Image may appear to reduce image quality due to automatic downsampling, and users may not understand the difference between preservation modes like ClearScan.
Before adjusting OCR settings, ensure your source document is scanned at a sufficiently high resolution (at least 300 DPI) for accurate text recognition, and save a backup copy of the original PDF in case the OCR downsampling alters the image quality permanently.
Optimize Searchable Image and Downsample Settings
Adjust the downsampling settings to prevent Acrobat from heavily reducing the resolution of your original images during the OCR process.
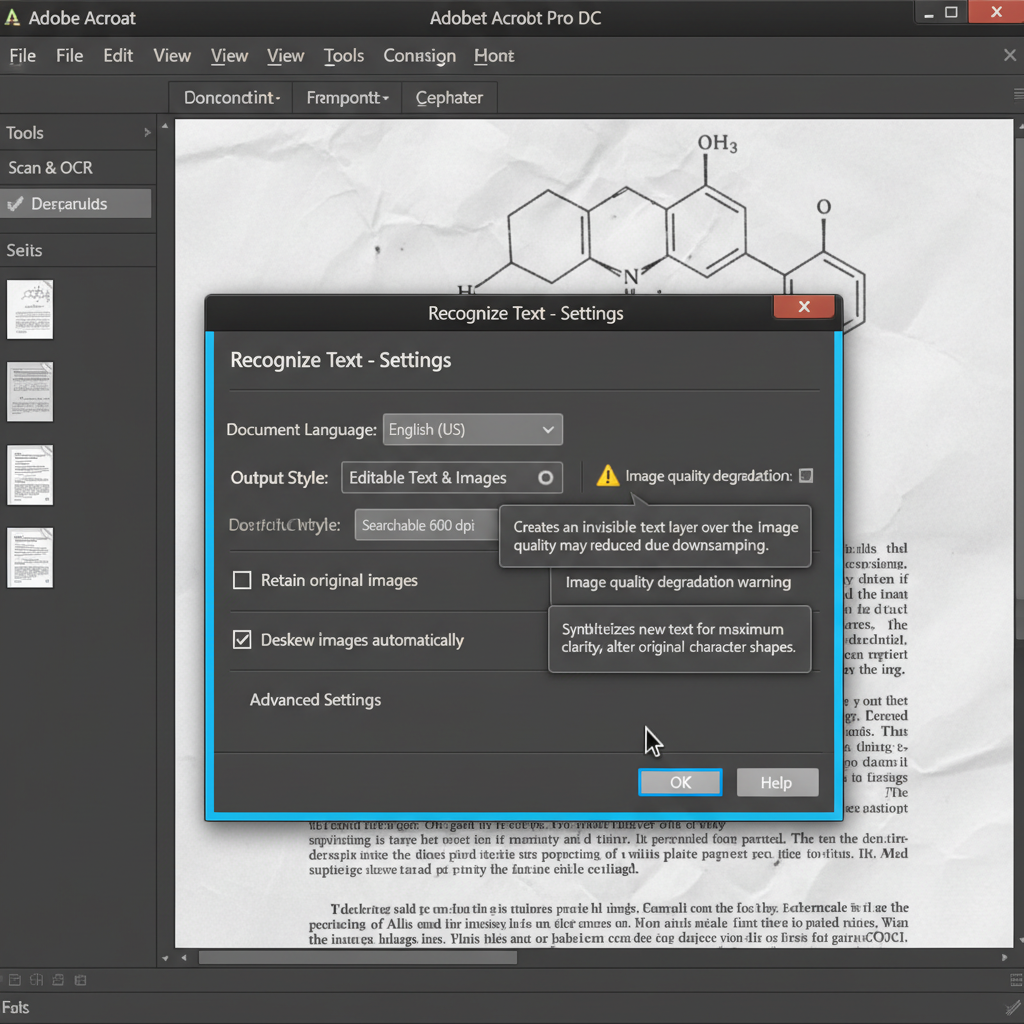
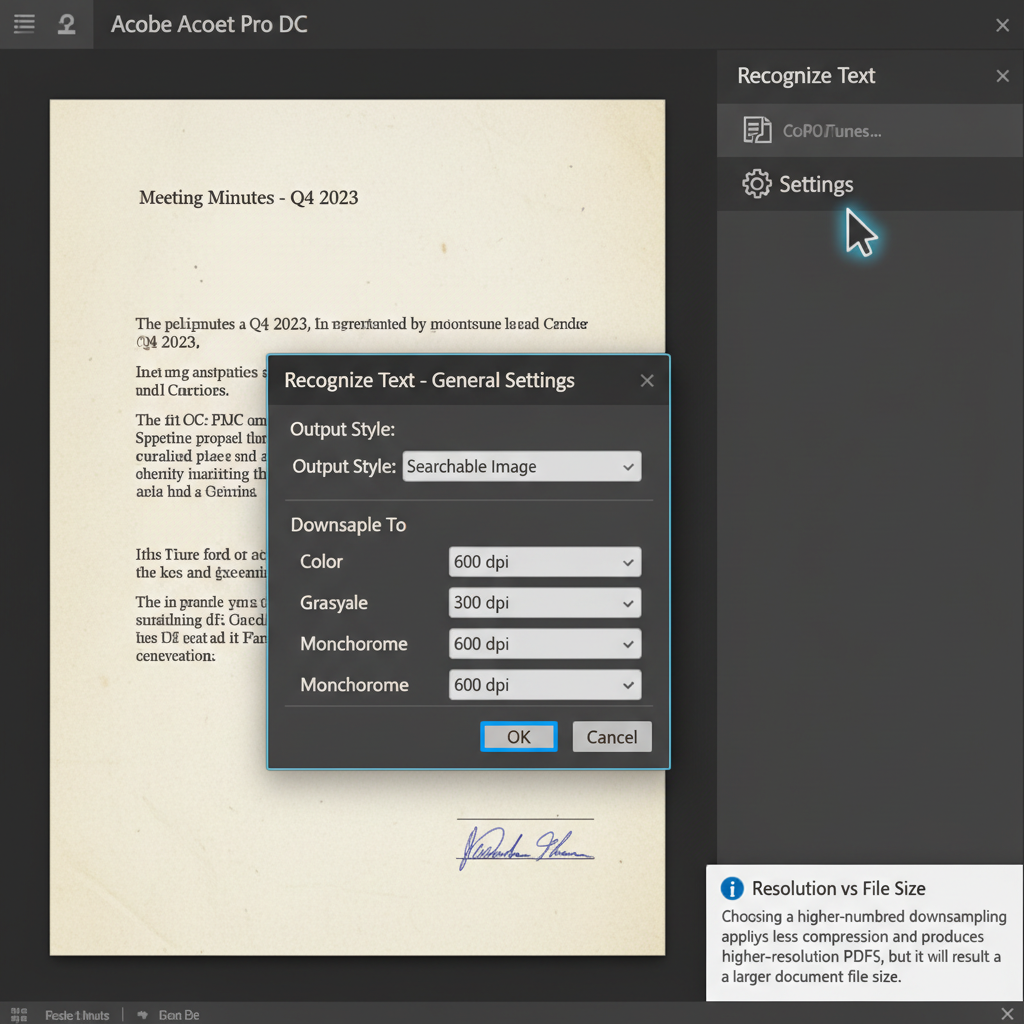
The Searchable Image option makes text searchable and selectable by placing an invisible text layer over the original document image. However, the associated downsampling settings reduce the number of pixels in color, grayscale, and monochrome images to save file size, which can degrade quality.
Launch Adobe Acrobat, open your scanned PDF, and select the 'Recognize Text' tool from the right-hand pane or the Tools menu.
Click on 'Settings' (often represented by a gear icon) in the Recognize Text toolbar to open the recognition configuration dialog.
In the settings window, change the 'Output' style from the dropdown menu to 'Searchable Image'.
Look for the 'Downsample To' option. To maintain maximum image quality, select the highest available DPI setting (e.g., 600 dpi), or disable downsampling if your version allows it.
Click 'OK' to save your settings and run the text recognition process on your document.
Utilize Editable Text & Images (ClearScan) for Custom Fonts
Use this setting when you need the text to be fully editable, replacing the original image text with a mathematically approximated custom font.
Create Searchable PDFs Easily with WPS Office
WPS Office features a powerful built-in OCR engine that quickly converts scanned documents and images into fully searchable and editable PDFs, giving you complete control over output quality and formats.
- 1. Open your PDF: Launch WPS Office and open your scanned PDF document in the PDF editor.
- 2. Navigate to the OCR Tool: Go to the 'Tools' tab on the top ribbon and click the 'OCR' button to launch the recognition panel.
- 3. Choose Output Preferences: Select your desired output operation, such as 'Searchable PDF' to overlay invisible text or 'Extract Text' for raw document conversion.
- 4. Process and Save: Select the correct document language to maximize accuracy, click 'Start' to process the text, and save your new searchable file.

Frequently Asked Questions
Why does my PDF look blurry after applying Acrobat OCR?
This typically occurs because Acrobat's 'Downsample To' setting reduces the pixels of the original image layers during processing to decrease file size. To prevent this, change the downsample setting to a higher DPI value or disable downsampling in the OCR settings.
Can Acrobat OCR process separate areas of a page independently?
No, Adobe Acrobat OCR processes the entire page as a whole. It does not currently support independent processing for separate page areas or user-defined zones on the same page.
What is the difference between Searchable Image and Editable Text & Images?
'Searchable Image' keeps the scanned image exactly as it is and adds an invisible layer of text on top for searching. 'Editable Text & Images' (ClearScan) replaces the actual text in the image with visually similar digital fonts that you can modify directly, converting the remaining background to a lower-resolution image.


