

How to Use Image Recognition and OCR to Sort Faxed PDFs
Question details
The user wants to automatically sort image-only faxed PDFs by source using OCR or image recognition on cover pages.
- Product
- PDF Editors
- Device & OS
- not provided
- Scenario
- Automating the sorting and routing of incoming faxed PDFs based on sender information or visual cover-page templates.
- Observed behavior
- Standard OCR fails because faxed PDFs are often low-resolution, image-only files with artifacts, making text extraction unreliable.
Ensure that the source fax machines or scanners are configured to send files at the highest possible resolution (at least 300 DPI) and use high-contrast, black-and-white settings without background shading.
Optimize OCR Settings for Faxed PDFs
Use exact searchable image settings in your PDF editor to create a hidden text layer without modifying the original low-quality fax appearance.
Standard OCR works by analyzing contrasting pixels to identify letters. Because older faxes often transmit at 140 to 200 PPI, the software struggles to distinguish characters accurately, especially when words are split across lines.
To improve text recognition, you must force your PDF software to process the document as a high-contrast image while retaining the visual layout.
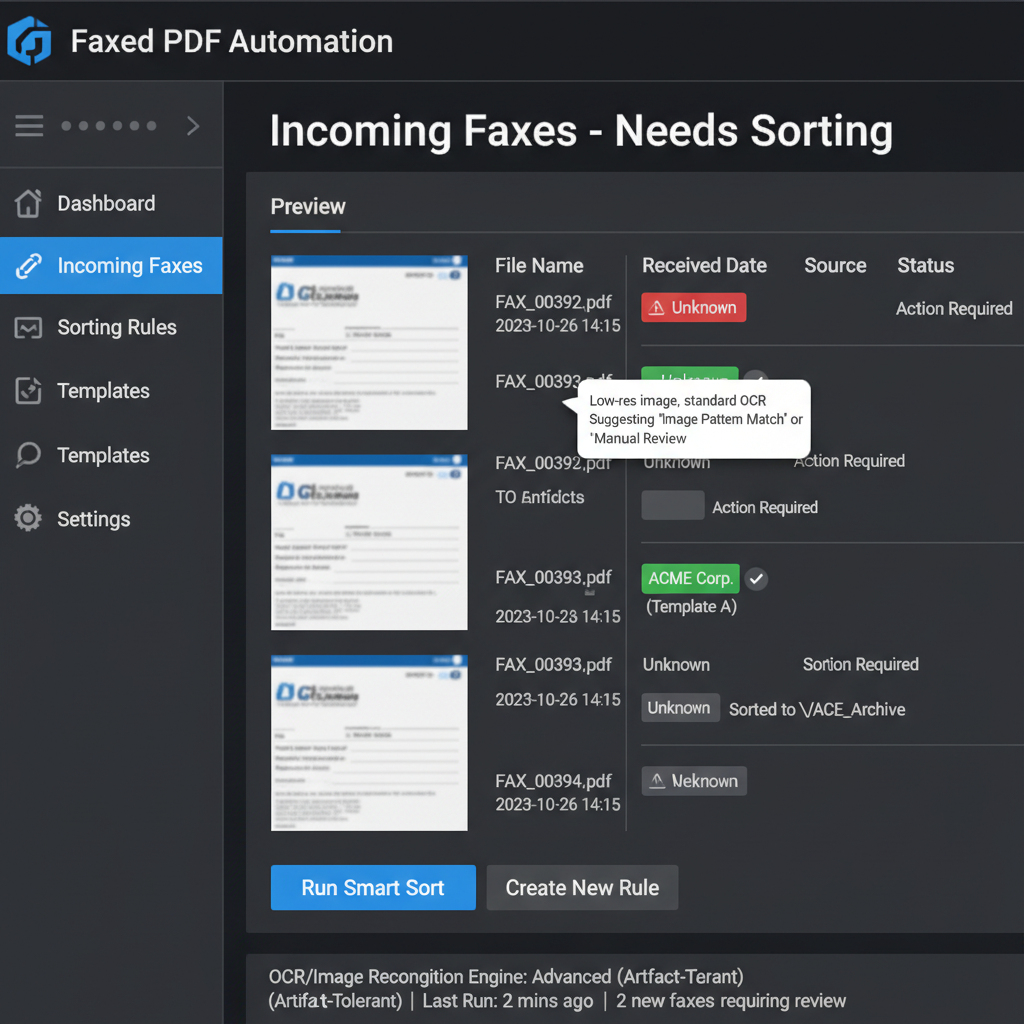
Launch your advanced PDF editor and navigate to the 'Tools' or 'Edit' menu to select the 'Recognize Text' or 'OCR' feature.
In the OCR settings menu, change the output style to 'Searchable Image (Exact)'. This ensures the original fax image remains intact while text is mapped invisibly over it.
Set the document language, apply the setting to all pages, and click 'OK' or 'Start' to process the file.
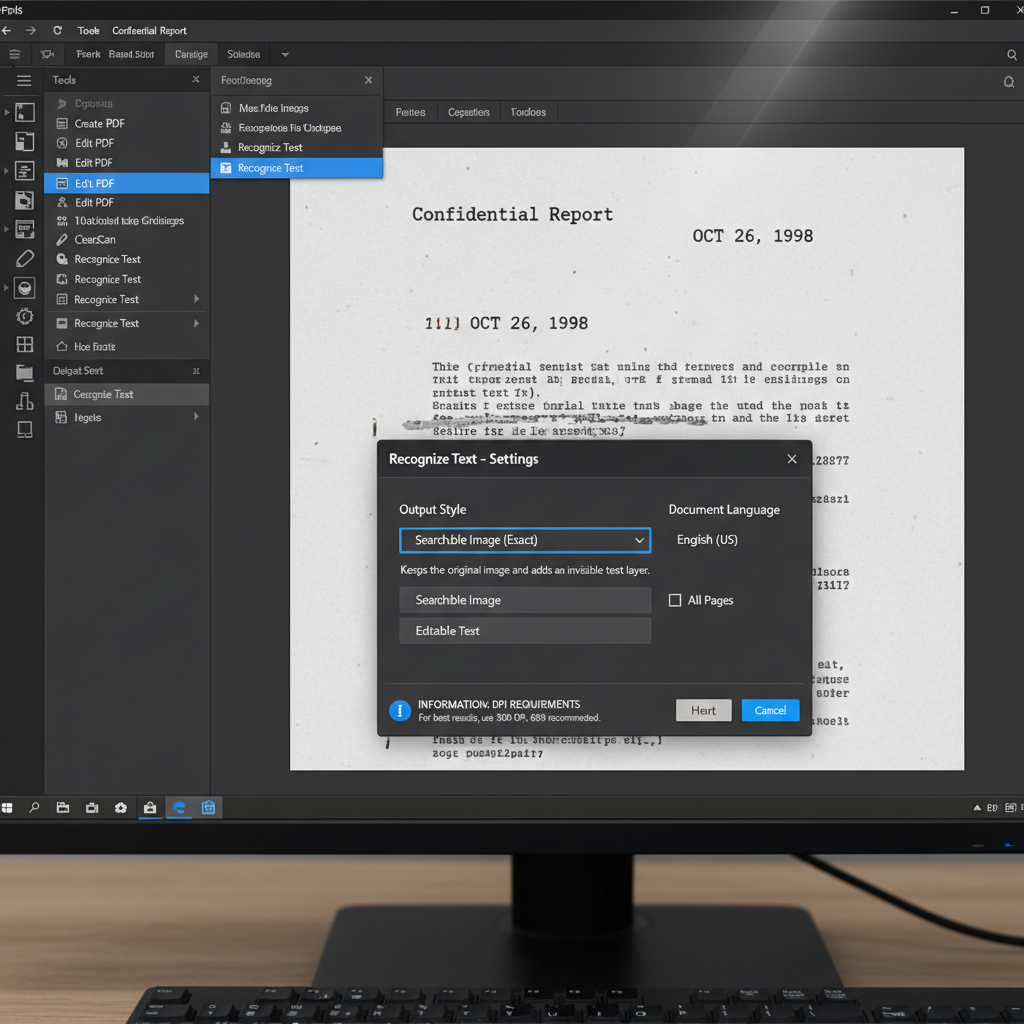
Implement Document Classification for Visual Matching
Bypass text recognition entirely by using image-recognition software to sort faxes based on visual templates of cover pages.
Extract Text from Scanned PDFs with WPS Office
WPS Office includes a highly accurate, built-in OCR engine designed to extract text from scanned documents and image-only PDFs, making it easier to manage and organize your digital files.
- 1. Open the PDF: Launch WPS Office and open your image-only or faxed PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on 'OCR' to initiate the text recognition process.
- 3. Extract and Save: Highlight the specific area you want to recognize or process the entire document, then save the extracted text as a searchable PDF or Word document.
Frequently Asked Questions
Why does OCR frequently fail on older faxed documents?
Older fax machines typically compress and transmit documents at very low resolutions (around 140 to 200 PPI). OCR software requires clean, high-contrast images at a minimum of 300 DPI to accurately differentiate between individual letters and background noise.
Can I sort PDFs using logos instead of text?
Yes. If text recognition is unreliable, you can use specialized document classification or image-recognition software. These programs analyze the graphical layout or logo on a document and match it against a pre-existing library of known cover-page templates.
How can I improve the quality of incoming faxes for better recognition?
Whenever possible, request that senders configure their fax machines to 'Fine' or 'Super Fine' resolution modes. Additionally, ask them to disable background shading or watermarks and ensure the physical pages they scan are clean and high-contrast.


