

How to Fix Partial OCR Recognition on Image-Based PDFs in Acrobat Pro DC

Question details
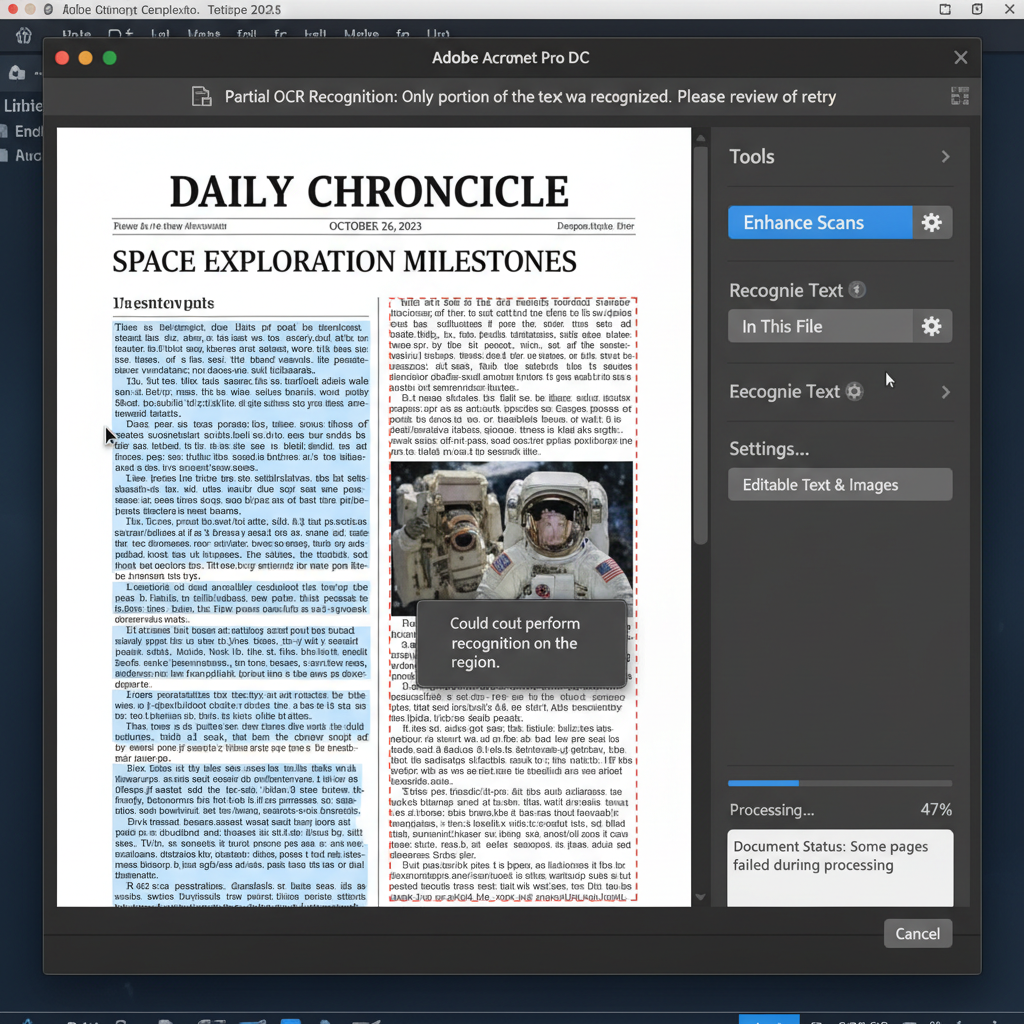
The user needs to fully extract editable text from complex image-based PDFs, such as scanned newspaper pages, where the OCR engine only recognizes partial text.
- Product
- Adobe Acrobat Pro DC
- Device & OS
- not provided
- Scenario
- Attempting to run OCR on complex or partially processed image-based PDFs to make the entire document searchable and editable.
- Observed behavior
- Acrobat recognizes only a portion of the document as editable text while leaving the rest of the document as an unsearchable image.
Before re-running OCR, ensure your document has adequate resolution (at least 300 DPI is recommended for scanned newspapers) and check if the PDF contains previously embedded text layers that might interfere with the scanning process.
Re-run OCR with 'Searchable Image Exact' Settings
Use this method to force Acrobat to recognize text on pages that may have been partially OCR-processed or treated entirely as images.
Acrobat sometimes skips sections of a document if it detects that parts of the file have already been processed or if it misidentifies text blocks as graphics. Forcing a specific output style bypasses this conflict.
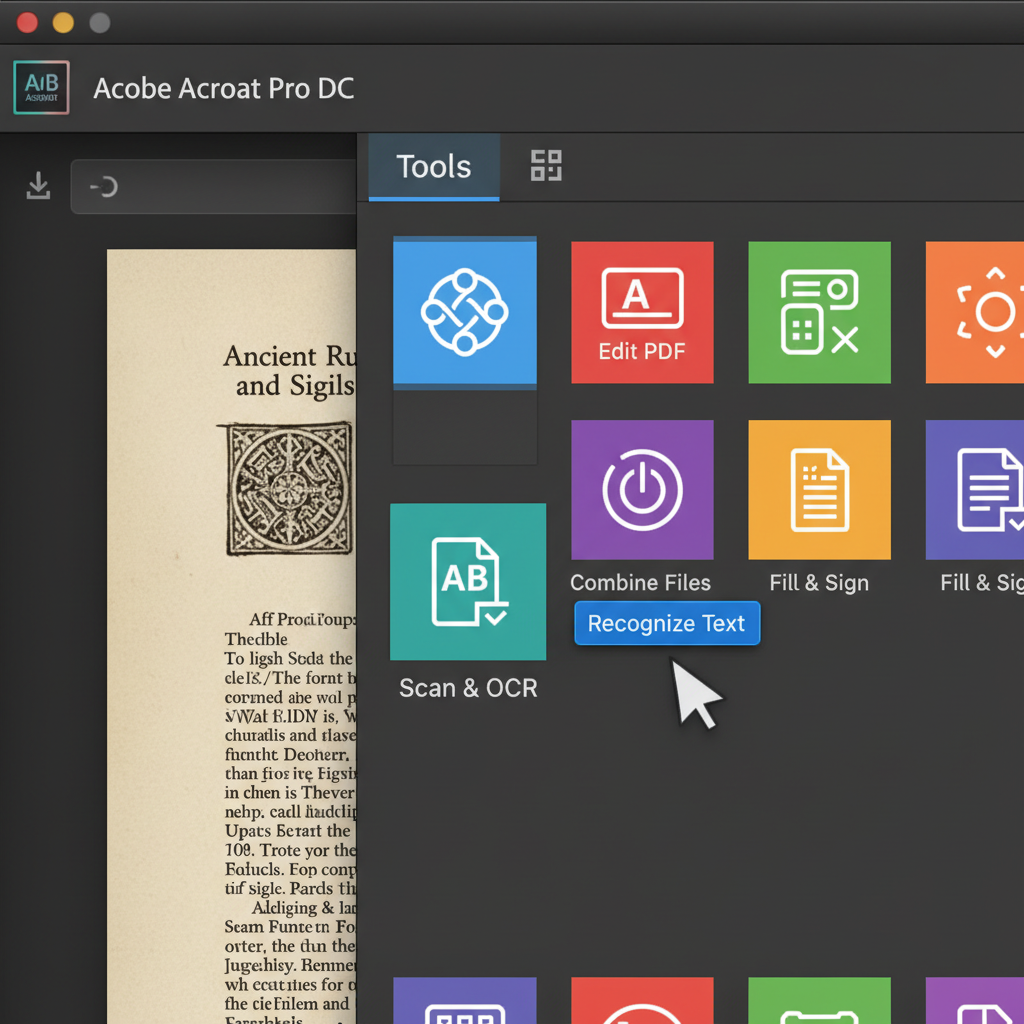
Open your PDF document in Adobe Acrobat Pro DC. Go to the 'Tools' menu and select 'Scan & OCR' (or 'Enhance Scans' in older versions).
Click on 'Recognize Text' in the secondary toolbar and choose 'In This File'. Then, click on the 'Settings' gear icon.
In the Settings dialog box, locate the Output dropdown menu and select the 'Searchable Image Exact' option. Click 'OK' to save your preferences.
Click the 'Recognize Text' button to start processing the document again. Acrobat will re-scan the entire page, forcing text recognition on the remaining image areas.
Optimize Scan Quality and Page Orientation
Low-resolution scans, low contrast, or skewed orientations often cause partial OCR recognition failures on complex layouts like newspapers.
Extract Text from Scanned PDFs Instantly Using WPS Office
If Acrobat continues to struggle with complex layouts like newspapers, WPS Office provides a robust built-in OCR engine that accurately extracts text from scanned PDFs and images, preserving the original formatting seamlessly.
- 1. Open Your PDF: Launch WPS Office and open your scanned or image-based PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Select Recognition Area: Choose whether to extract text from a specific selected area or extract text from the entire page.
- 4. Convert and Save: Select your desired output format (such as Convert to Word or Extract Text) and click 'Confirm' to process and save the editable document.
Frequently Asked Questions
Why does Acrobat only OCR part of my PDF document?
This usually happens when the PDF contains complex formatting (like newspaper columns), low-contrast areas, or if the document has already been partially OCR-processed. Acrobat may automatically skip regions it believes are already text or strictly graphical.
What does the 'Searchable Image Exact' setting do?
This setting forces the OCR engine to keep the original image completely intact without degrading its quality, while placing a hidden, searchable text layer perfectly aligned over the recognized words.
How can I improve OCR accuracy on scanned newspaper clippings?
Ensure your initial scan resolution is at least 300 DPI, increase the document's contrast to make the text bolder against the paper background, and ensure the page is straightened before running the OCR tool.
Can I extract text from a PDF without Adobe Acrobat?
Yes, you can use built-in OCR tools in robust alternatives like WPS Office. WPS Office allows you to open image-based PDFs and use its native OCR feature to extract text directly into fully editable Word or Text formats.


