

Best Workflow for OCR and Creating Searchable PDF Documents

Question details
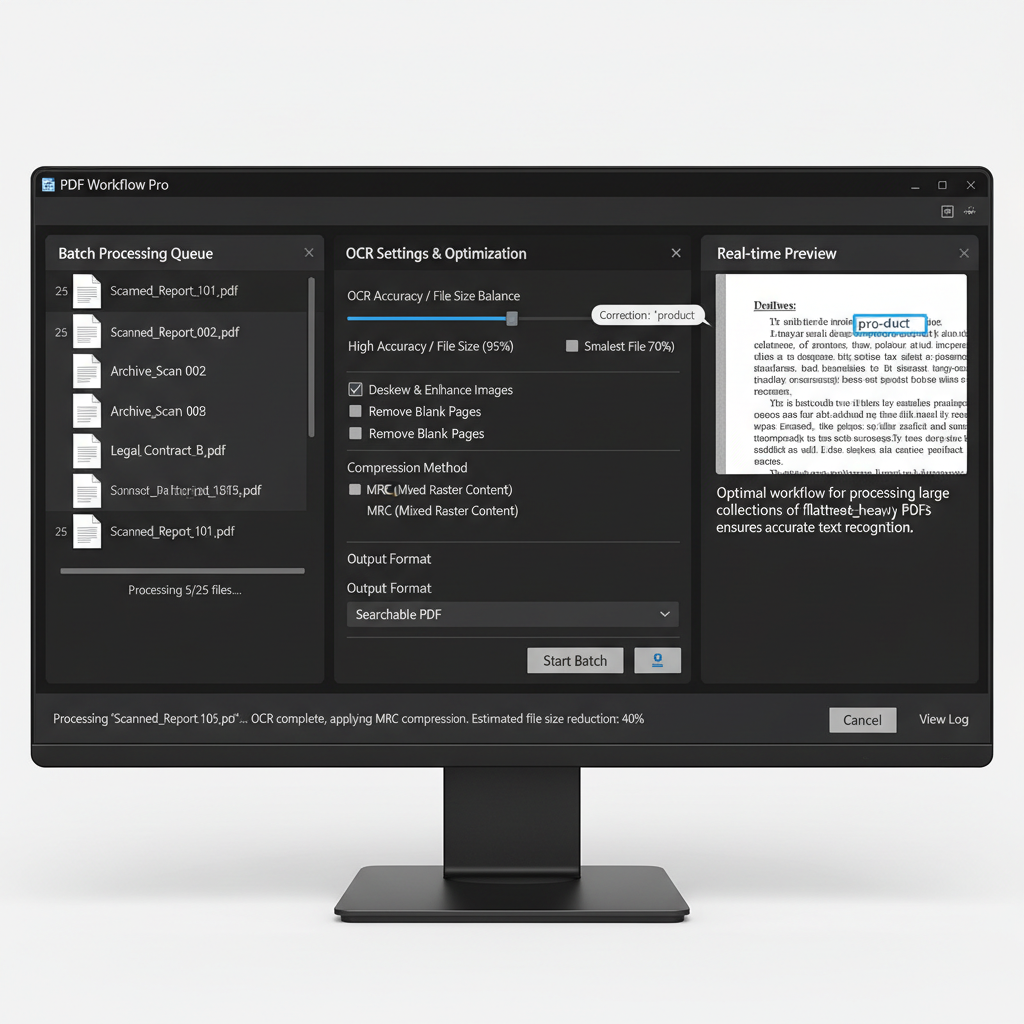
The user is looking for an optimal workflow to process a large collection of flattened, image-heavy PDFs to ensure accurate OCR text recognition while keeping file sizes reasonable.
- Product
- PDF Software
- Device & OS
- not provided
- Scenario
- Applying Optical Character Recognition (OCR) to batches of scanned documents to make them searchable without heavily bloating the file sizes.
- Observed behavior
- Finding a balance is required because low-resolution scans save space but reduce text recognition accuracy, leading to unsearchable hyphenated words or misidentified characters.
Ensure your original document scans are of high resolution and clear quality, as OCR accuracy heavily depends on the source material.
Use Optimize Scanned Pages Workflow in Adobe Acrobat
Run Acrobat's built-in optimization tools to recognize text and reduce the file size of scanned documents efficiently.
Applying OCR during the optimization process ensures that the software analyzes the high-quality source images before any aggressive downsampling is applied to reduce the PDF size.
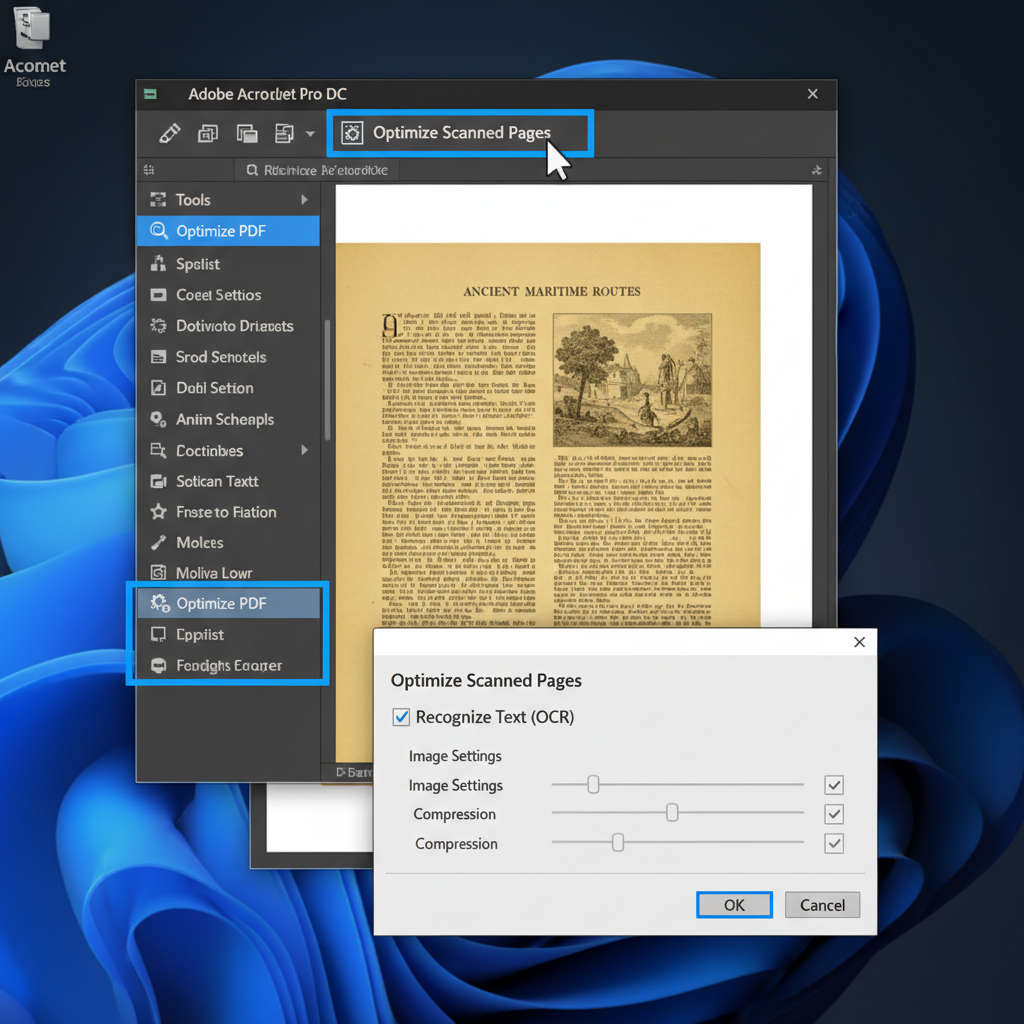
Open your image-heavy PDF in Adobe Acrobat, navigate to the 'Tools' menu, and select 'Optimize PDF'.
Click on 'Optimize Scanned Pages' from the top menu bar.
In the optimization settings, ensure the 'Recognize Text' checkbox is selected, then proceed to run the optimization.
If the resulting document is still too large, return to the Optimize PDF menu and select 'Reduce File Size' to compress the document further.
Easily Extract and Search Text in PDFs with WPS Office
WPS Office provides a highly accurate, built-in OCR (Optical Character Recognition) tool that lets you convert scanned documents and image-heavy PDFs into fully searchable and editable text files in just a few clicks.
- 1. Open PDF in WPS Office: Launch WPS Office and open your scanned or image-heavy PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Set Output and Recognize: Select your desired language and output format (choose 'Searchable PDF' to keep the original layout or 'Extract Text' for a plain document), then click 'Recognize' to process the file.

Frequently Asked Questions
Why are some words not searchable after running OCR on a PDF?
Poor original scan quality, low resolution, or complex formatting can hinder OCR accuracy. Additionally, hyphenated words split across lines or unclear letter combinations (like 'rr' being misread as 'n') often cause search failures.
Does optimizing a PDF reduce its OCR accuracy?
Standard file optimization usually targets image compression and shouldn't heavily affect already recognized OCR text. However, if you downsample images before running the OCR process, text recognition accuracy will drop significantly.
How can I improve OCR results on low-quality scanned PDFs?
To improve OCR results, rescan the original documents at a higher resolution (at least 300 DPI), ensure the text is large and clear, and increase the document contrast to make the characters stand out from the background.


