



How to Convert and Split Large Scanned PDFs for Translation

Question details
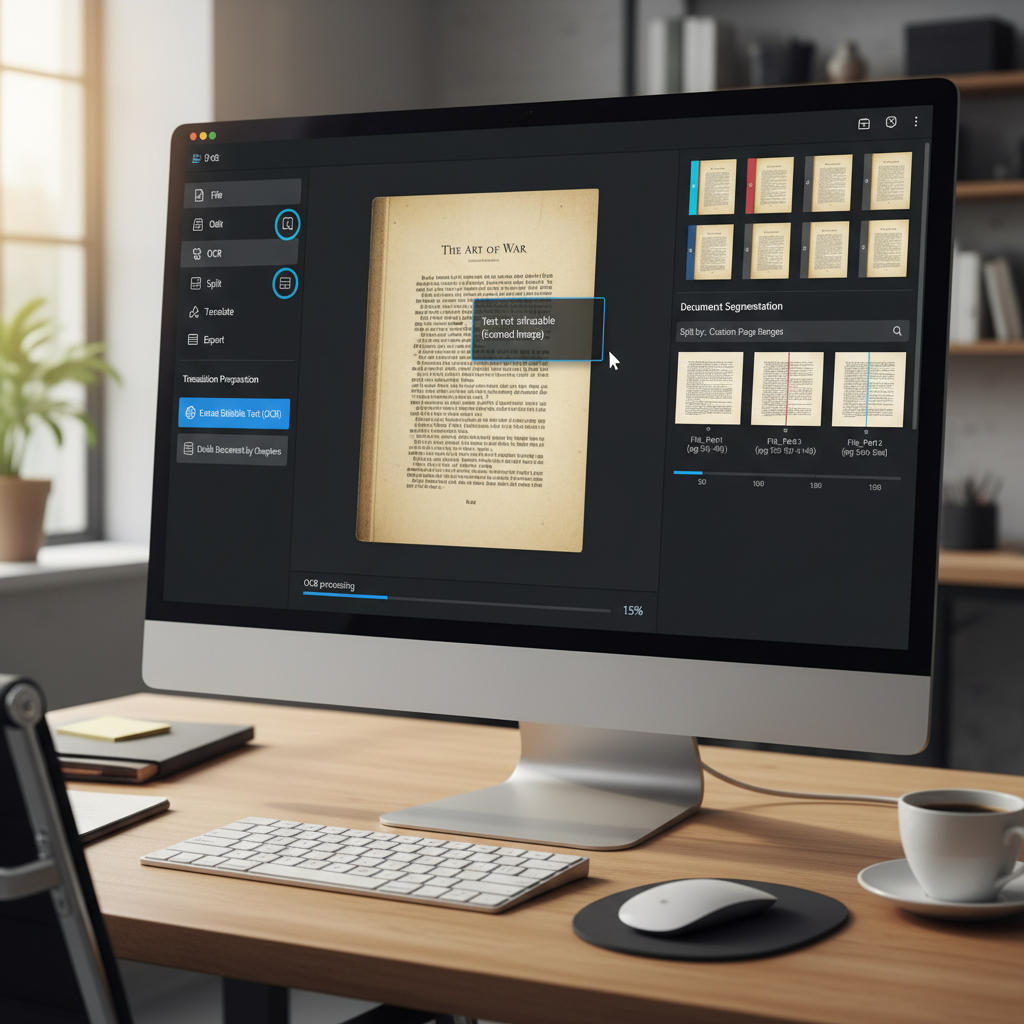
The user needs to extract editable text from large, book-length scanned PDFs and divide the documents into smaller files to facilitate the translation process.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Preparing large scanned PDF books or documents for professional or software-assisted translation.
- Observed behavior
- Scanned PDFs function as flattened images, rendering the text unselectable and uneditable, which prevents direct translation or export to word processors.
Ensure your scanned PDF has a clear, high resolution (ideally 300 DPI or higher) and determine the primary language of the text to ensure the Optical Character Recognition (OCR) yields accurate results.
Use an OCR-Capable PDF Editor to Convert and Split
Apply Optical Character Recognition (OCR) to convert scanned images into selectable text, split the file into manageable chunks, and export them as editable Word documents.
Because scanned documents do not contain actual text data, standard PDF to Word conversion will only output images. You must run OCR first to recognize the characters.
Splitting the document after OCR prevents translation software from crashing due to large file sizes and makes it easier to distribute work among multiple translators.
Launch your preferred PDF editor (such as WPS Office or Adobe Acrobat) and open the large scanned PDF document you wish to translate.
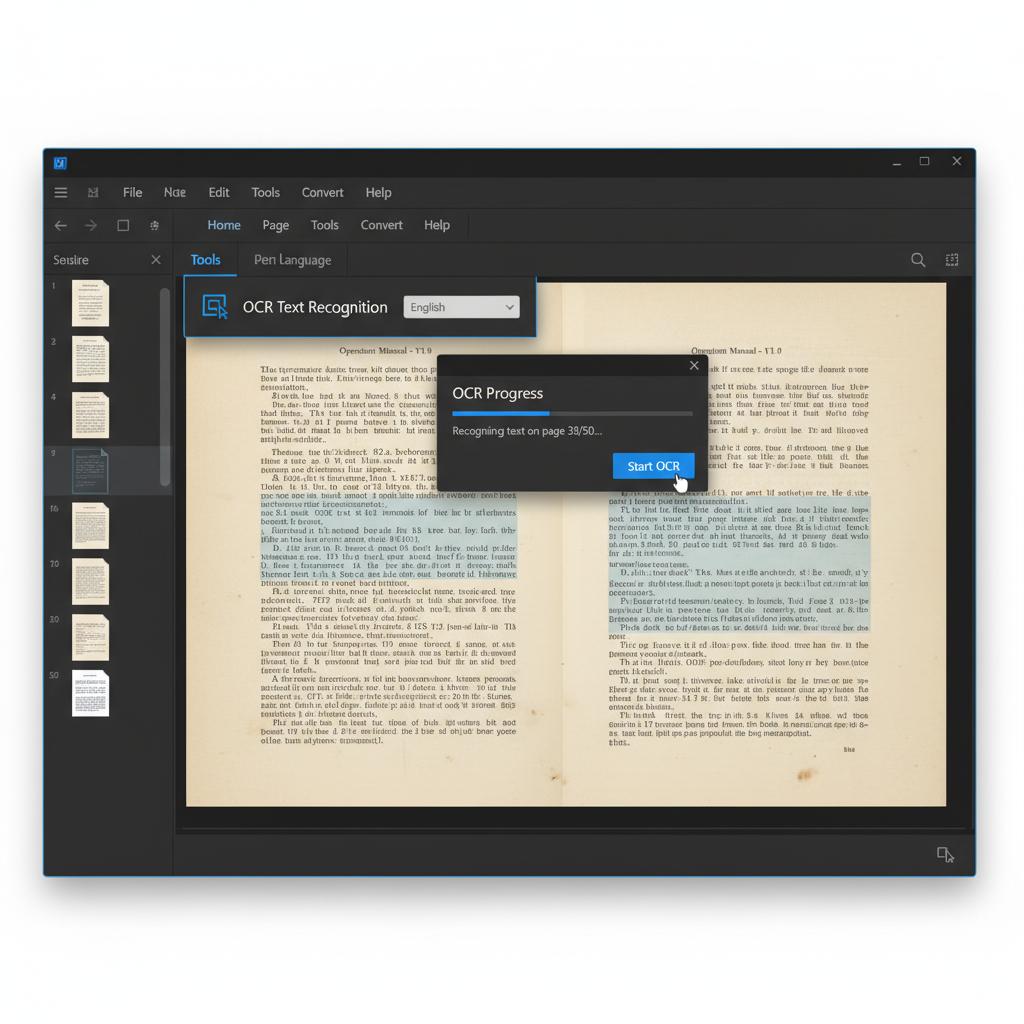
Navigate to the 'Tools' or 'Edit' tab and select the 'OCR' feature. Choose the correct language of your scanned document and start the recognition process to make the text selectable.
Go to the 'Page' or 'Organize' menu and select 'Split PDF'. Choose to split the document by a specific number of pages, file size, or bookmarks to divide the book into smaller chapters.
Open one of the newly split PDF sections. Go to the 'Convert' or 'Tools' menu and select 'PDF to Word' to save the section as a .docx file, which is ready to be loaded into your translation software.
Convert, OCR, and Split PDFs Easily with WPS Office
WPS Office offers a robust PDF toolkit equipped with highly accurate OCR technology, making it incredibly simple to extract text from scanned books, split large files into manageable chapters, and export them seamlessly into Word for your translation projects.
- 1. Open your scanned PDF: Launch WPS Office, go to the PDF tab, and open your large scanned document.
- 2. Apply OCR technology: Click on the 'Tools' tab and select 'OCR'. Choose your language settings and convert the image-based text into editable content.
- 3. Split the large file: Navigate to the 'Page' tab and click on 'Split PDF'. Define your split criteria, such as maximum page count per file, to divide the book.
- 4. Convert to Word: Open the split sections and use the 'PDF to Word' tool to export them as editable documents ready for your translation tool.
Frequently Asked Questions
Why can't I select or copy text in my scanned PDF?
Scanned PDFs are essentially digital photographs of physical pages wrapped in a PDF format. Because they consist of pixels rather than text data, you cannot select or copy the words directly. You must use Optical Character Recognition (OCR) software to analyze the images and translate them into machine-readable, editable text.
Can I translate a scanned PDF directly without converting it to Word first?
While some advanced translation tools offer built-in OCR features, it is generally not recommended for large documents or books. Converting the PDF to Word first using a dedicated OCR tool allows you to correct any text recognition errors and clean up formatting before feeding it into translation software, leading to a much more accurate final translation.
How do I split a PDF if the file size is too large for my translation software?
You can use the 'Split PDF' tool found in modern PDF editors. This feature typically allows you to divide a large document into multiple smaller files based on a set number of pages, maximum file size, or specific page ranges (like dividing a book by its chapters). This ensures the files are small enough for translation platforms to process without crashing.


