



How to Fix Adobe Acrobat Changing Zero (0) to the Letter O
Question details
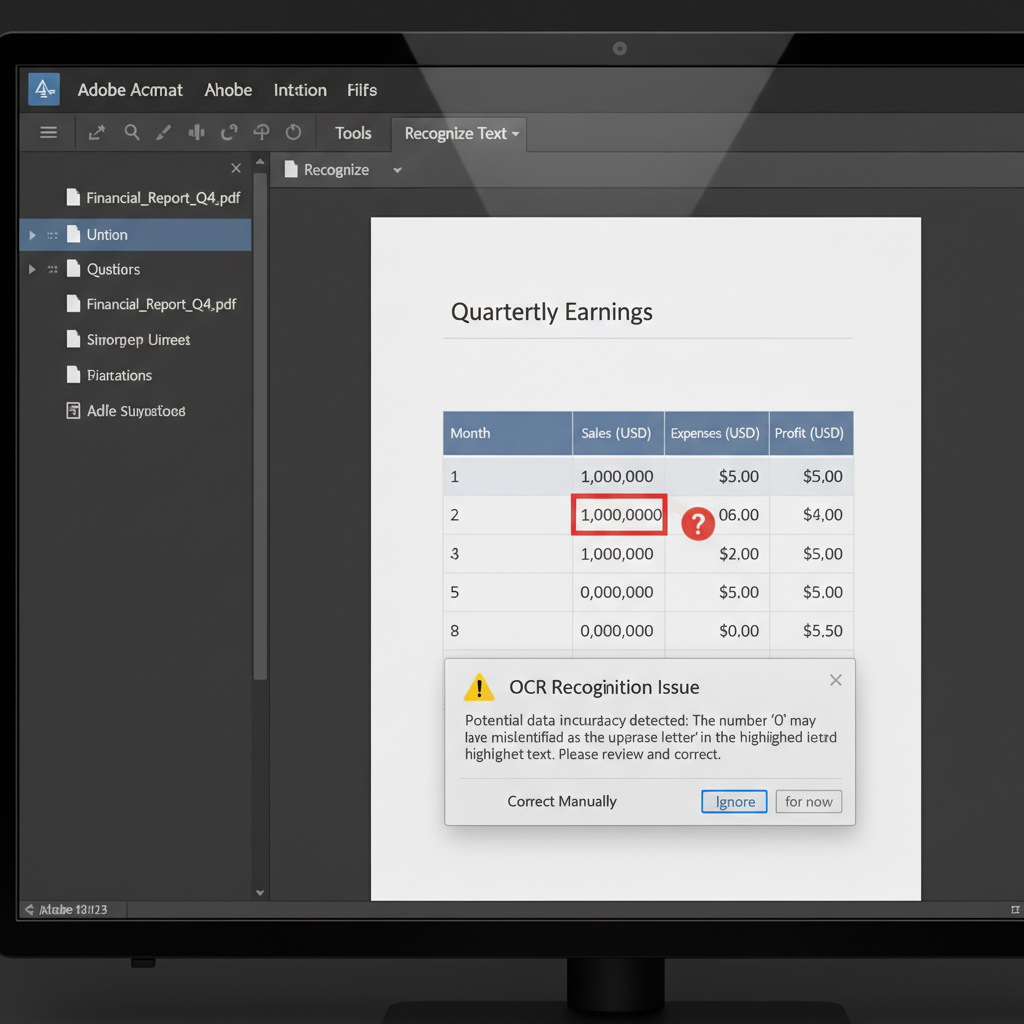
Users report that Adobe Acrobat misidentifies the number zero (0) as the uppercase letter 'O' when recognizing or displaying text in PDF files.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Performing Optical Character Recognition (OCR) on scanned PDF documents or simply viewing text within a PDF.
- Observed behavior
- The software substitutes the number zero with the letter 'O', which causes data inaccuracies, especially in financial documents or numerical lists.
Determine whether this character substitution happens across all your PDF files or is isolated to a specific scanned document, and ensure your Acrobat software is fully updated.
Optimize OCR Settings and Scan Quality
Adjust your text recognition settings and ensure high-quality source images to help the software distinguish similar characters.
Character confusion often stems from low-resolution scans or mismatched language settings. By improving the source quality and verifying OCR parameters, you can significantly reduce character substitution errors.
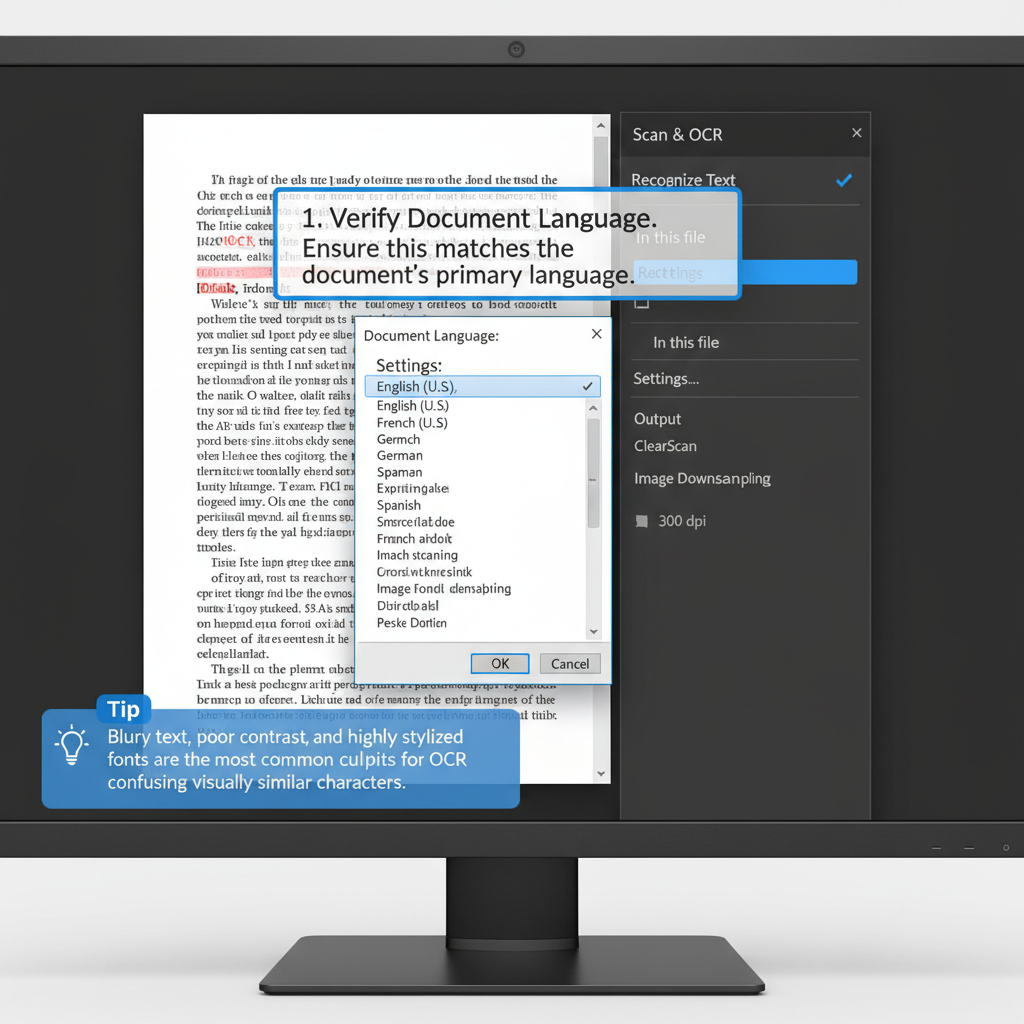
Open the 'Scan & OCR' tool in Adobe Acrobat, select 'Recognize Text', and ensure the selected OCR language perfectly matches the primary language of your document.
If you are scanning a physical document, configure your scanner's resolution to at least 300 DPI (Dots Per Inch) before creating the PDF.
When generating a PDF from a source application like Word, use a font where the number zero is easily distinguishable from the letter 'O' (such as Consolas or a font with a slashed zero).
Manually Correct OCR Suspects
Use Acrobat's built-in text correction tool to manually identify and fix incorrectly recognized characters.
Use WPS Office for Highly Accurate PDF OCR
If Acrobat continues to misread characters, try the WPS PDF OCR tool. WPS Office provides an advanced, highly accurate OCR engine that perfectly distinguishes similar characters like zeros and letter O's, ensuring your data remains precise.
- 1. Open PDF in WPS: Launch WPS Office and open your scanned PDF document using the built-in WPS PDF viewer.
- 2. Select the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Choose Extraction Method: Select whether you want to extract the text directly on screen or convert the document into an editable Word or Excel file.
- 4. Confirm Settings and Run: Set the appropriate document language and click 'Start' to perform highly accurate text recognition.
Frequently Asked Questions
Why does OCR software confuse the number zero and the letter O?
OCR (Optical Character Recognition) software analyzes the geometric shapes of characters. Because the number '0' and the uppercase letter 'O' share almost identical oval shapes in many standard fonts, lower resolution scans or poor contrast can cause the engine to misinterpret the character.
Does changing the document font before converting to PDF help?
Yes. If you have access to the original source document, changing the font to a monospaced font or one with a slashed zero (like Consolas or Monaco) significantly improves OCR accuracy when the document is later scanned or processed.
Can I fix OCR character errors in a locked PDF?
No. You cannot edit, run OCR, or correct text in a PDF that has security restrictions preventing editing. You must first unlock the PDF using the correct permissions password provided by the document owner.


