



How to Fix PDF Converting to Word or Excel as Gibberish
Question details
Users need to resolve an issue where converting a PDF file into editable formats results in unrecognizable text.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
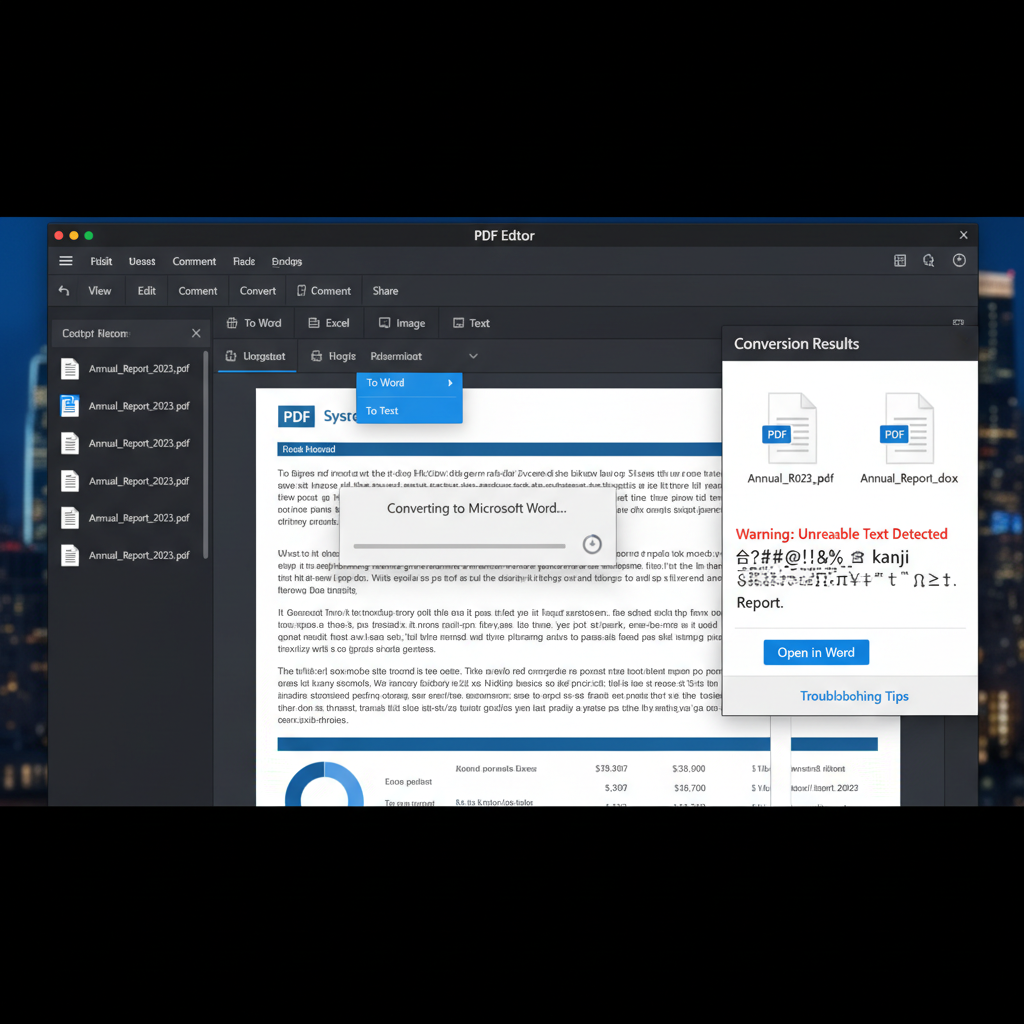
- Exporting or converting a PDF document into Microsoft Word or Excel formats.
- Observed behavior
- The converted Word or Excel document displays gibberish, incorrect symbols, or foreign language characters instead of the original text.
Before attempting another conversion, open the original PDF in your standard PDF reader to ensure the text displays correctly and the document is not inherently corrupted.
Use Optical Character Recognition (OCR) Before Exporting
Running OCR extracts actual text from scanned or improperly encoded PDFs, overriding damaged character mapping during the conversion process.
Gibberish text often occurs because the PDF was created by unsupported software that failed to include proper character encoding. Even though the text looks correct on screen, the underlying data is garbled. Utilizing an OCR tool forces the software to read the shapes of the letters rather than relying on the corrupted underlying code.
Launch your PDF editor (such as Adobe Acrobat) and open the problematic PDF document.
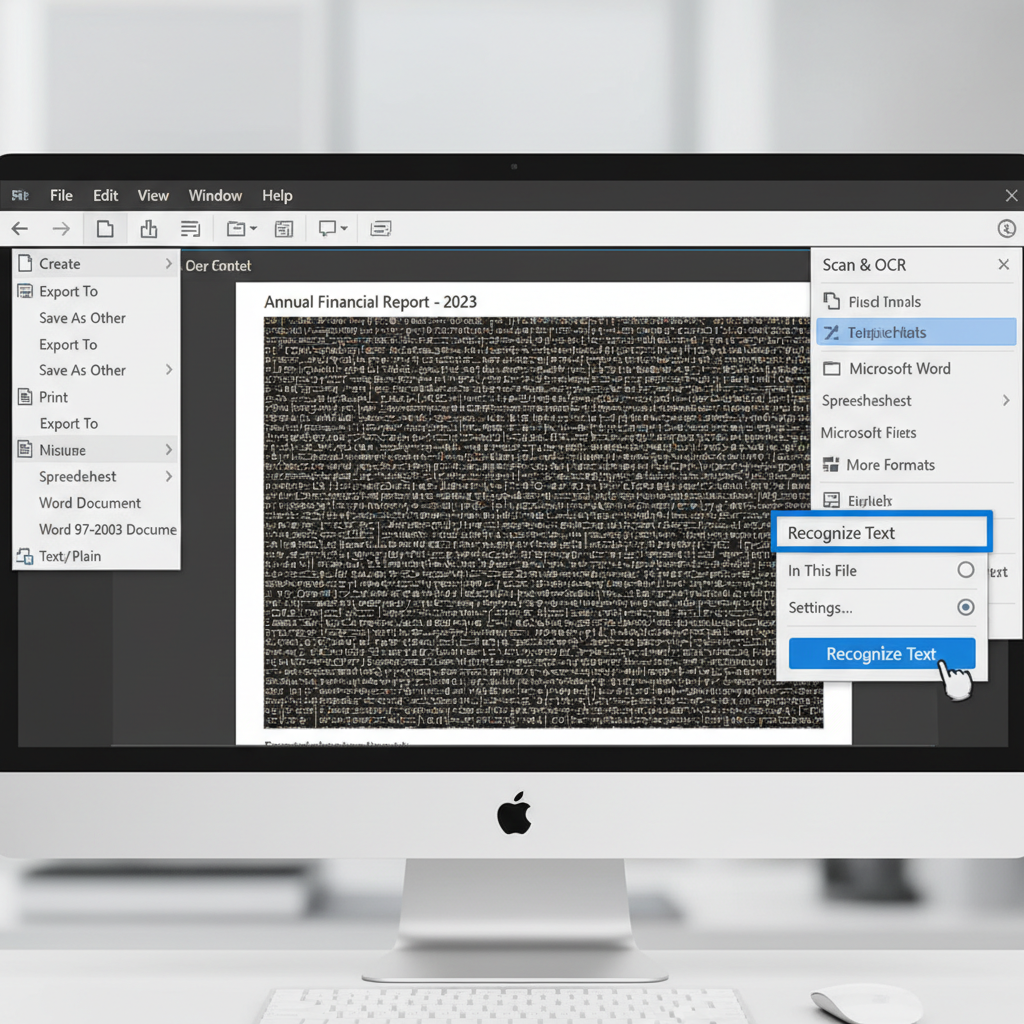
Navigate to the 'Scan & OCR' or 'Recognize Text' tool from the right-hand pane or the Tools menu.
Select 'In This File' and click 'Recognize Text' to allow the software to scan the document and rebuild the readable text layer.
Once the OCR process is complete, go to File > Export To > Microsoft Word (or Excel) to perform the conversion again.
Fix Missing Embedded Fonts
Verifying and embedding missing fonts ensures that custom typography is preserved during the conversion rather than being substituted with random symbols.
Convert PDFs Accurately with WPS Office
WPS Office features an advanced PDF conversion tool with built-in OCR technology. It seamlessly reads and converts complex PDFs, preventing character encoding issues and ensuring your text exports perfectly to Word or Excel.
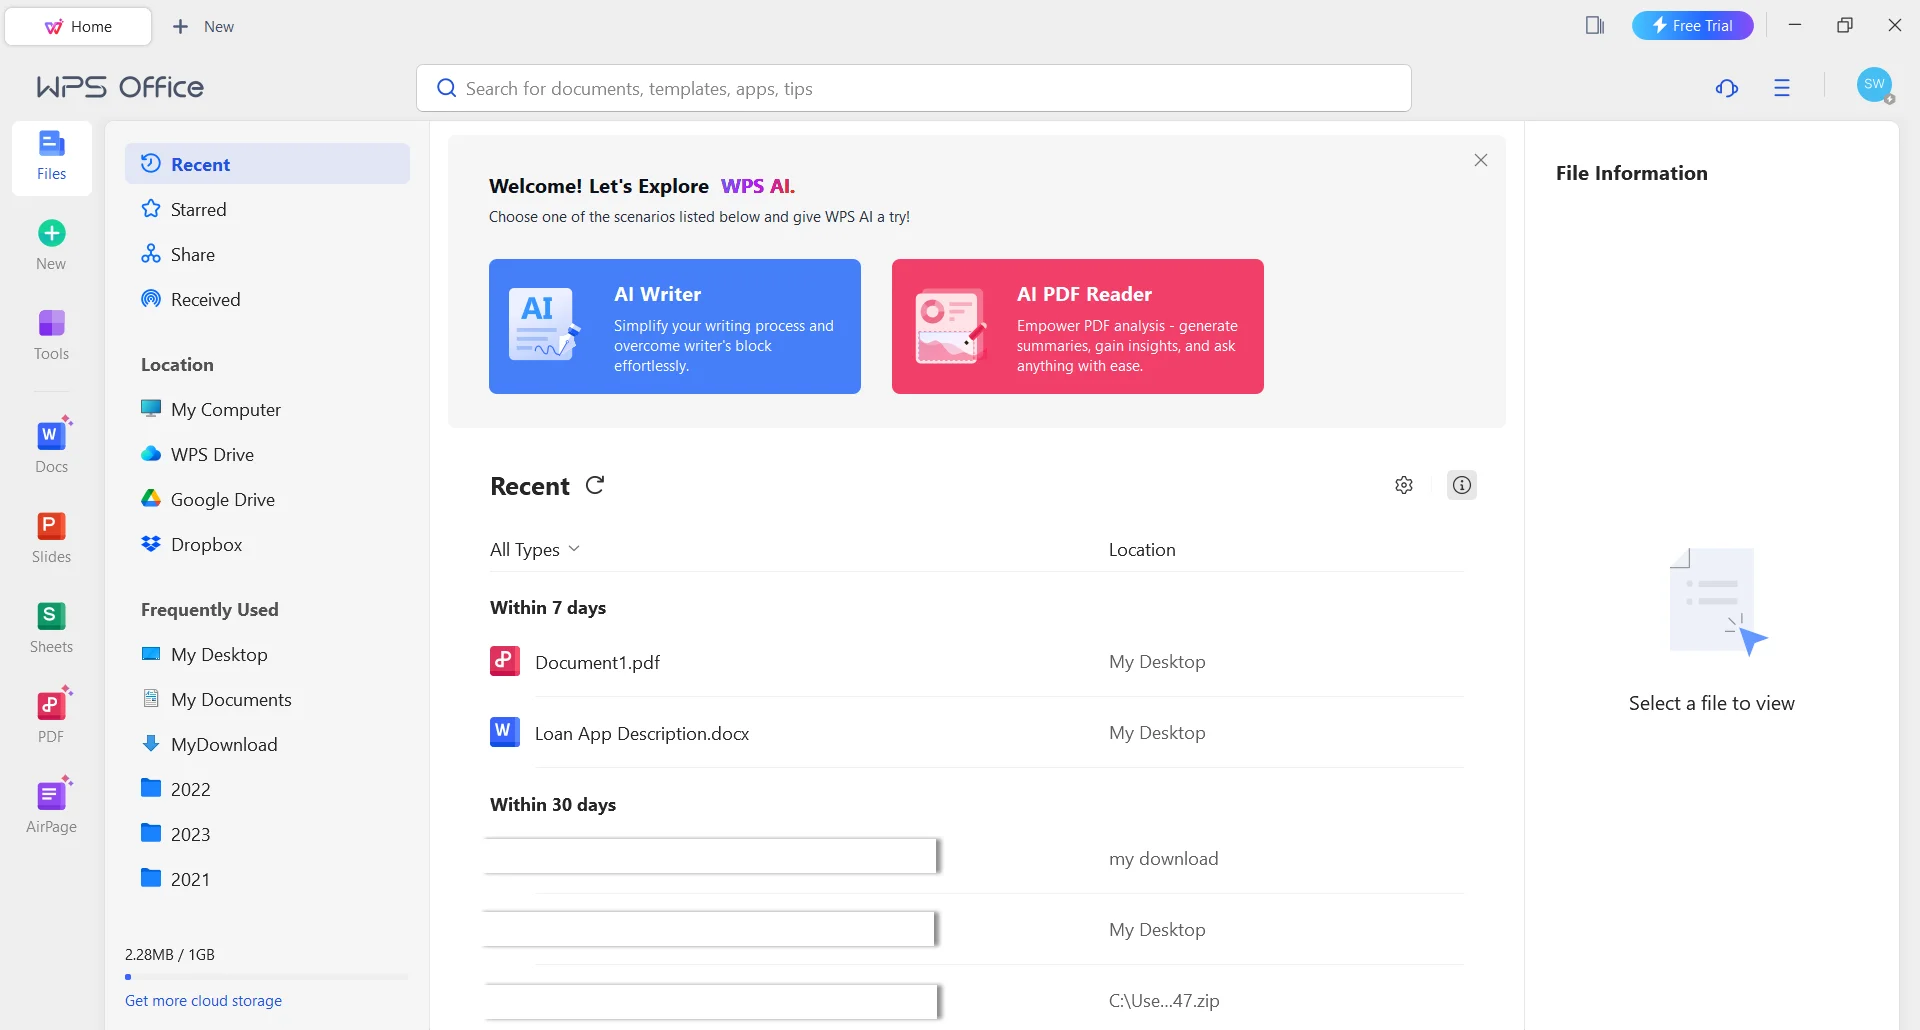
- 1. Open PDF in WPS Office: Launch WPS Office and open your problematic PDF file using the WPS PDF application.
- 2. Select the Conversion Tool: Navigate to the 'Tools' tab on the top ribbon and select 'PDF to Word' or 'PDF to Excel' depending on your needs.
- 3. Enable OCR: In the conversion dialog box, ensure that the OCR option is enabled to accurately recognize and extract the text.
- 4. Convert and Save: Click 'Start' to begin the conversion. The newly generated, error-free document will open automatically for editing.
Frequently Asked Questions
Why does my PDF text turn into symbols when I copy and paste it?
This happens when the PDF contains subset fonts without a proper character map (Unicode mapping). While the PDF viewer knows how to draw the shape of the letters on the screen, the computer cannot interpret what letters they actually are, causing clipboard copies and conversions to output symbols.
Can I fix the gibberish text in the already converted Word document?
No. Once the text has been converted into gibberish in Word or Excel, the original character data is lost. You must fix the encoding issue in the original PDF or use a converter with an OCR feature to reconvert the file.
Does OCR work for documents containing foreign languages?
Yes, most advanced OCR tools support multiple languages. However, you must explicitly select the correct language in the OCR settings before processing the PDF to ensure the software applies the correct alphabet and dictionary, preventing gibberish output.


