



How to Scan Documents for Blank or Completed Fields
Question details
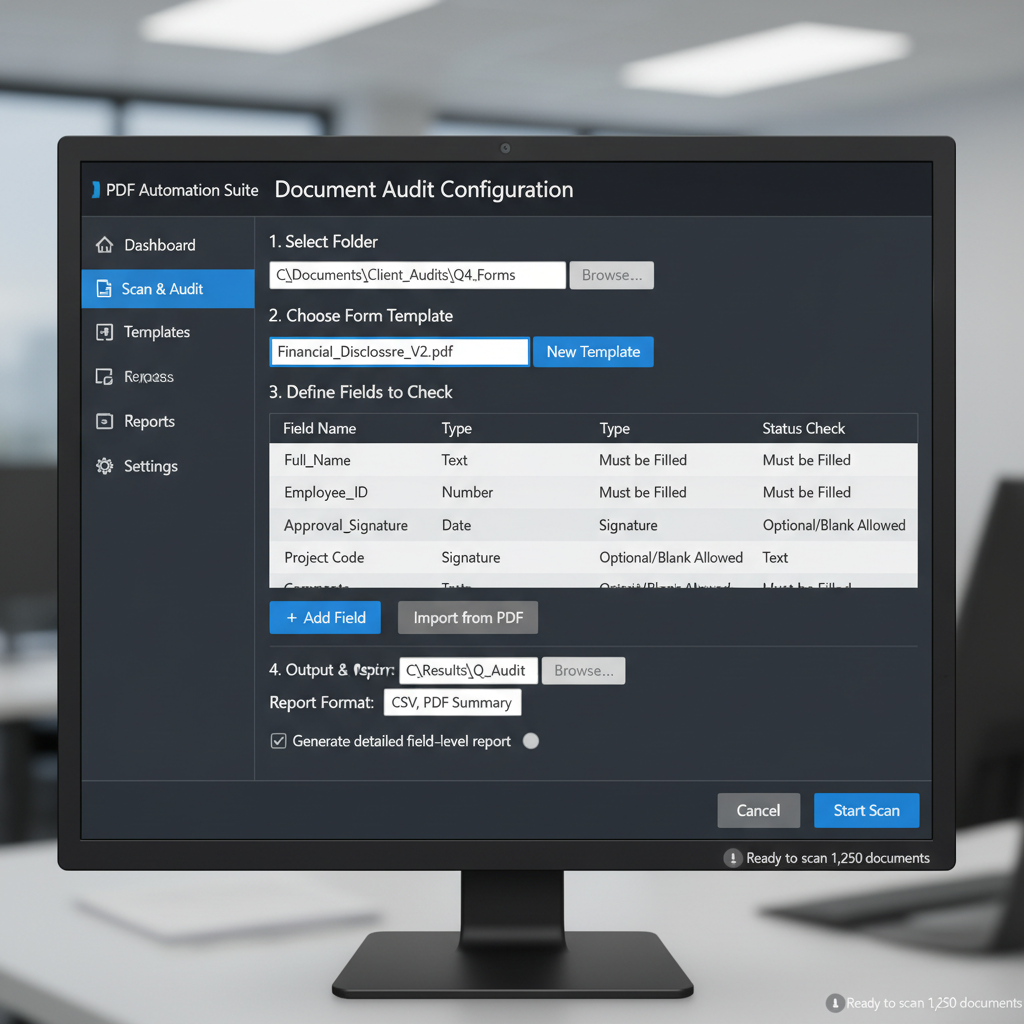
The user needs a software solution to scan folders of documents to identify whether specific form fields are filled in or left blank, typically for high-volume document audits.
- Product
- PDF Automation Software
- Device & OS
- not provided
- Scenario
- Conducting high-volume document audits requiring automated checks to verify if required form fields are completed or empty.
- Observed behavior
- Needs to efficiently locate specific fields and determine their completion status across multiple files without manual review.
Before setting up an automated scanning process, sort your files into two categories: interactive PDF forms (AcroForms) and flattened/scanned image documents, as they require entirely different processing methods.
Extract Data from Interactive PDF Forms (AcroForms)
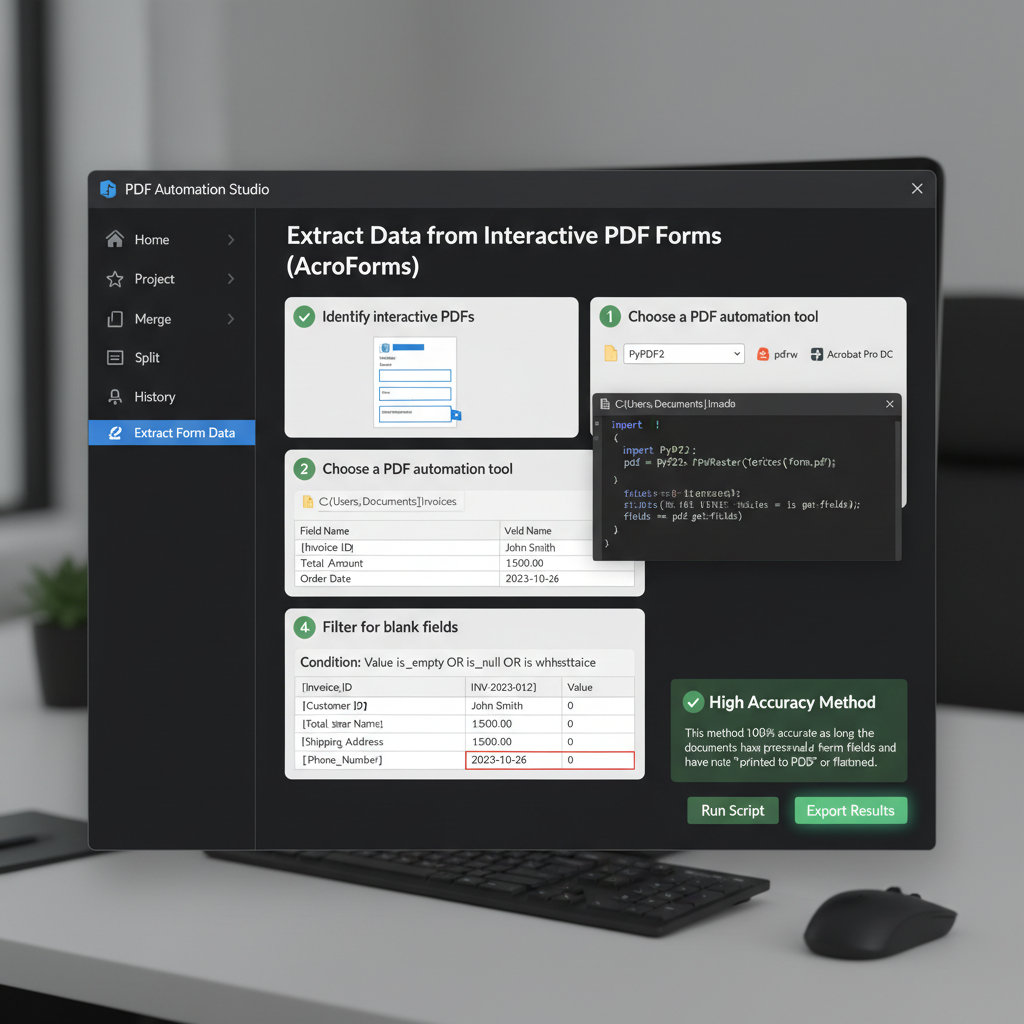
Use PDF automation tools or scripts to read the internal data structure of interactive PDF forms directly, making it easy to spot empty variables.
Interactive PDFs store form data in clearly defined fields (AcroForms). Since the data is stored as text variables, you do not need OCR. An automation script can read these variables in milliseconds.
Open a sample document on your computer and click on the form fields to ensure they are active, clickable, and highlightable.
Select a commercial PDF data extraction software or utilize a Python scripting library (such as PyPDF2 or pdfrw) designed to parse AcroForm data.
Configure the tool or script to target your specific folder and extract the dictionary of field names along with their corresponding text values.
Set your tool's logic to flag any file where the required field variables return an empty string, null value, or just whitespace.
Use OCR for Scanned Documents and Flattened PDFs
Employ Optical Character Recognition (OCR) and Intelligent Document Processing (IDP) to visually locate fields and detect entered text or handwriting.
Manage and Extract PDF Forms Efficiently with WPS Office
WPS Office includes powerful PDF tools to handle interactive forms, perform advanced OCR on scanned documents, and convert form data into Excel spreadsheets for incredibly easy auditing.
- 1. Open your PDF in WPS Office: Launch WPS Office and open your interactive PDF form or scanned document.
- 2. Interact with Form Fields: Navigate to the 'Form' tab to interact with form fields, ensuring the document is properly structured.
- 3. Apply OCR to Scanned Files: If the document is a flattened image, click 'OCR' on the Tools tab to convert the image into searchable and selectable text.
- 4. Convert to Excel for Easy Auditing: Go to the 'Tools' tab and select 'PDF to Excel' to export the data. Once in Excel, you can use standard filters to instantly highlight blank cells.
Frequently Asked Questions
Can I check for blank fields in a PDF without writing any code?
Yes, many dedicated Intelligent Document Processing (IDP) tools and comprehensive PDF editors allow you to export form data directly to CSV or Excel. Once the data is in a spreadsheet, you can simply use the 'Filter' feature to find all blank rows without needing to write automation scripts.
Why are my filled PDF fields showing as blank during extraction?
This usually happens if the PDF form was 'flattened' prior to you receiving it. Flattening merges the form field data into the background image of the document, stripping away the interactive variables. To read this data, you will need to switch from AcroForm extraction to an OCR-based extraction method.
Does OCR software work well with handwritten form fields?
OCR accuracy varies significantly with handwriting. While modern AI-driven OCR tools can read neat, block-letter handwriting fairly well, they struggle with cursive or messy writing. It is highly recommended to include a manual review step for any documents containing handwritten inputs.


