



Fix PDF to Word Converter Exporting Scanned PDFs as Images
Question details
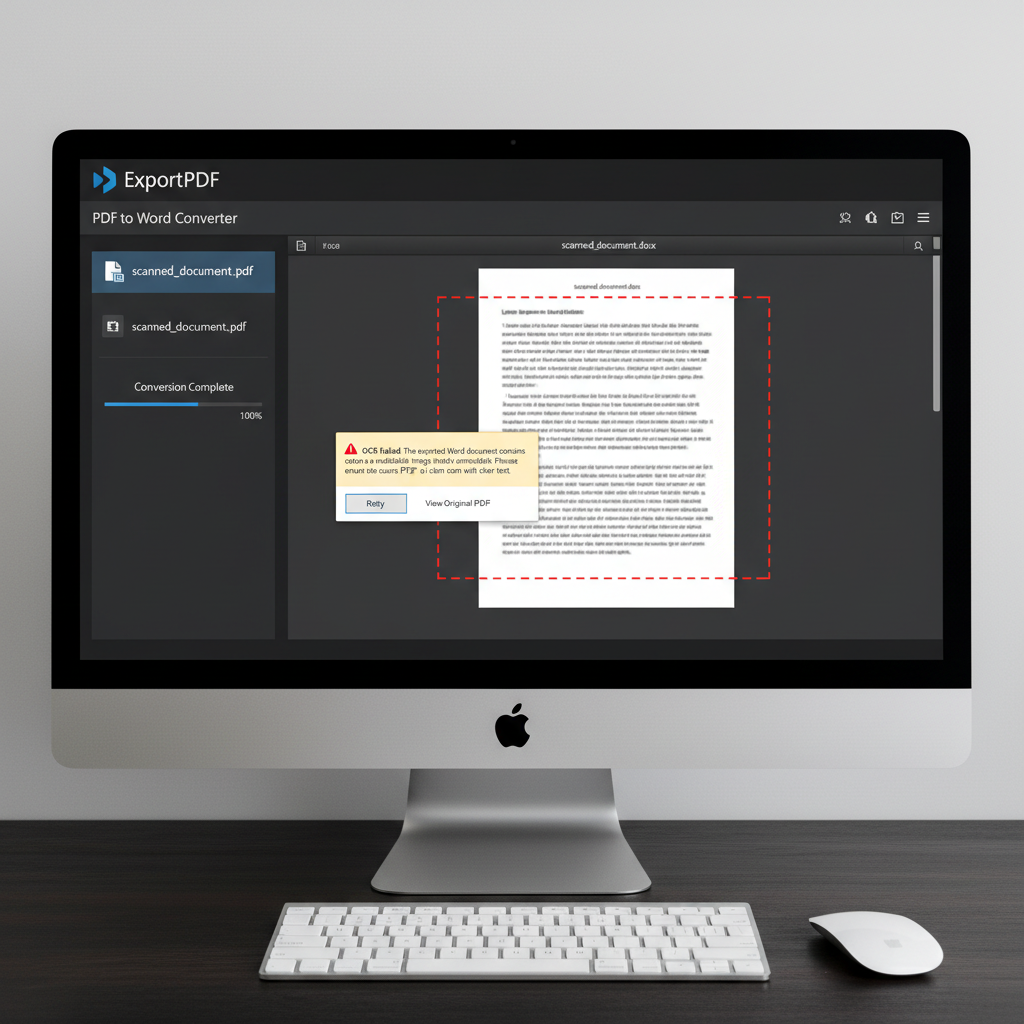
The user is trying to convert a scanned PDF to a Word document, but the output results in an uneditable image instead of extractable text.
- Product
- ExportPDF
- Device & OS
- not provided
- Scenario
- Converting a scanned document to an editable Word file using Optical Character Recognition (OCR).
- Observed behavior
- The resulting Word document contains a static picture instead of editable text, indicating that the OCR process failed or was bypassed during conversion.
Ensure your original scanned document has high contrast and is readable. Avoid cropping or heavily editing the raw scanned image in third-party software before converting it to a PDF.
Use the Unedited Original Scan for Conversion
Using a raw, unedited scan prevents OCR recognition failures caused by manual image manipulations like removing lines or handwriting.
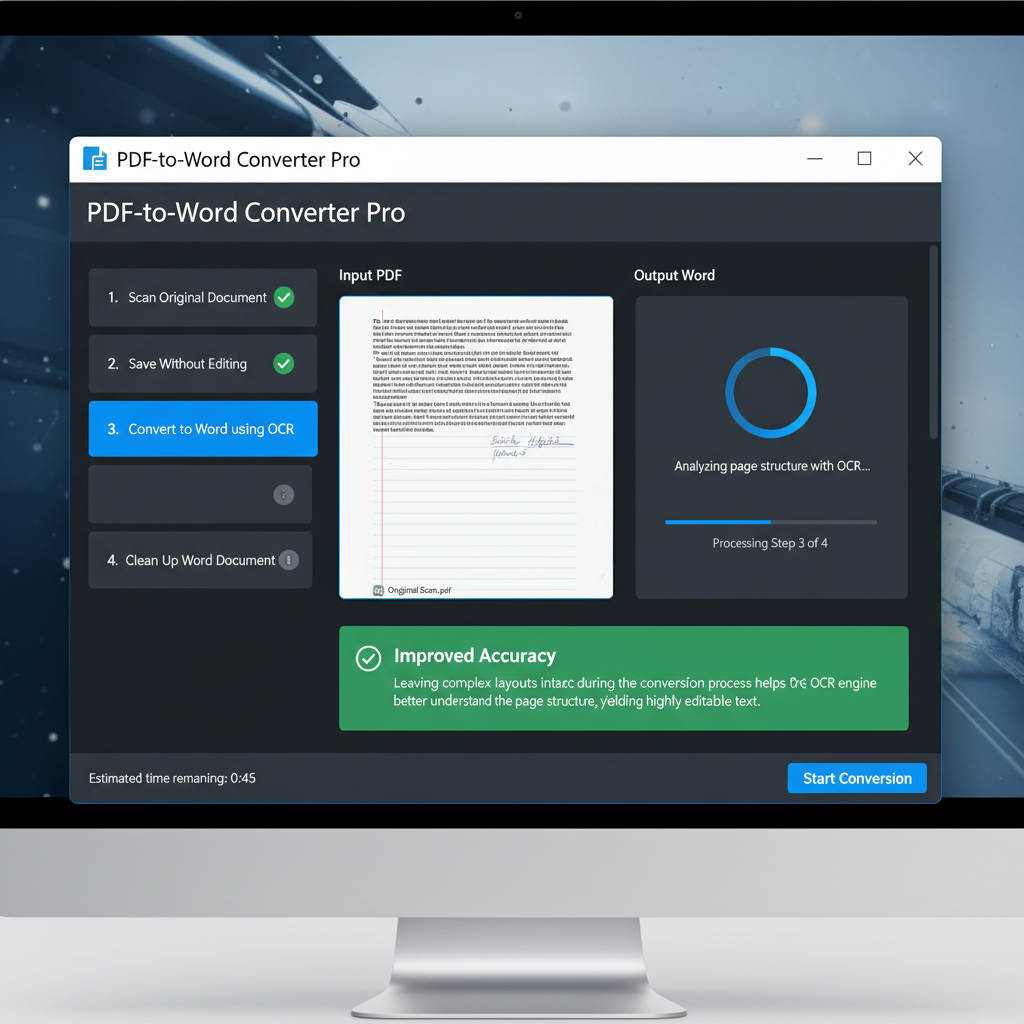
Many users try to clean up a scanned image by removing pictures, handwritten notes, or lines in an image editor before turning it into a PDF. However, this preprocessing can sometimes break the OCR functionality of PDF converters, causing them to insert the entire page as a static image in Word.
Scan your physical document at a high resolution (at least 300 DPI) to ensure the text is crisp and legible.
Save the raw scan directly as a PDF file. Do not use image editing tools to erase lines, borders, or pictures.
Upload this complete, unedited PDF to your PDF-to-Word converter and run the conversion process.
Once the document is successfully converted into editable text, open it in Microsoft Word or WPS Writer to manually delete any unwanted lines, pictures, or notes.
Enable OCR Settings and Select the Correct Language
OCR must be explicitly enabled and configured with the correct language to extract text from images.
Convert Scanned PDFs to Editable Text with WPS Office
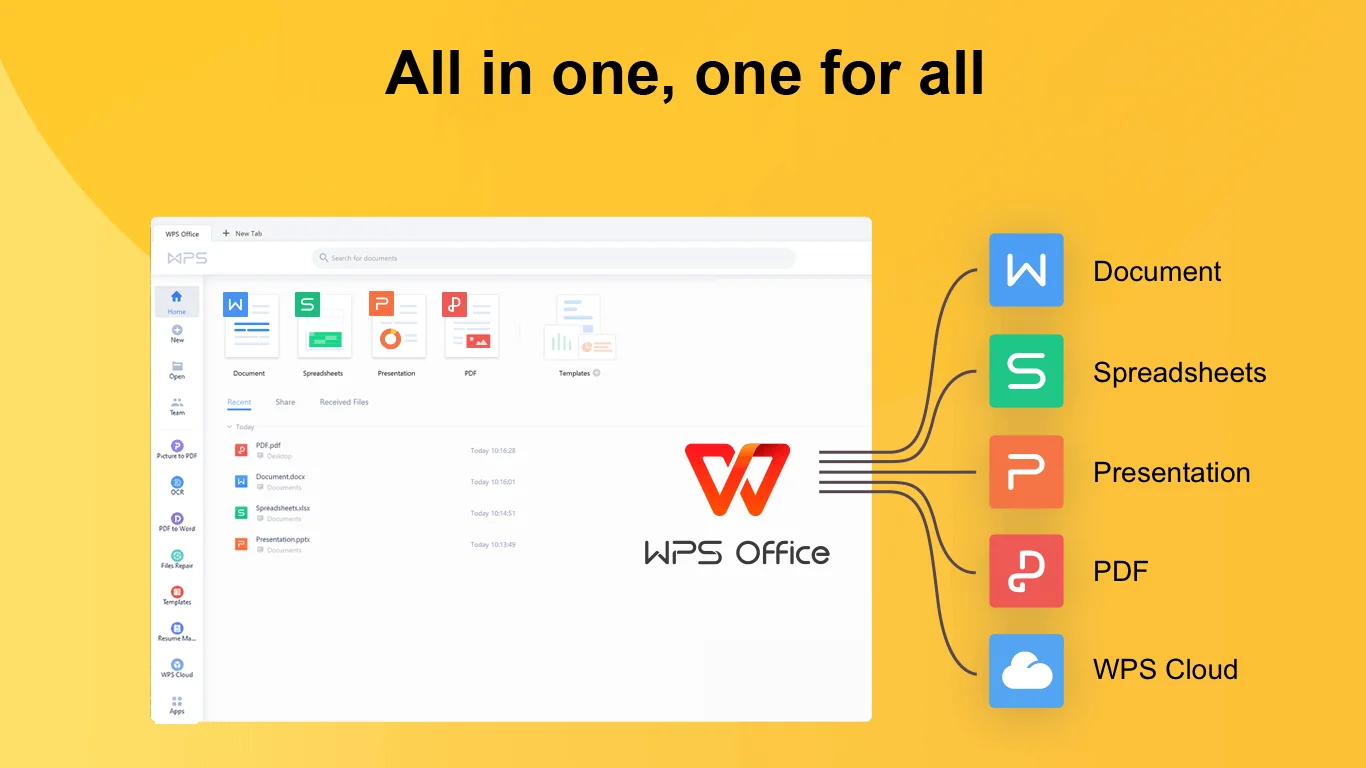
WPS Office features a powerful built-in PDF to Word converter equipped with advanced OCR technology. It seamlessly extracts text from scanned documents and images, preserving the original layout while making the content fully editable without complex workarounds.
- 1. Open the PDF: Launch WPS Office and open your scanned PDF document.
- 2. Select PDF to Word: Navigate to the 'Tools' tab on the top ribbon and click on the 'PDF to Word' button.
- 3. Enable OCR: In the conversion dialog box, ensure that the OCR function is toggled on and select the correct document language.
- 4. Convert and edit: Click 'Start'. The document will be converted and automatically opened as a fully editable Word file.
Frequently Asked Questions
Why does my converted Word document only show a picture?
If your PDF was created from a scanner or a photograph, the text is embedded as a flat image layer. If the Optical Character Recognition (OCR) feature is not enabled or fails during conversion, the software will simply paste that flat image into the Word document instead of extracting editable text.
How can I improve OCR accuracy for scanned PDFs?
To improve OCR results, ensure your original scan is straight, clear, and has high contrast (such as black text on a white background). Avoid pre-editing the image to erase elements, and always make sure the correct text language is selected in your converter's OCR settings.
Can I remove unwanted handwriting or lines during the PDF to Word conversion?
It is not recommended to alter the original image to remove handwriting or lines before conversion, as this can confuse the OCR engine. Instead, convert the raw scan to Word first, and then manually delete the unwanted elements within your word processor.
Does WPS Office support OCR for multiple languages?
Yes, WPS Office's PDF tools support multi-language OCR recognition. Selecting the appropriate language before running the PDF to Word conversion ensures special characters and text are accurately recognized and formatted.


