



How to Fix Converted Word Document Appearing as an Uneditable Image
Question details
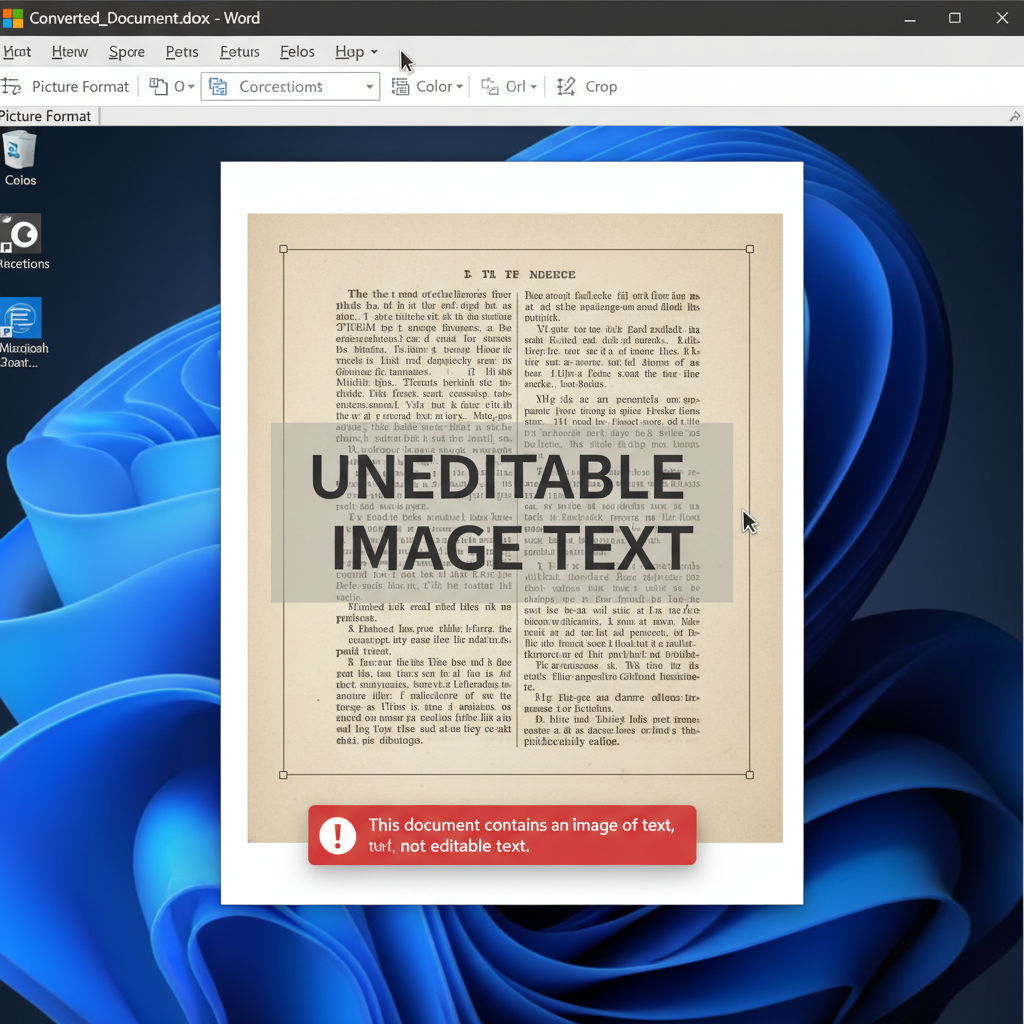
The user converted a scanned PDF to a Word document, but the resulting file behaves like a static image without any editable text.
- Product
- Adobe Export PDF / Microsoft Word
- Device & OS
- not provided
- Scenario
- Converting a scanned, image-based PDF document into an editable Microsoft Word file.
- Observed behavior
- The converted Word document contains an uneditable image of the PDF pages instead of selectable and editable text.
Before troubleshooting, open the original PDF file and try to highlight the text with your cursor. If the text cannot be selected, the PDF is an image-based scanned file that requires Optical Character Recognition (OCR) before or during conversion.
Run OCR Before Converting to Word
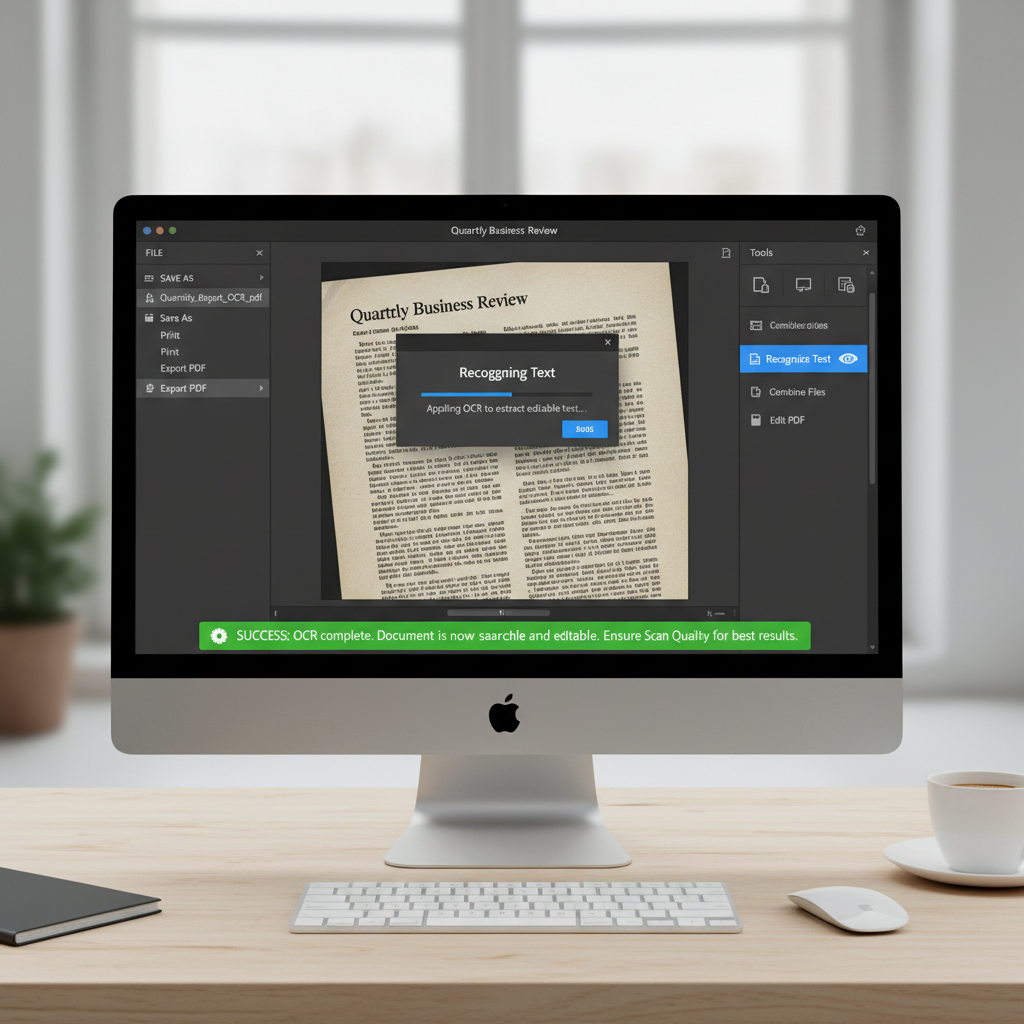
Applying Optical Character Recognition (OCR) extracts readable text from scanned images, ensuring the converted Word document is fully editable.
Standard PDF to Word conversion tools simply translate the existing format of the PDF. If the PDF contains only an image of a scanned document, the resulting Word file will also contain just an image. Using an OCR tool processes the image, recognizes the characters, and creates a hidden text layer that allows the content to be edited.
Launch your PDF editor (such as Adobe Acrobat Pro) and open the scanned PDF document.
Navigate to the 'Tools' menu and select 'Recognize Text' or 'Scan & OCR' depending on your software version.
Wait for the OCR process to complete, then go to 'File' > 'Save As' to save the newly searchable PDF file.
Use the 'Export PDF' function to convert this new OCR-processed file into a Microsoft Word document.
Verify PDF Properties and Structure
Check the source of the PDF to ensure it wasn't created by a third-party tool that improperly structures or flattens text.
Easily Convert Scanned PDFs to Editable Word Documents
WPS Office includes a built-in OCR engine that accurately recognizes text from scanned PDFs and directly converts them into fully editable Word documents in one simple step, saving you the hassle of manual transcription or multi-step processes.
- 1. Open PDF to Word converter: Launch WPS Office, navigate to the 'PDF' tab, and click on 'PDF to Word'.
- 2. Add your scanned PDF: Click 'Add Files' or drag and drop your scanned PDF document into the converter window.
- 3. Enable OCR: Ensure the 'OCR' setting is checked so the software knows to extract text from the images.
- 4. Start the conversion: Click the 'Convert' button. Once finished, your new, fully editable Word document will open automatically.
Frequently Asked Questions
Why does my converted Word document look like a picture?
When you convert a scanned PDF, the converter reads the page as a single flat image. Unless the conversion software uses OCR (Optical Character Recognition) to extract the text, the result in Word will remain an uneditable picture of the document.
What is OCR and why do I need it?
OCR stands for Optical Character Recognition. It is a technology that scans images of text (such as a scanned document or photograph) and translates them into machine-readable, editable text characters, which is required when converting image-based PDFs to Word.
Can I edit the text if I triple-click the image in Word?
Sometimes, if the conversion layered hidden text behind the image, triple-clicking might highlight usable text. However, for true scanned images without an underlying text layer, this will not work, and you must process the file through an OCR tool.
Does the quality of the scan affect the conversion?
Yes. Poor resolution, blurry text, handwriting, or slanted pages make it difficult for the OCR engine to accurately recognize characters. This may result in missing text, typos, or gibberish in the converted Word document.


