



How to Fix Poor OCR Results When Editing Scanned PDFs
Question details
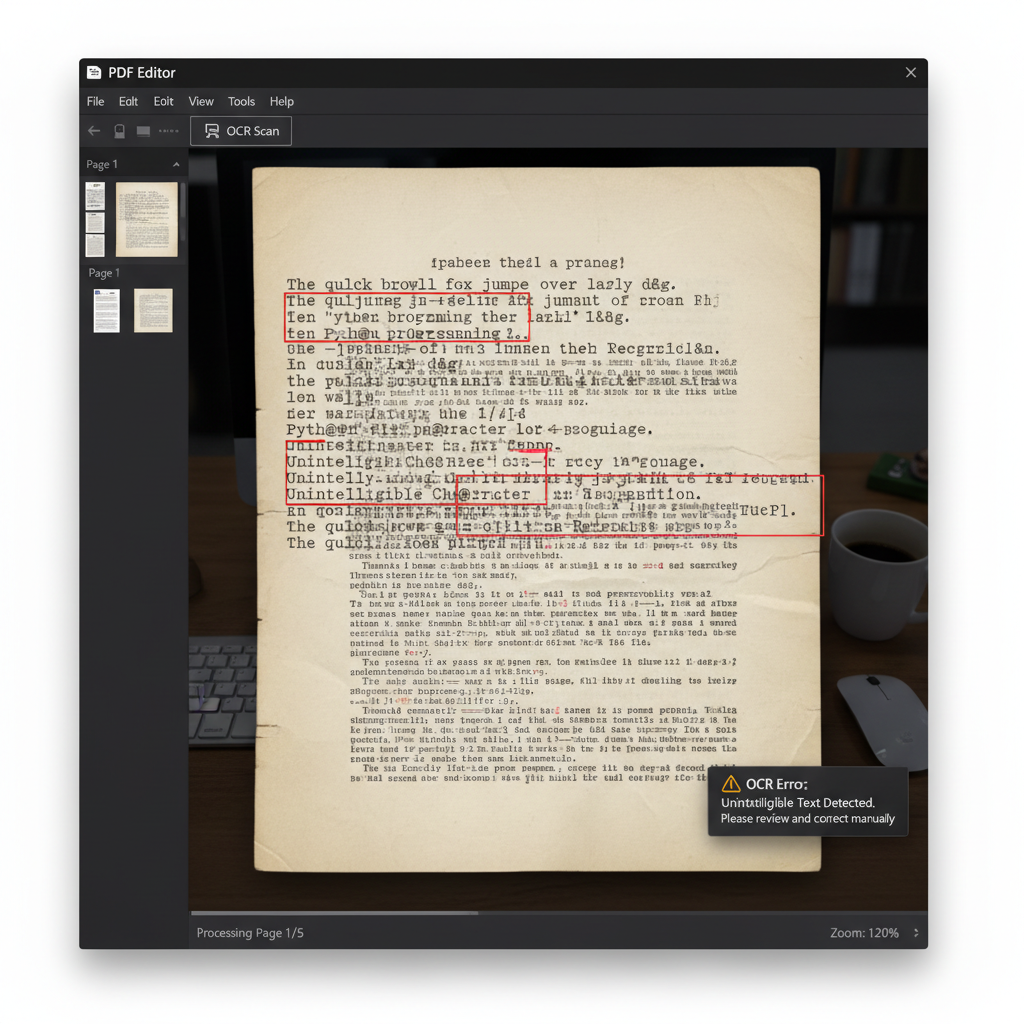
The user experienced poor and unintelligible text results when using OCR to edit a scanned PDF document.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Attempting to edit a scanned PDF document using Optical Character Recognition (OCR) software.
- Observed behavior
- The OCR engine converts the scanned document into unintelligible text, making accurate editing impossible.
Before re-running OCR on your document, check the original scanned file to ensure the text is legible, not blurry, and has high contrast against the background.
Enhance Scan Quality Before Applying OCR
The most common reason for unintelligible OCR text is poor scan clarity. Improving the source image resolves most OCR issues.
OCR engines rely entirely on the visual clarity of the text. If the source document has low resolution, dark edges, or uneven lighting, the software will struggle to recognize character shapes properly, leading to gibberish output.
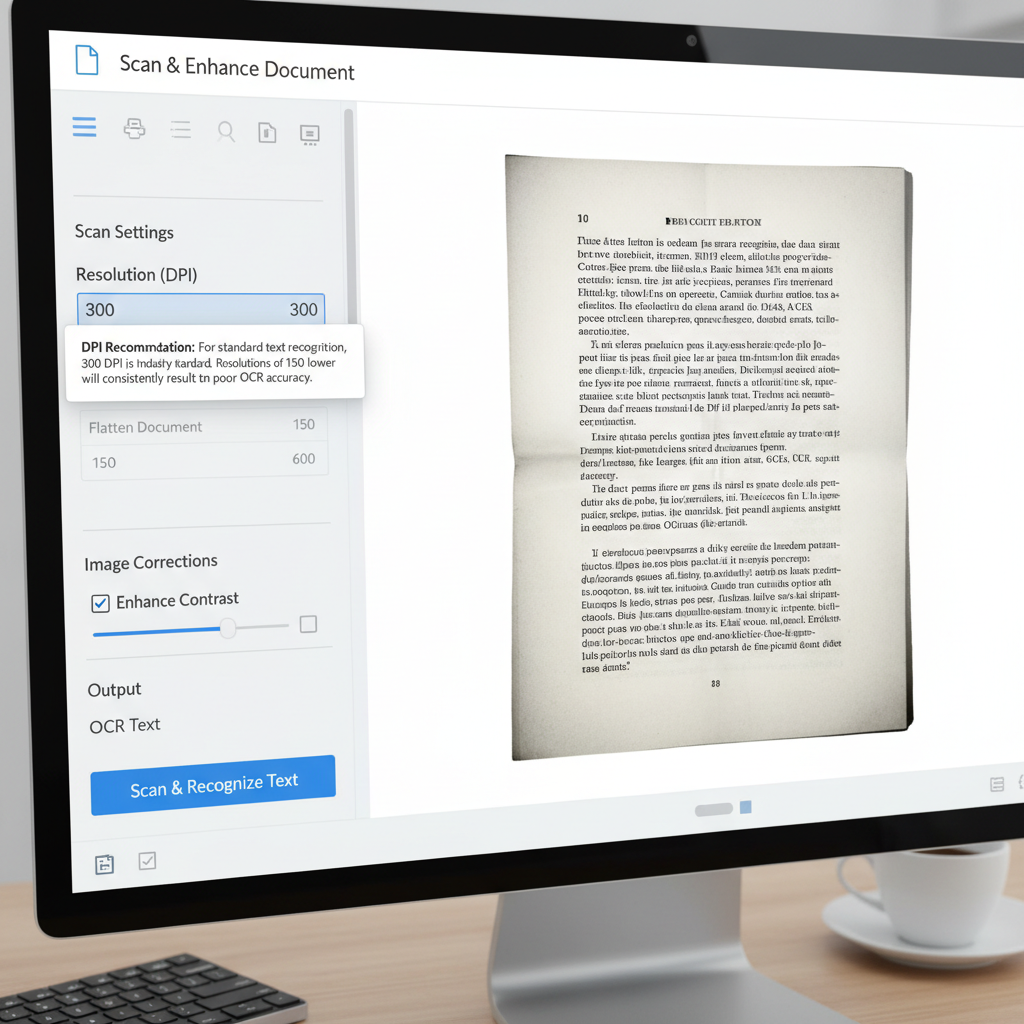
Ensure that the original document was scanned at a minimum of 300 DPI (Dots Per Inch). If the resolution is lower, re-scan the physical document.
When scanning from a book or folded paper, ensure the page is pressed completely flat against the scanner glass to avoid shadow gradients.
Use a basic image editor or scanner software settings to increase the contrast, making the text completely black and the background pure white.
Adjust OCR Language and Layout Settings
Incorrect OCR settings, such as selecting the wrong document language or a layout mode that doesn't fit the document, can severely confuse the text recognition engine.
Use WPS PDF for High-Accuracy OCR and Easy Editing
WPS PDF features advanced Optical Character Recognition (OCR) technology to accurately convert scanned documents and images into fully editable, searchable text, saving you the hassle of manual retyping.
- 1. Open the scanned PDF: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and select the 'OCR' button.
- 3. Choose extraction method: Choose between 'Extract Text' for plain text copying or 'Convert to Editable Document' to preserve the layout.
- 4. Start text recognition: Select the document language and click 'Start' to begin the high-accuracy text recognition process.
Frequently Asked Questions
Why does my OCR output look like gibberish?
Gibberish or unintelligible text typically happens when the original scan is blurry, the resolution is below 300 DPI, or the wrong recognition language is selected in your PDF editor's OCR settings.
Can OCR recognize handwritten text in a scanned PDF?
Standard OCR is designed for printed text and struggles significantly with handwriting. If your document contains cursive or uneven handwriting, the OCR engine is likely to convert it into incorrect or unintelligible characters.
How can I edit a scanned PDF without OCR?
Without OCR, a scanned PDF is treated as a flat image by the computer. To edit the text, you must either use an OCR tool to convert the image into editable text, or manually retype the content from scratch.
Does WPS Office support OCR for scanned PDFs?
Yes, WPS Office includes a robust OCR feature built right into its PDF tool. It can extract text from scanned PDFs and images, allowing you to convert them directly into editable Word documents or searchable PDFs.


