

Improve OCR Accuracy for Scanned Cyrillic PDFs to Word Conversion
Question details
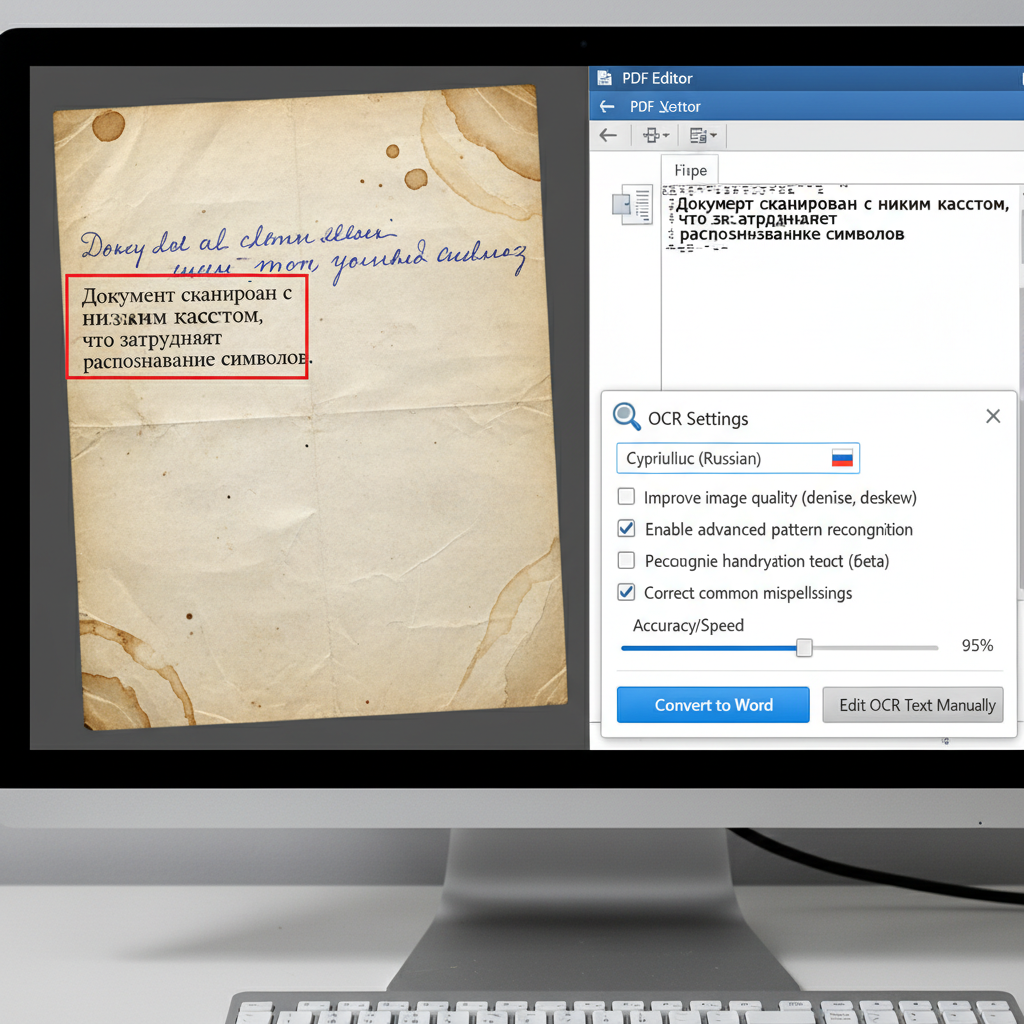
The user needs to improve the accuracy of OCR (Optical Character Recognition) when converting scanned PDF documents containing Cyrillic text into Word files.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Converting scanned, handwritten, or poorly printed Cyrillic PDF documents into editable Word formats.
- Observed behavior
- The resulting Word document contains inaccurate text recognition, primarily due to low-quality scans or complex original text formats.
Ensure your scanned document is saved in a high-resolution format (at least 300 DPI) before attempting OCR conversion, as image clarity directly impacts text recognition accuracy.
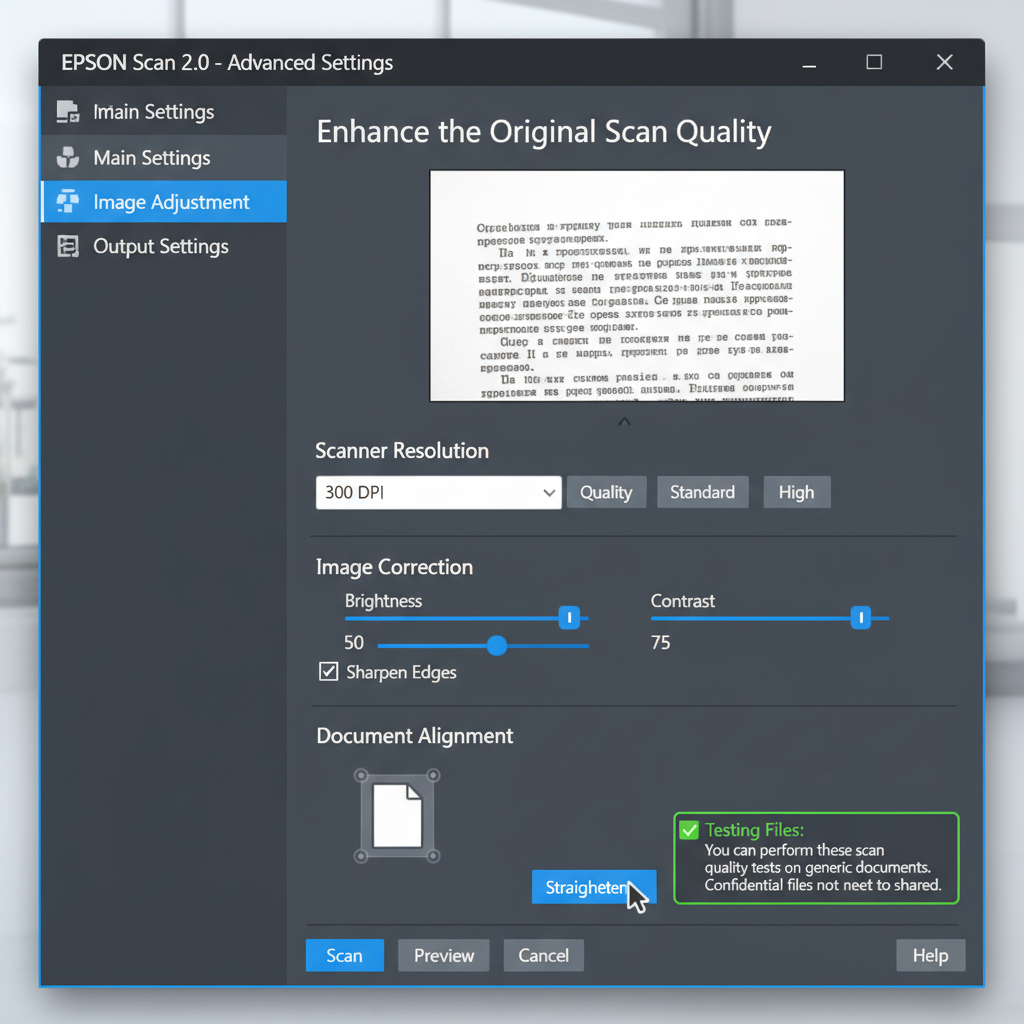
Enhance the Original Scan Quality
Optimizing the physical scan is the most effective way to improve OCR accuracy for complex alphabets like Cyrillic.
OCR accuracy is heavily dependent on the clarity of the source image. Handwritten or poorly printed text can confuse recognition algorithms, so giving the OCR engine the cleanest possible image is crucial.
Set your scanner resolution to a minimum of 300 DPI (Dots Per Inch) to capture clear character edges.
Adjust the contrast and brightness settings on your scanner software to make the dark Cyrillic text stand out distinctly against the white background.
Ensure the paper is perfectly aligned in the scanner. Skewed or tilted text significantly reduces OCR precision.
Test Alternative OCR Engines or Language Settings
Different OCR applications use varying algorithms; some are better optimized for specific regional languages.
Extract Text from Scanned PDFs with WPS Office
WPS Office includes a powerful built-in OCR engine that supports multiple languages. It efficiently converts scanned PDFs and images into editable Word documents while preserving the original layout.
- 1. Open the Scanned PDF: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab and click on the 'OCR' button or select 'PDF to Word' from the top menu.
- 3. Set the Recognition Language: In the OCR settings prompt, ensure the recognition language is set to match the Cyrillic language of your document for optimal accuracy.
- 4. Convert and Edit: Click 'Convert' or 'Extract Text' to process the file. Once finished, the editable Word document will open automatically.
Frequently Asked Questions
Why is handwritten Cyrillic text difficult for OCR to convert?
Handwritten text lacks the uniform structure of printed fonts. Letters can be connected, slanted, or irregularly shaped, making it challenging for standard OCR algorithms to accurately identify individual characters.
What is the ideal DPI for scanning text documents for OCR?
A resolution of 300 DPI (Dots Per Inch) is generally recommended for standard text documents. If the text is very small or poorly printed, scanning at 400 or 600 DPI may yield better OCR results.
Do I need an internet connection to use OCR in PDF converters?
It depends on the software. Some online tools rely on cloud-based OCR engines and require an internet connection, while desktop software like WPS Office provides built-in OCR capabilities that can process documents locally.
Can I fix OCR errors without re-scanning the document?
Yes. Once the scanned PDF is converted to a Word document, you can manually proofread and edit the text to correct any recognition errors using your word processor.


