

How to Improve OCR Results on Watermarked PDF Documents
Question details
The user needs to improve text recognition (OCR) accuracy on scanned PDF documents that contain text-obscuring watermarks.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
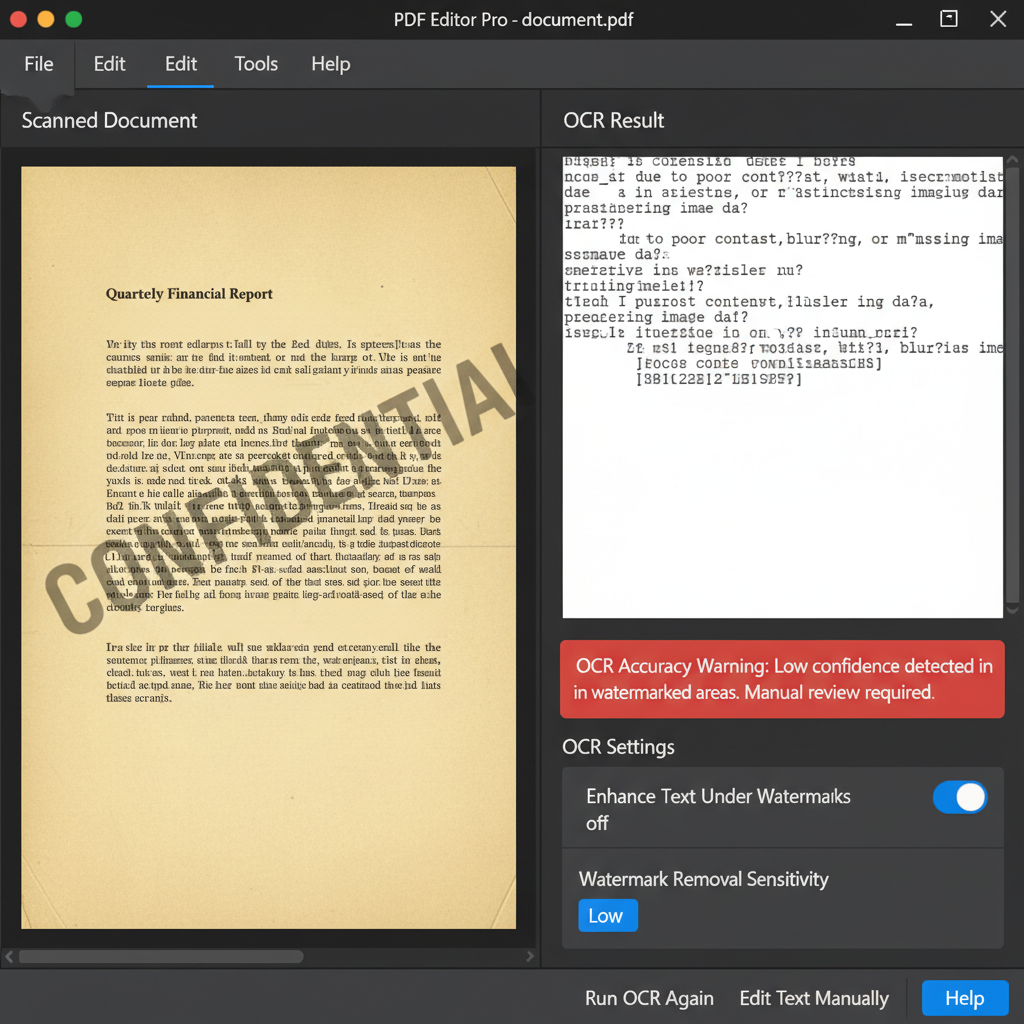
- Running OCR to extract or recognize text on a scanned PDF document that has a watermark.
- Observed behavior
- The OCR tool fails to accurately recognize text located beneath or obscured by the watermark due to poor contrast, blurring, or missing image data.
Ensure you have the legal right or permission to remove or alter the watermark on the document. Source the highest resolution original scan available, as OCR heavily depends on the clarity and contrast of the source image.
Enhance Scan Quality and Remove Watermarks Before OCR
Removing the watermark and using a high-quality scan restores the contrast needed for the OCR engine to accurately identify text.
OCR (Optical Character Recognition) accuracy relies entirely on the visual quality of the page. A watermark alters the pixels and reduces contrast, making it difficult for the software to distinguish characters from the background.
Source a high-resolution version of the document (preferably 300 DPI or higher) with strong black-and-white contrast to provide the best foundation for text recognition.
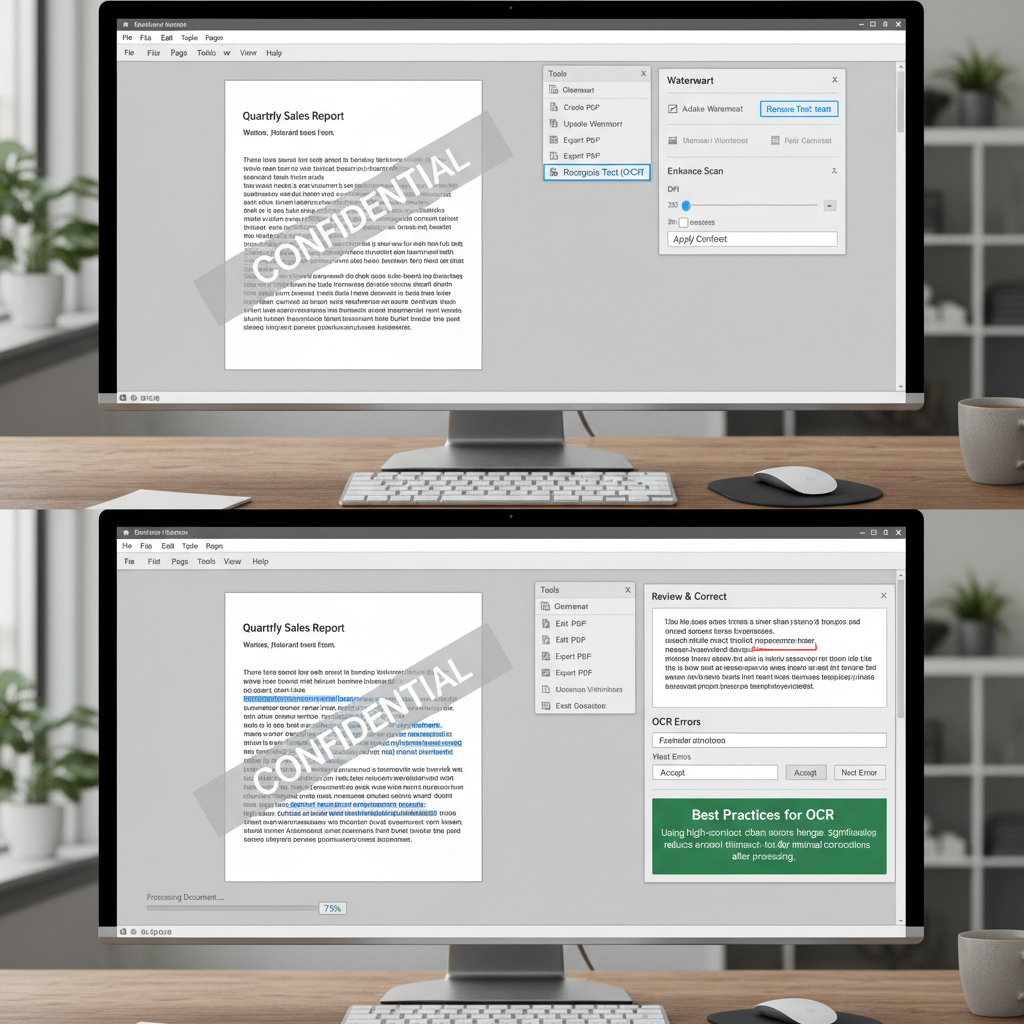
Open the document in your PDF editor. Navigate to the 'Edit' or 'Page' tab, select the 'Watermark' tool, and choose the option to 'Remove Watermark'.
Once the watermark is removed and contrast is improved, navigate to the 'Tools' menu and select 'OCR' or 'Recognize Text' to process the document again.
Carefully check the text where the watermark was previously located. Because some image data may have been permanently obscured, manually correct any lingering OCR errors.
Effortlessly Extract Text from PDFs with WPS Office
WPS Office provides a powerful, built-in OCR feature for PDFs that accurately recognizes text even in complex scanned documents. You can easily remove watermarks, enhance page clarity, and extract editable text in seconds.
- 1. Open your PDF: Launch WPS Office and open your scanned PDF document.
- 2. Remove Watermarks: Go to the 'Insert' or 'Edit' tab and click on 'Watermark' to delete any existing watermarks from the pages.
- 3. Initiate OCR: Switch to the 'Tools' tab and click on the 'OCR' button.
- 4. Extract or Convert: Choose 'Extract text' to pull the raw text, or select 'Convert to Word' to generate a fully editable document while preserving the layout.

Frequently Asked Questions
Why does OCR fail on text covered by a watermark?
OCR relies on a clear, distinct contrast between the text and the background. Watermarks reduce this contrast and alter the visual data of the characters, causing the optical recognition engine to misinterpret or completely miss the letters beneath.
Can I use OCR on a low-resolution scanned PDF?
While possible, low-resolution scans usually result in poor OCR accuracy with many missing or incorrect words. It is highly recommended to scan documents at 300 DPI or higher for reliable text recognition.
How can I manually correct OCR errors after processing?
Most advanced PDF editors, including WPS PDF, allow you to either edit the recognized text directly within the PDF or export the OCR results to a Word document where you can easily make manual corrections using a standard word processor.


