

How to Prevent Quality Loss When Using OCR on a PDF
Question details
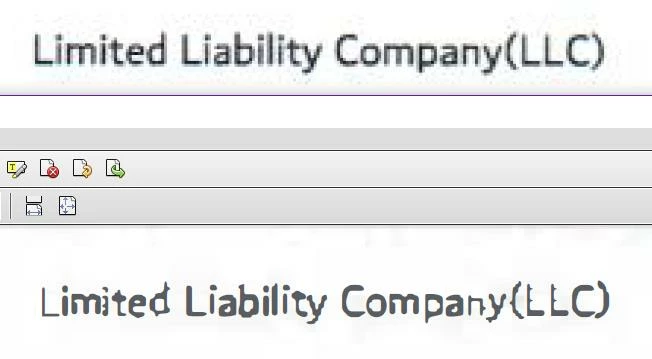
The user wants to perform OCR on a scanned PDF without degrading the visual quality or causing text to appear jagged.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Converting a scanned document into a searchable PDF using an Optical Character Recognition (OCR) tool.
- Observed behavior
- Applying OCR causes the original scanned text and images to appear jagged, pixelated, or compressed in visual quality.
Verify that your original scanned document has a high enough resolution (at least 300 DPI) before applying OCR, as low-resolution originals will inevitably yield poor results.
Configure OCR for Searchable Image Output
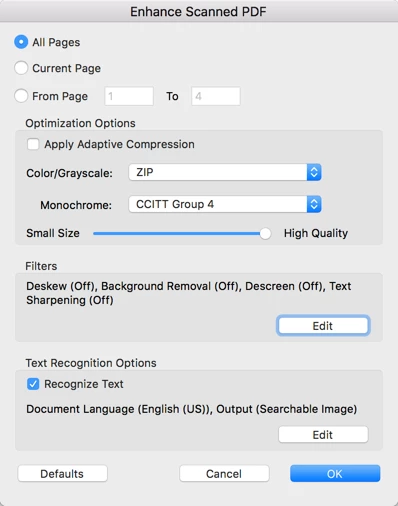
Set the OCR output to 'Searchable Image' and configure lossless compression to keep the original scan visible while placing the recognized text invisibly behind it.
Quality loss during OCR typically occurs when the software replaces the original scanned image with a synthesized font (Editable Text mode) or applies heavy compression to the file to save space.
Launch your PDF editor, open the scanned document, and navigate to the OCR or Text Recognition tool.
In the OCR output or export settings, choose 'Searchable Image' (sometimes called 'Text Under Image') instead of 'Editable Text'. This preserves the exact appearance of your original scanned page.
Locate the image compression options within the OCR settings. Select 'High Quality' and use lossless compression formats like ZIP or CCITT G4, avoiding lossy formats such as JPEG.
If your primary goal is only to make the text searchable, disable features like 'Enhance Scanned PDF' or 'Deskew/Despeckle' workflows, which can unintentionally alter the image quality.
Use WPS Office for High-Quality PDF OCR
WPS Office provides advanced OCR capabilities that accurately recognize text from scanned PDFs without degrading the original document's image quality. You can seamlessly extract text or create searchable PDFs with highly customizable settings.
- 1. Open your scanned document: Launch WPS Office and open your scanned PDF document in the WPS PDF editor.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button to launch the text recognition panel.
- 3. Choose extraction settings: Select the appropriate OCR mode depending on whether you want to extract text, convert it to a Word document, or maintain a searchable PDF.
- 4. Process and save: Click 'Start OCR' to let WPS Office process the document. Once completed, save the newly generated high-quality file.
Frequently Asked Questions
Why does my PDF look blurry after using OCR?
Blurriness usually happens if the OCR tool is set to output 'Editable Text' or if it applies strong, lossy compression (like JPEG) to the background images to reduce file size. Switching to a 'Searchable Image' output and selecting high-quality compression prevents this.
What is the best resolution for scanning documents for OCR?
For optimal OCR accuracy and visual clarity, you should scan your documents at 300 DPI (Dots Per Inch). Resolutions lower than this may lead to text recognition errors and pixelated outputs.
Can I make a PDF searchable without changing how it looks at all?
Yes. By choosing the 'Searchable Image' or 'Text Under Image' option in your OCR software, it will create an invisible layer of text beneath the completely unaltered original scanned image.


