

Fix Adobe Acrobat Closing During OCR on Large Scanned PDFs

Question details
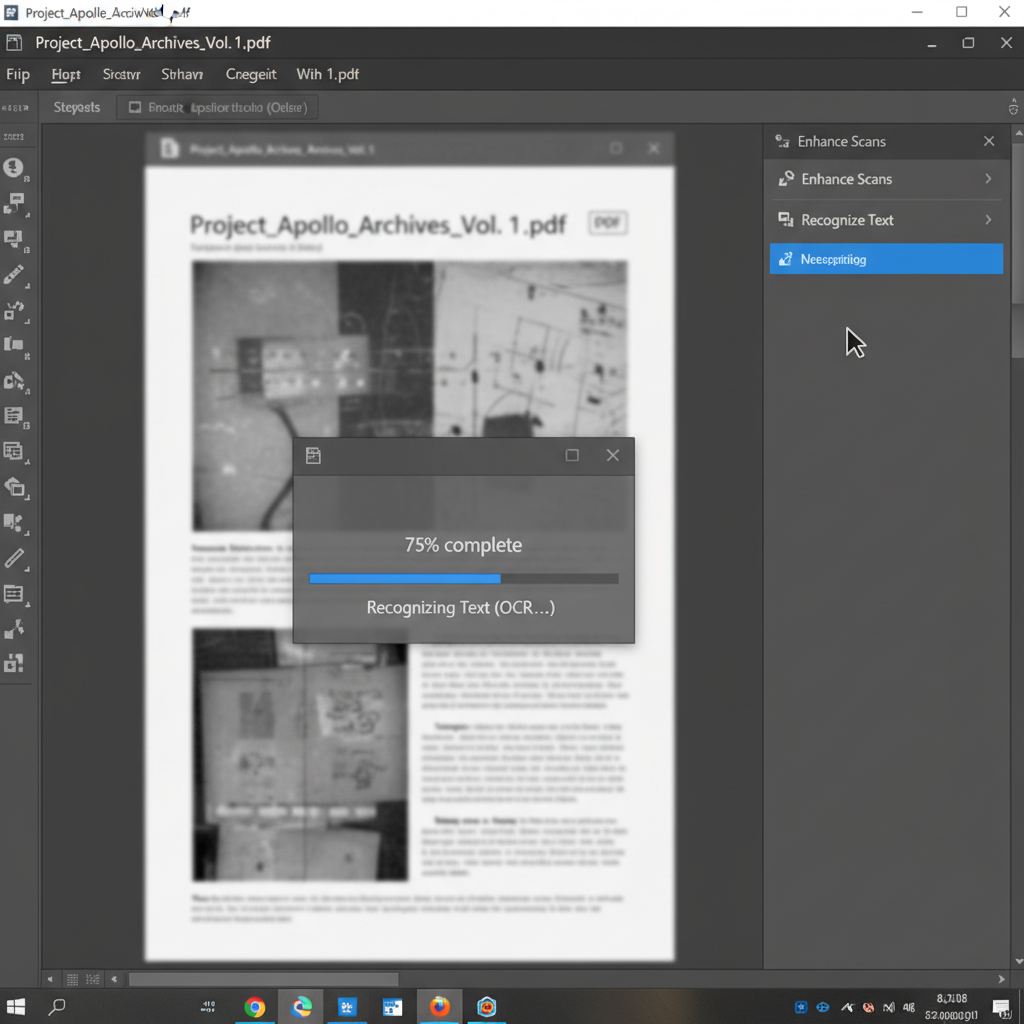
Adobe Acrobat DC unexpectedly closes without any error warning when performing Optical Character Recognition (OCR) on large scanned PDF documents, typically crashing around 75 percent completion.
- Product
- Adobe Acrobat DC
- Device & OS
- Windows
- Scenario
- Running the OCR tool to extract and recognize text on a large, multi-page scanned PDF file.
- Observed behavior
- The application suddenly shuts down and closes without displaying a warning message, failing to complete the text recognition process.
Verify that your local hard drive has sufficient free storage space to handle large temporary files, and ensure you have saved a backup copy of your original scanned document before troubleshooting.
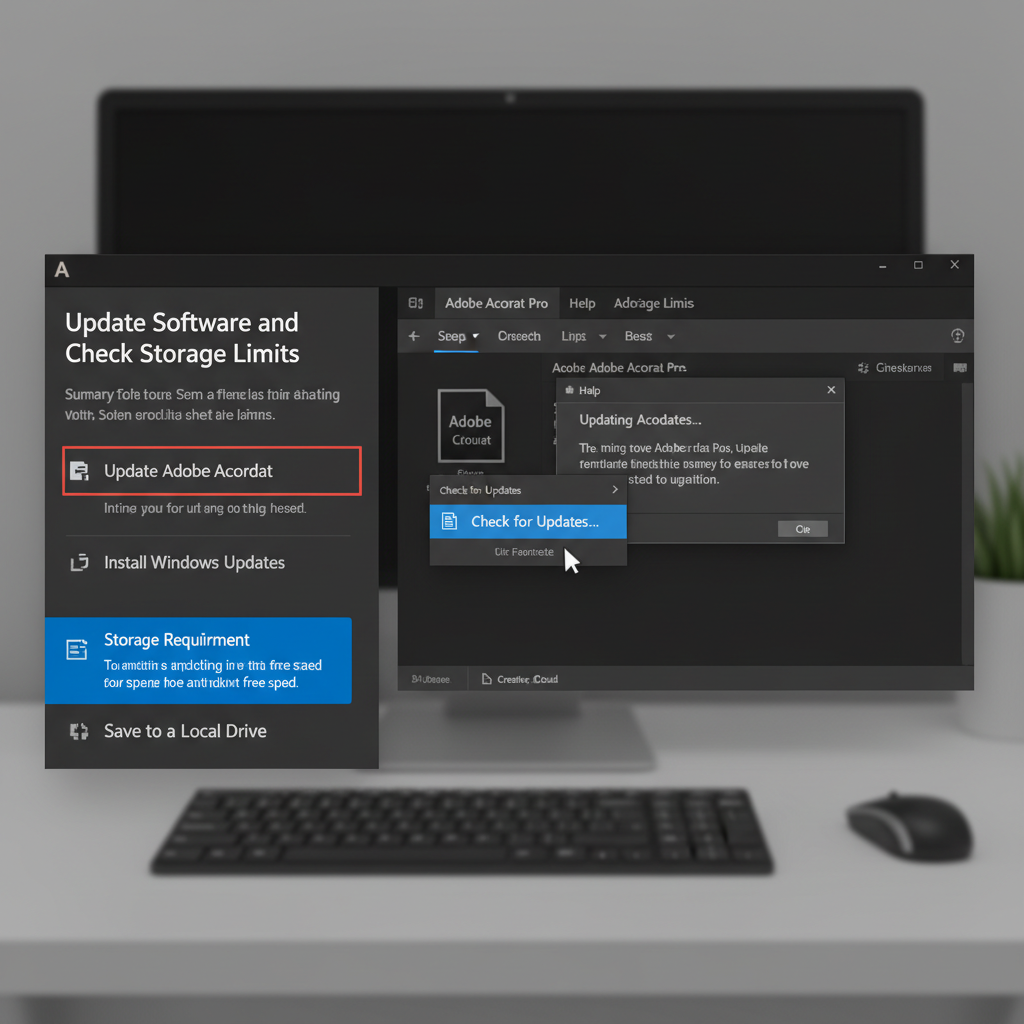
Update Software and Check Storage Limits
Keeping Adobe Acrobat and Windows updated ensures optimal performance and patches known memory allocation bugs that cause OCR crashes.
Processing large scanned PDFs of hundreds of pages requires significant system resources. Outdated software may struggle with memory limits, causing unexpected crashes. Updating your system and working from a local drive can stabilize the OCR process.
Open Adobe Acrobat, click on 'Help' in the top menu bar, and select 'Check for Updates'. Install the latest release.
Open your Windows Settings, go to 'Update & Security', and click 'Check for updates' to ensure your operating system is current.
If you are processing the file from a network or cloud drive, move the PDF to your local C: drive (ensuring it has plenty of free space) before running OCR.
Process the PDF in Smaller Page Ranges
Running OCR on smaller sections helps bypass memory limits and isolates specific damaged pages that might be triggering the crash.
Repair Acrobat Installation and Disable Plug-ins
A corrupted installation or conflicting third-party plug-ins can cause the application to shut down unexpectedly during intensive tasks.
Extract Text from Large PDFs with WPS Office
If your current PDF reader struggles with heavy OCR workloads, WPS Office offers a highly stable PDF editor. Its built-in OCR technology efficiently handles large scanned documents, allowing you to quickly convert them into editable formats without crashing.
- 1. Open PDF: Launch WPS Office and open your large scanned PDF document.
- 2. Access OCR: Navigate to the 'Tools' tab and click on the 'OCR' button to initiate the text recognition feature.
- 3. Extract Text: Select your desired page range and output format, such as Word Document or plain text, then click 'Extract'.

Frequently Asked Questions
Why does Adobe Acrobat crash when running OCR on large files?
Crashes typically occur due to insufficient system RAM, a corrupted page within the scanned document, or software bugs struggling with the memory allocation required for processing hundreds of pages simultaneously.
How can I find out which page is causing the OCR process to fail?
You can process the document in smaller batches, such as 50 to 100 pages at a time. If a specific batch causes the application to close, continuously halve the page range of that batch until you pinpoint the exact damaged page.
Can I run OCR on files saved directly on a network drive?
While possible, running resource-intensive tasks like OCR on files located on network or cloud drives can cause connection timeouts and application crashes. It is highly recommended to copy the large PDF to your local hard drive before processing.


