

Apply Acrobat OCR to Selected Pages in Multiple PDFs

Question details
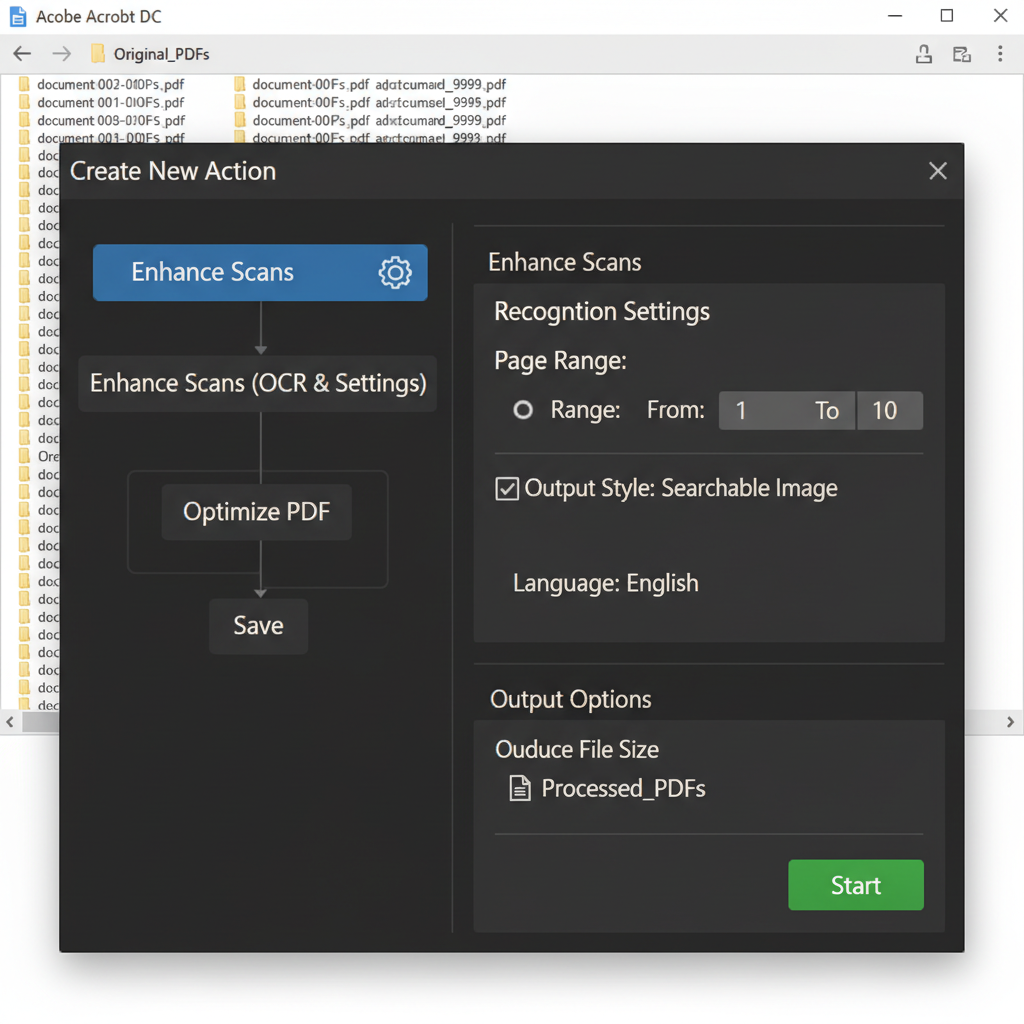
The user needs to automate the enhancement, OCR, and optimization of exactly the first 10 pages for a folder containing approximately 1,000 PDF documents.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Batch processing a massive folder of PDF files where processing power and time need to be saved by restricting OCR to a specific page range.
- Observed behavior
- The user is attempting to use a custom Acrobat JavaScript workflow to handle this, as standard UI batch processing tools typically apply OCR to entire documents rather than designated page limits.
Before attempting any batch OCR or document enhancement processes, make sure to copy your 1,000+ source PDFs into a separate, secure backup folder, as OCR optimization permanently alters the original files.
Use Acrobat Action Wizard for Batch Processing
Since Acrobat JavaScript does not natively support batch-running the Enhance Scanned Pages workflow for specific page ranges, you can use the Action Wizard to automate the OCR process, though you may need to split the files first.
Acrobat JavaScript lacks a reliable command to isolate page ranges during a batch OCR process. The most robust built-in alternative is the Action Wizard, which can batch-process entire folders.
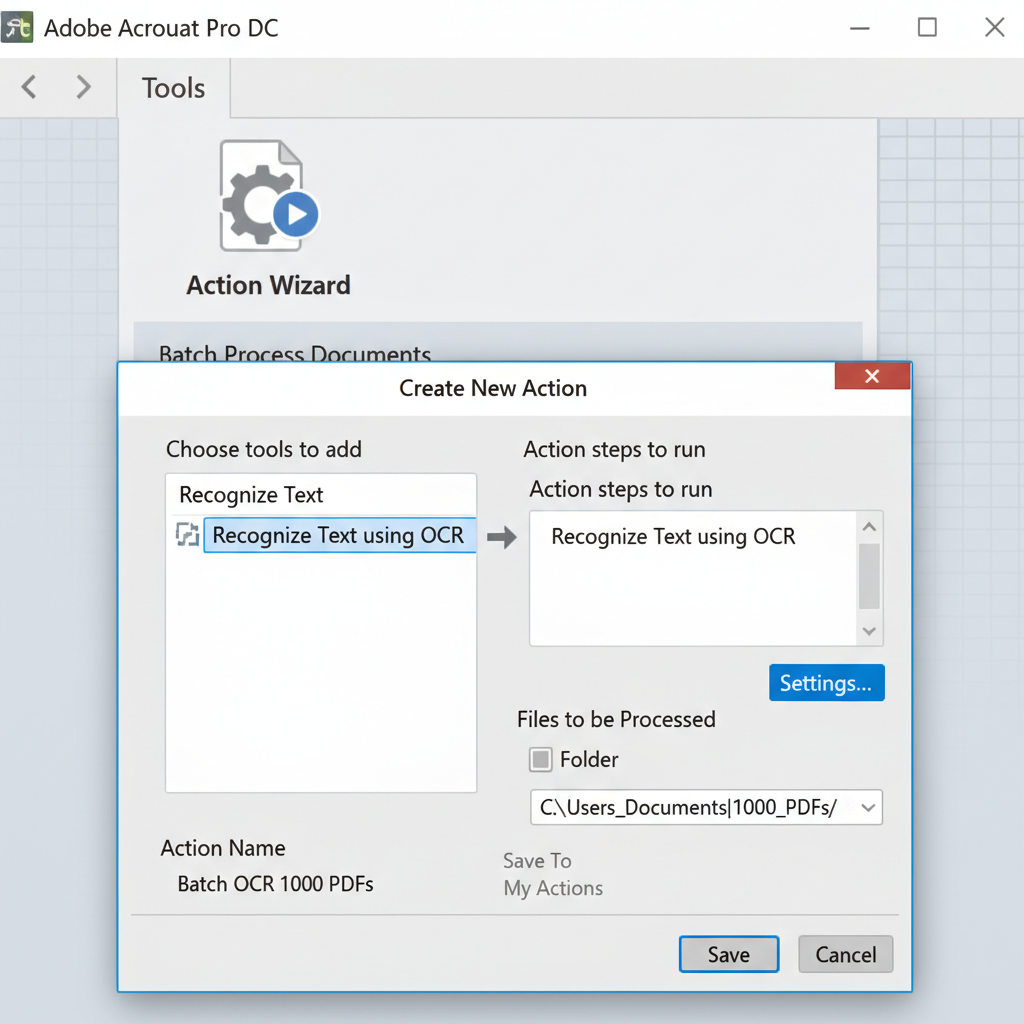
Launch Adobe Acrobat, navigate to the 'Tools' tab, and select 'Action Wizard'.
Click 'New Action' in the toolbar. In the 'Choose tools to add' pane, expand the 'Recognize Text' category and add it to the right-hand action steps.
Under 'Files to be Processed', click 'Add Folder' and select the directory containing your 1,000 PDFs.
Save the action with a descriptive name, then click on it in the Actions List to run it across the entire folder.
Pre-Split PDFs to Isolate the Target Pages
To enforce the 10-page limit during batch OCR, split the first 10 pages of every document into a new folder before processing.
Utilize Adobe PDF Services API or Dedicated Automation
For highly specific, high-volume operations spanning thousands of files, external programmatic automation offers the flexibility that standard Acrobat JS lacks.
Extract and OCR PDF Pages Easily with WPS PDF
While scripting complex batch tasks in other software can be restrictive, WPS Office provides an intuitive interface for managing PDFs and applying highly accurate OCR. You can easily extract specific pages and convert scanned documents into editable text formats without writing any complex code.
- 1. Open your PDF: Launch WPS Office and open the PDF file you want to process.
- 2. Extract the required pages: Navigate to the 'Page' tab and select 'Extract Page' to isolate the specific pages you need (e.g., pages 1-10).
- 3. Apply OCR: Open the extracted document, go to the 'Tools' tab, and click on 'OCR'. Choose your desired output format.
- 4. Save your editable file: Click 'Start OCR' to convert the extracted pages into an editable document and save it to your local drive.

Frequently Asked Questions
Can I use Acrobat JavaScript to OCR only specific pages?
No, Acrobat JavaScript does not provide a reliable built-in command to batch-run the full 'Enhance Scanned Pages' or OCR workflow on specific page ranges across multiple files.
Does Acrobat Action Wizard allow setting page ranges for OCR?
By default, the Action Wizard's 'Recognize Text' tool processes the entire document. To apply OCR strictly to the first 10 pages, you must first split or extract those pages from the original PDF before running the action.
Is it safe to run batch OCR directly on my original PDF files?
No. OCR and page optimization processes permanently alter the source files. Always run batch operations on a copy of your documents to prevent accidental data loss or unwanted formatting changes.
What alternative tools can process complex batch OCR workflows?
For advanced scripting and page-specific batch OCR on hundreds of files, developers often utilize the Adobe PDF Services API, command-line Python libraries, or dedicated enterprise batch-OCR software.


