

Best Adobe OCR Tools for Automating PDF Text Recognition

Question details
The user is searching for a reliable Adobe tool, service, or API to automatically apply Optical Character Recognition (OCR) to multiple scanned PDF documents.
- Product
- Adobe Acrobat Pro / Adobe Document Services API
- Device & OS
- not provided
- Scenario
- Automating text recognition for large batches of scanned PDF files to eliminate manual processing.
- Observed behavior
- Seeking automated OCR capabilities beyond single-file manual processing to efficiently create searchable text from scanned documents.
Before setting up automated OCR, ensure your scanned PDFs are of sufficient resolution (ideally 300 DPI or higher) for accurate text recognition, and verify that you have an active Adobe Acrobat Pro subscription or access to Adobe API credentials.
Automate OCR using Adobe Acrobat Pro's Action Wizard
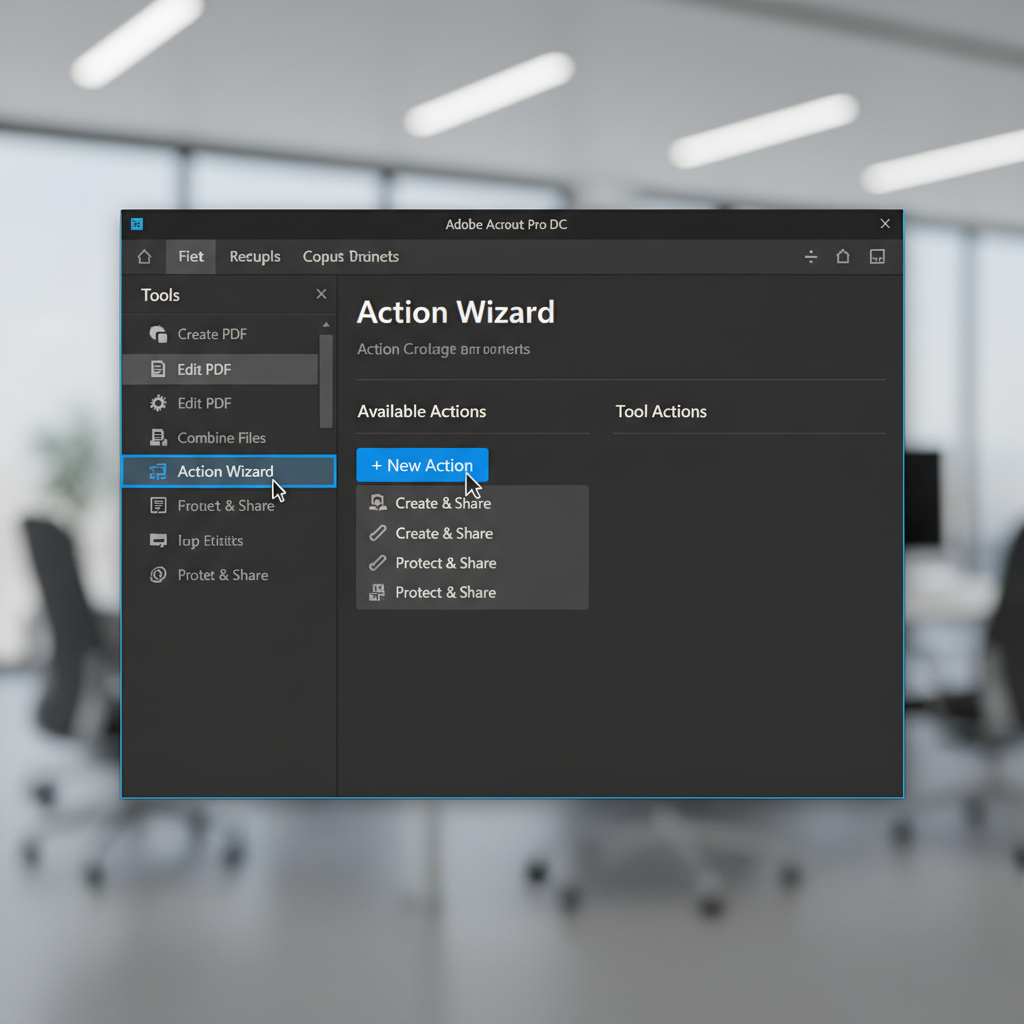
Use the built-in Action Wizard in Acrobat Pro to run OCR automatically across multiple files in a specified folder without writing any code.
Acrobat Pro includes a powerful batch processing tool called Action Wizard. It allows users to string together multiple commands, such as applying text recognition, and execute them on an entire directory of files at once.
Open Adobe Acrobat Pro. Go to the 'Tools' menu and select 'Action Wizard' from the list of available features.
Click on 'New Action' in the toolbar. In the 'Choose tools to add' pane on the left, expand 'Recognize Text', select 'In Multiple Files', and click the '+' icon to add it to your action steps.
Under 'Files to be Processed' on the right side, click 'Add Folder' and browse to the directory containing the scanned PDFs you want to process.
Click 'Save' and give your action a clear name, such as 'Batch OCR'. To automate the OCR process, simply click on this new action in the Action List and select 'Start'.
Implement Automated OCR via Adobe PDF Services API
For enterprise-level automation or integration into custom applications, use Adobe's dedicated PDF Extract API.
Automate PDF OCR with WPS Office
WPS Office offers a powerful, built-in OCR feature within its PDF editor, allowing you to quickly extract text from scanned documents and images. It serves as a highly cost-effective and lightweight alternative for standard document processing tasks, ensuring high accuracy and format retention.
- 1. Open WPS PDF: Launch WPS Office and open your scanned PDF document using the WPS PDF editing tool.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' or 'Picture to Text' icon.
- 3. Configure OCR Settings: Select the specific pages you want to process, choose the document's primary language, and decide whether to extract raw text or convert it into a searchable document.
- 4. Execute OCR: Click 'Extract Text' or 'Convert'. WPS will automatically process the document and provide editable text almost instantly.

Frequently Asked Questions
Is OCR included for free in Adobe Acrobat Reader?
No, Adobe Acrobat Reader is a free viewer and does not include OCR capabilities. You need a paid subscription to Adobe Acrobat Pro or Standard to use built-in text recognition.
Can I automate OCR processing without writing code?
Yes, you can automate OCR without coding by using the Action Wizard feature within Adobe Acrobat Pro. It allows you to set up a batch process to recognize text across multiple files in a designated folder.
What languages does Adobe's OCR engine support?
Adobe's OCR engine supports dozens of languages, including English, Spanish, French, German, Japanese, and Chinese. Selecting the correct language in the OCR settings significantly improves recognition accuracy.
Why is the OCR text recognition failing on my scanned PDF?
OCR may fail or produce errors if the source document has low resolution, poor lighting, overlapping text, or heavy handwriting. Ensuring the original scan is clear, straight, and at least 300 DPI will drastically improve results.


