

Can You Export the OCR Text Layer as a Separate PDF?

Question details
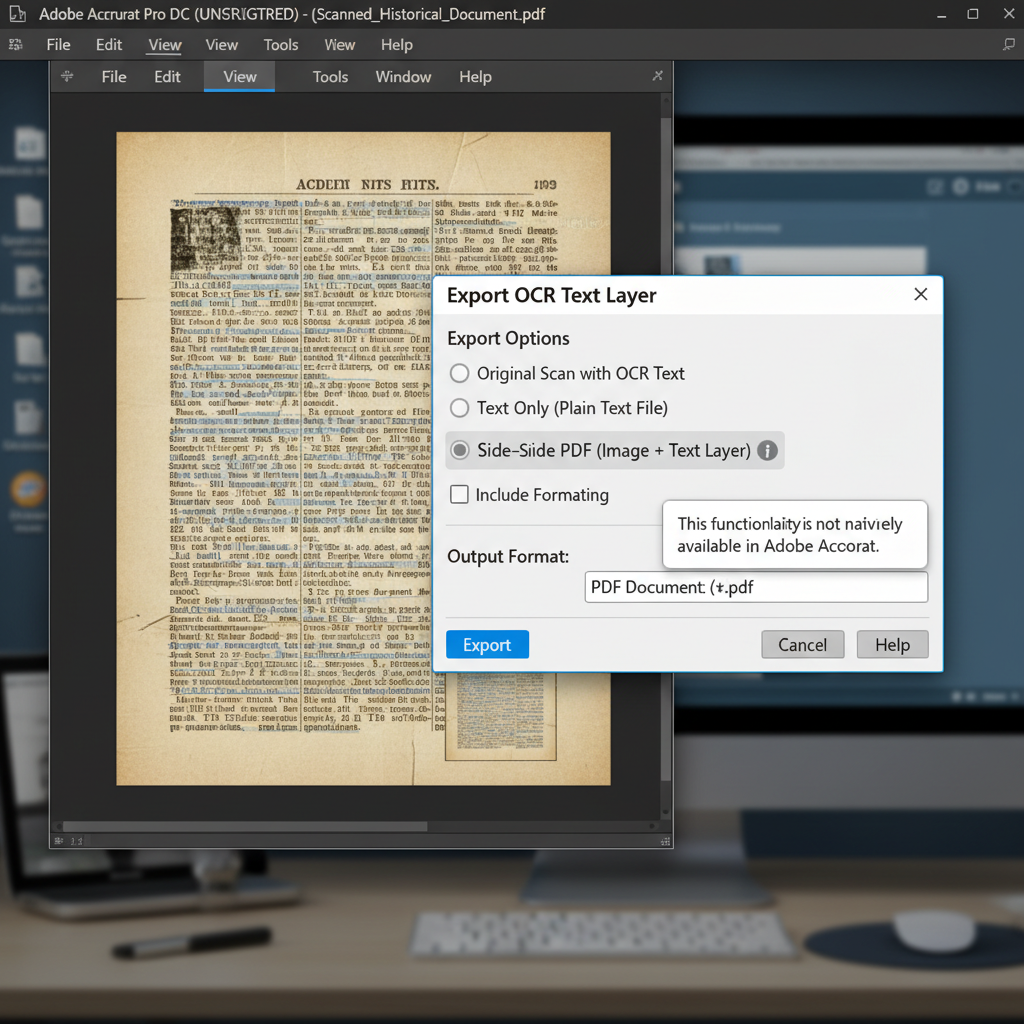
The user wants to know if it is possible to separate and export the hidden OCR text layer from a scanned document as an independent PDF.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to isolate the invisible, selectable OCR text from the original scanned image background within a PDF document.
- Observed behavior
- Acrobat stores OCR text as an invisible layer mapped over the scanned image and does not offer a native, direct way to export just the OCR layer as a side-by-side PDF document.
Ensure your PDF document has already undergone Optical Character Recognition (OCR) processing, which is required to generate the hidden text layer over the image.
Extract Text via Acrobat Export Tools
Since Acrobat cannot export the OCR layer as a standalone PDF, the standard workaround is to export the document content to a text-based format.
Adobe Acrobat does not normally export the OCR layer as an independent, side-by-side PDF layer. OCR text is designed to be an invisible text layer positioned perfectly over the scanned image to enable searching and highlighting.
To isolate the text from the image, you must use Acrobat's accessibility or export tools to copy the text to a completely new file.
Launch Adobe Acrobat and open the PDF file that has already been processed with OCR.
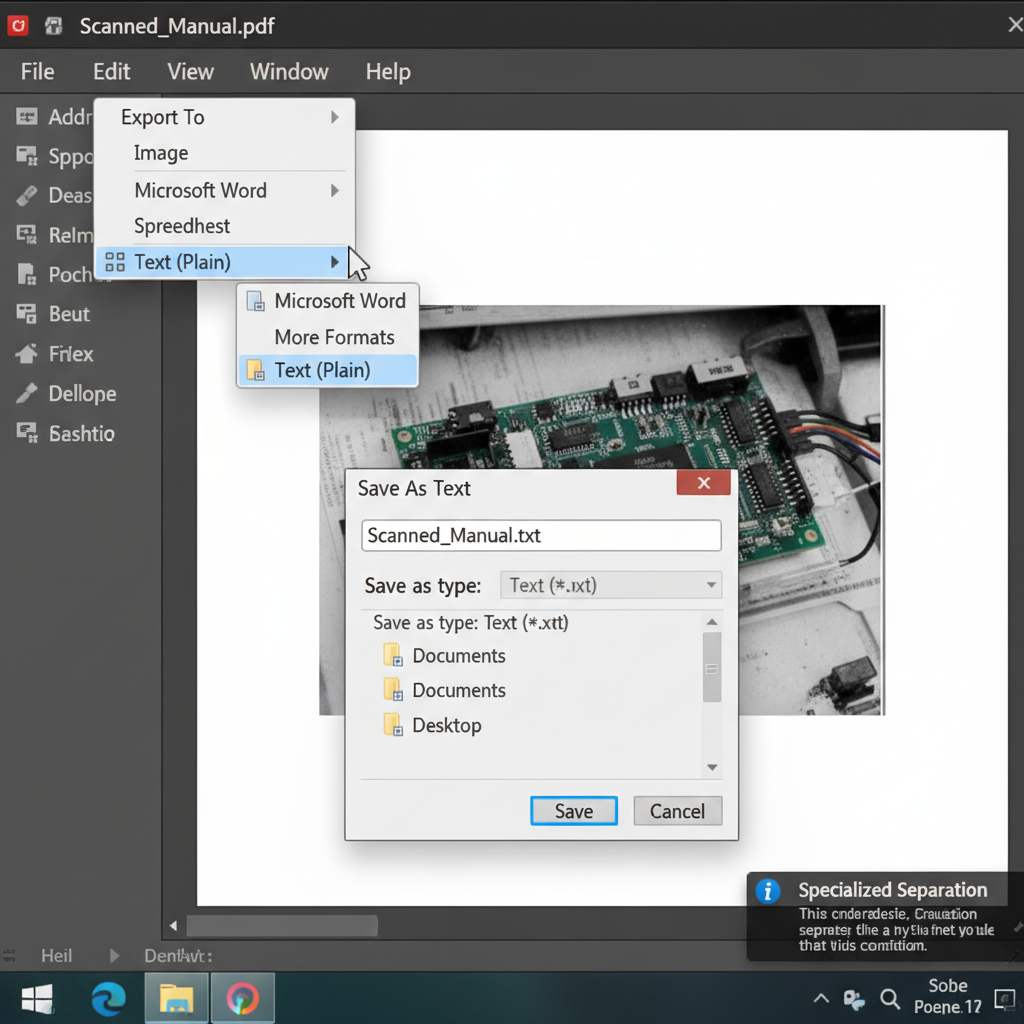
Click on 'File' in the top menu, hover over 'Export To', and select 'Text (Plain)' or 'Microsoft Word'.
Choose a destination folder and click 'Save'. The invisible OCR text layer is now saved as a separate text or Word file, stripped of the original image background.
Manually Copy the OCR Text
For specific paragraphs rather than the whole document, manually copying the text via accessibility tools is the fastest method.
Extract Text from Scanned PDFs with WPS Office
If you need to separate text from scanned images without wrestling with invisible PDF layers, WPS Office provides a powerful built-in OCR feature. You can easily extract text from scanned PDFs or convert them directly into editable Word documents.
- 1. Open PDF in WPS: Launch WPS Office and open your scanned PDF document in the WPS PDF tool.
- 2. Use the OCR Feature: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button to start text recognition.
- 3. Extract or Convert Document: Choose 'Extract Text' to pull the OCR layer into a plain text window, or select 'PDF to Word' to convert the entire document into an editable format without the scanned background.

Frequently Asked Questions
Why is the OCR text invisible in my PDF?
OCR text is intentionally stored as a hidden layer mapped perfectly over the original scanned image. This allows you to view the original document exactly as it was scanned, while still being able to search, select, and highlight the underlying recognized text.
Can I delete the image layer and keep only the OCR text in a PDF?
Most standard PDF editors do not allow you to simply delete the background image while leaving the hidden OCR text formatted properly on the page. The best practice is to export the OCR text to a Word document, edit it as needed, and save it back as a new PDF.
What is the easiest way to get text out of a scanned PDF?
The most reliable method is to use a PDF editor's conversion tools (like 'PDF to Word' or 'Export to Plain Text') after performing OCR. This extracts all the recognized text strings into a clean, editable file without requiring complex layer manipulations.


