

Can You Use Acrobat PDF Indexes for Online Website Search?

Question details
The user wants to know if Acrobat catalog index files (PDX and IDX) can provide standalone search functionality for documents hosted on a website.
- Product
- Adobe Acrobat / PDF
- Device & OS
- not provided
- Scenario
- Setting up a document search function for PDF files hosted on a public website or web server.
- Observed behavior
- Acrobat index files are not designed for web servers and cannot be used as a web-based search service.
Before configuring your website search, ensure your PDF files contain recognizable text rather than flat scanned images, and verify they are uploaded to a publicly accessible directory on your web server.
Use External Web Search Engines for PDF Indexing
Since PDX files do not work on web servers, the most efficient method is to allow modern external search engines like Google to index your online PDFs.
Major search engines have built-in capabilities to crawl, read, and index the text content of standard PDF files. By exposing your PDFs to web crawlers, users can use site-specific search queries to find your documents.
Ensure your PDF files are hosted on your live web server and are not blocked by password protection or a restrictive robots.txt file.
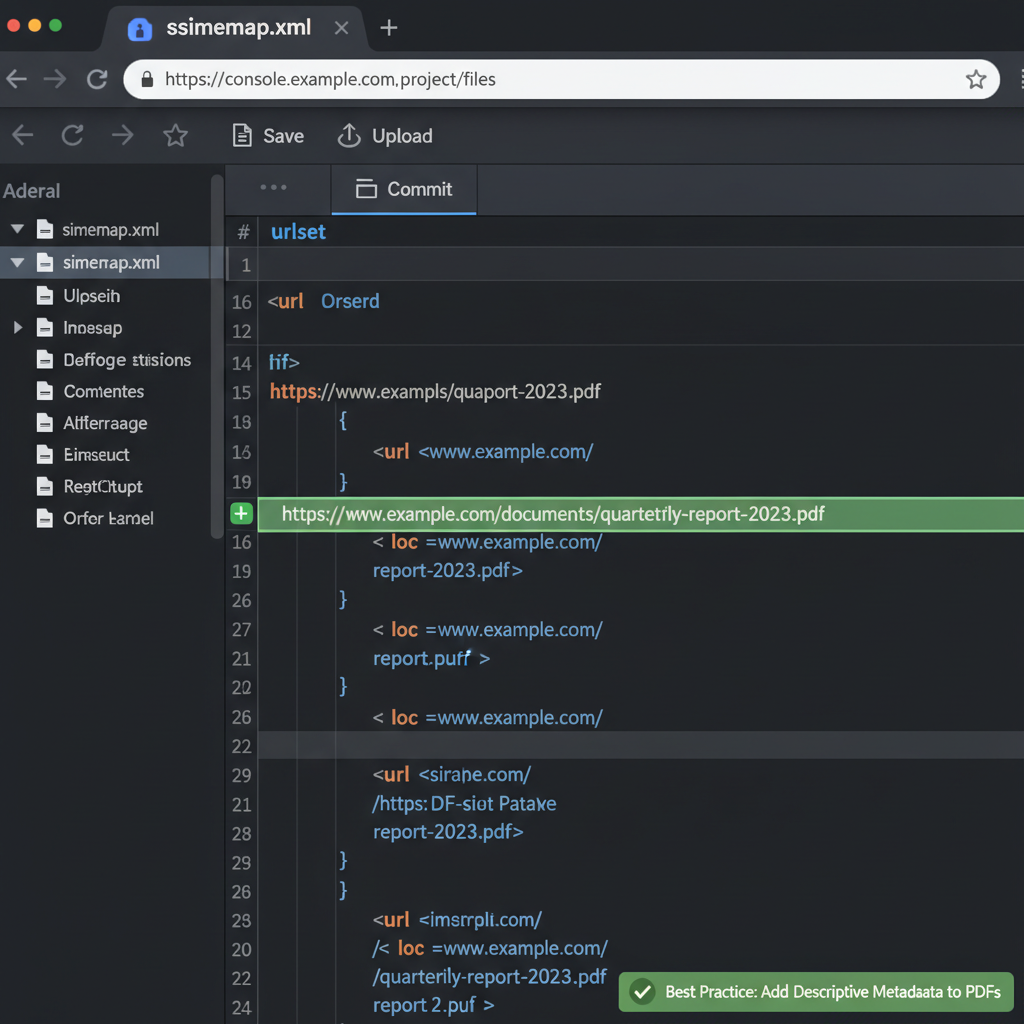
Add the direct URLs of your PDF documents to your website's sitemap to help search engine crawlers discover them faster.
Use tools like Google Search Console to submit your updated sitemap, prompting the search engine to crawl and index your PDF files.
Implement Server-Side Indexing Software
If you need an internal site search that does not rely on external search engines like Google, configure a server-side indexing platform.
Create Searchable PDFs with WPS Office
While Acrobat PDX files aren't suitable for website search, ensuring your PDFs contain machine-readable text is essential for web indexing. WPS Office provides powerful PDF tools, including OCR, to make sure external search engines and server tools can effortlessly read and index your documents.
- 1. Open your PDF: Launch WPS Office and open the PDF document you plan to upload to your website.
- 2. Apply OCR to scanned files: If your PDF is an image-based scan, navigate to the Tools menu and select 'OCR' to extract and convert the images into searchable text.
- 3. Optimize and save: Save the document as a standard PDF. You can also use the 'Compress PDF' feature to ensure the file is lightweight for optimal web performance.

Frequently Asked Questions
What are Acrobat PDX and IDX files used for?
PDX and IDX are Adobe Acrobat catalog index files designed to speed up complex searches across multiple PDF documents locally on a desktop or an internal network drive. They are not built to function over HTTP for website visitors.
Can Google index my PDF files automatically?
Yes, Google and most modern search engines natively crawl and index standard PDF files, provided the PDFs contain readable text and are linked publicly on your website without being blocked by robots.txt.
Why is my website's internal search not finding text inside PDFs?
Basic website search functions often only search HTML databases. To search inside PDFs natively, your website needs a specific plugin or a server-side indexing configuration (like Apache Solr or IIS Indexing) capable of extracting text from PDF formats.
How do I know if my PDF is searchable by web crawlers?
Try highlighting the text in your PDF using a standard PDF reader. If you can select individual words and copy them, web crawlers can typically read and index the text. If it highlights as one large image block, you need to apply OCR (Optical Character Recognition) before uploading.


