

Does Adobe Acrobat Support Turkish Text Recognition (OCR)?

Question details
The user wants to know if the Turkish language is supported for text recognition (OCR) when using Acrobat.com online services or the Adobe Acrobat application.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to extract or recognize Turkish text from scanned PDF documents for editing and searching.
- Observed behavior
- The user is looking for a definitive answer on whether their PDF tool supports accurate OCR processing for Turkish characters.
Ensure your scanned document is clear and high-resolution, as OCR accuracy heavily relies on the source image quality. If you are trying online services, verify your internet connection and file size before uploading.
Use the Adobe Acrobat Desktop Application
While Acrobat.com online services do not support Turkish text recognition, the desktop version of Adobe Acrobat fully supports it.
Adobe restricts certain advanced OCR language packs on its online platform to optimize web performance. To accurately process Turkish characters (like ş, ç, ğ, ı, ö, ü), you must use the installed desktop software.
Install the desktop version of Adobe Acrobat. If you do not have a paid license, you can sign up for a 30-day free trial on the official Adobe website.
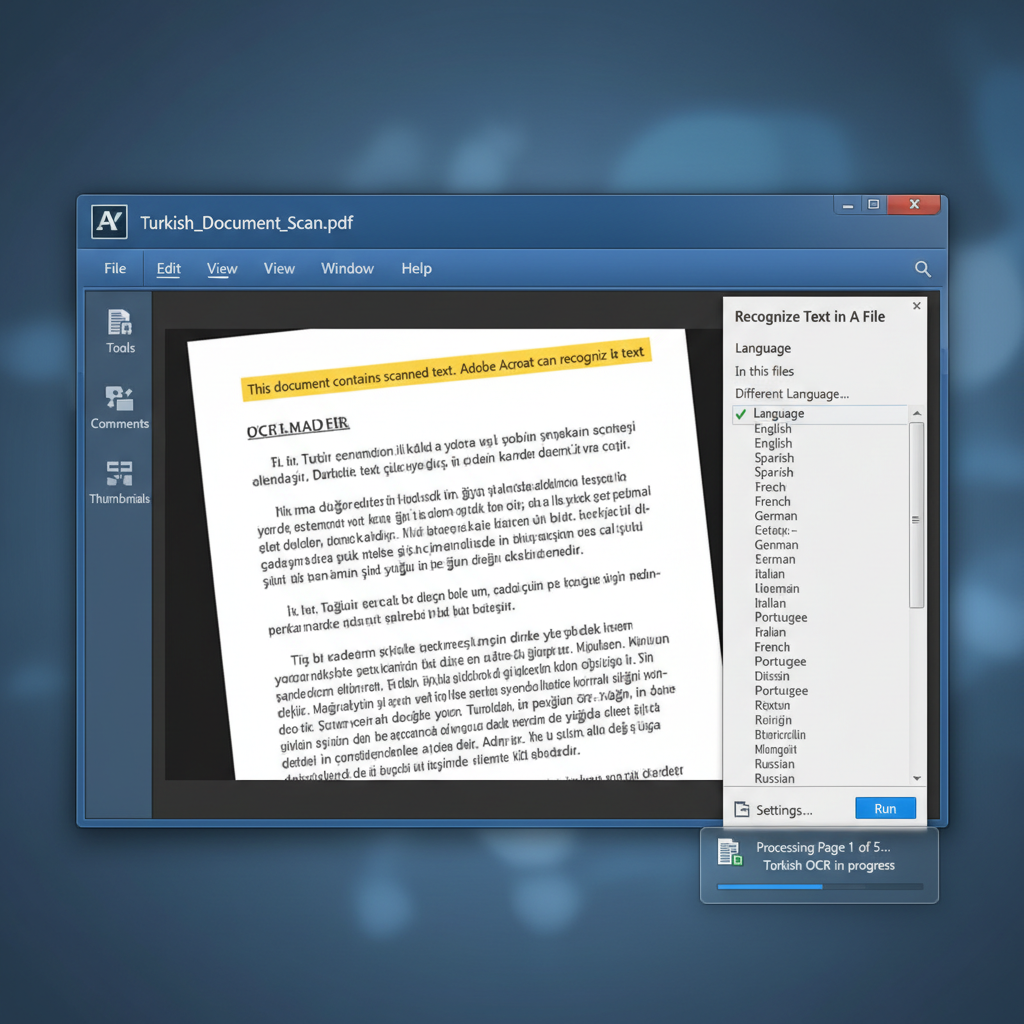
Launch the Adobe Acrobat desktop application and open the PDF document that contains the scanned Turkish text.
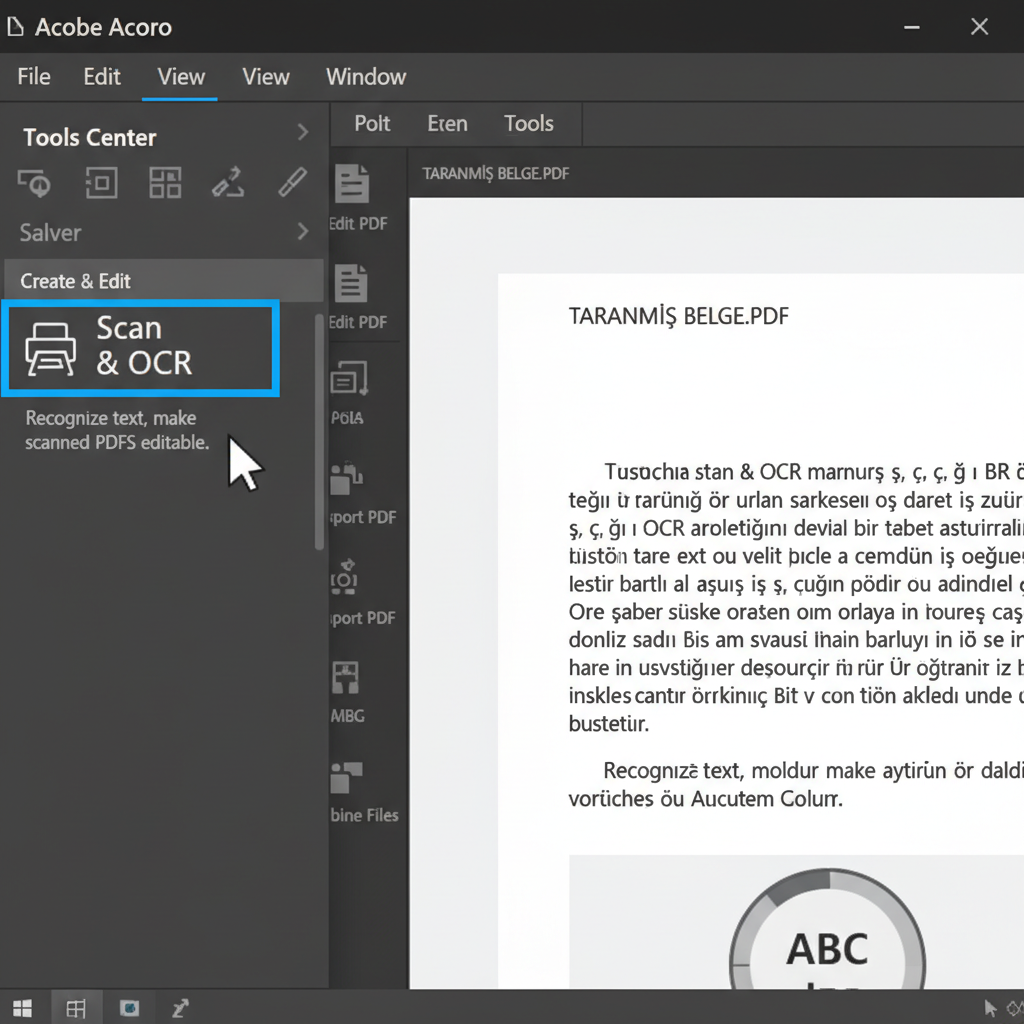
Navigate to the 'Tools' tab at the top of the interface and select the 'Scan & OCR' option.
Click on 'Recognize Text', choose 'In This File', then click on 'Settings'. Set the Document Language to 'Turkish' and click 'Recognize Text' to begin the extraction process.
Extract Text Accurately with WPS PDF OCR
WPS Office offers a powerful built-in PDF editor with an advanced OCR feature that can quickly and accurately extract text from scanned documents. It provides excellent format compatibility and is a highly efficient solution for processing multilingual text.
- 1. Open WPS Office: Launch WPS Office and open your scanned PDF document using the WPS PDF component.
- 2. Navigate to the OCR Tool: Click on the 'Tools' tab at the top menu bar and select the 'OCR' or 'Picture to Text' feature.
- 3. Select Extraction Settings: Choose whether you want to extract text from the current page or the entire document, and specify the language if prompted.
- 4. Save or Edit Text: Once the text is recognized, you can directly edit it within the viewer, copy it to your clipboard, or save it as a new Word document.

Frequently Asked Questions
Why does Acrobat.com online not support Turkish OCR?
Adobe's online PDF services have a more limited set of supported OCR languages compared to their full desktop application. This limitation helps optimize server processing speed and web performance.
Can I edit the text after performing OCR on a PDF?
Yes. Once the text recognition process is successfully completed, the scanned image is converted into searchable and editable text. You can then use your PDF editor's 'Edit PDF' tool to modify sentences, fonts, and formatting.
Are there other software options with built-in OCR?
Yes. Software suites like WPS Office come with integrated OCR capabilities in their PDF tools, allowing you to extract text from images and scanned documents without needing an Adobe subscription.


