

Fix Acrobat Action Wizard OCR Processing Only the First Page

Question details
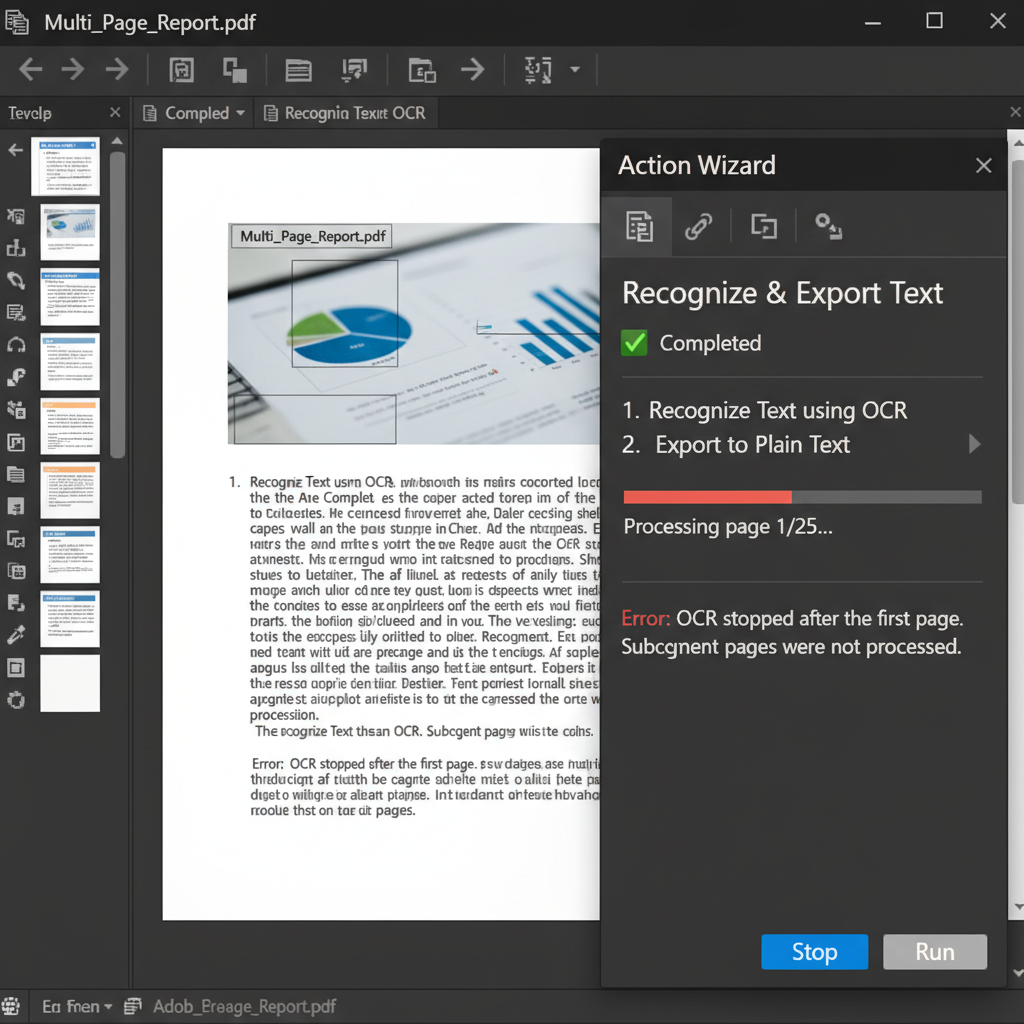
The user needs to resolve an issue where the Action Wizard text recognition (OCR) tool stops after processing the first page of a multi-page PDF document.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Running batch OCR and exporting a PDF as plain text using the Action Wizard tool.
- Observed behavior
- The software correctly recognizes and exports text for the first page but fails to process the subsequent pages of the PDF.
Ensure you have the latest version of your PDF software installed and create a backup copy of your original document before attempting file repairs or altering batch processing settings.
Verify Action Wizard Scope and Repair the Source PDF
Check the processing scope settings in the Action Wizard and test for file corruption to ensure the entire PDF is processed.
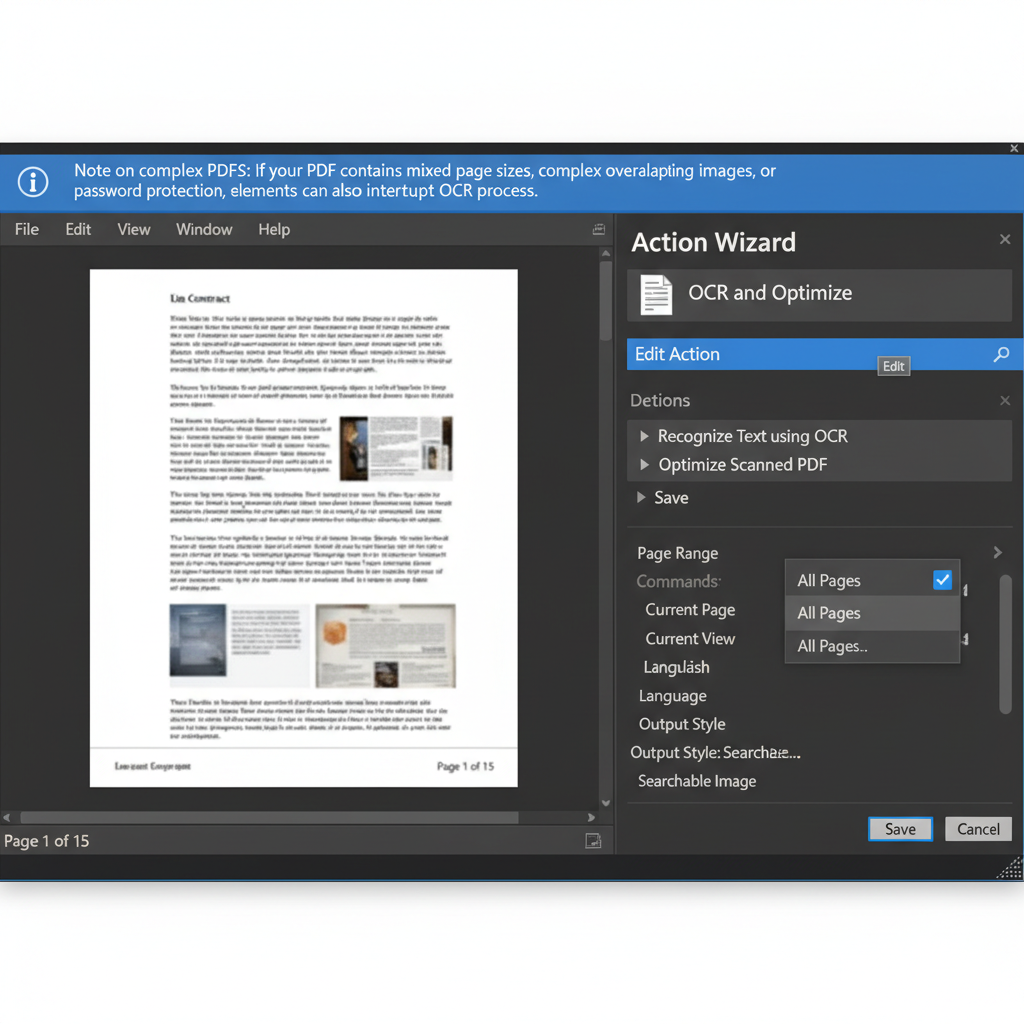
This issue typically occurs for two reasons: the Action Wizard is accidentally configured to process only the current page, or the source PDF file has structural damage preventing the OCR engine from reading past the first page.
Open the Action Wizard in Adobe Acrobat, edit your specific OCR action, and verify that the page scope is set to process the entire document rather than just the 'Current Page'.
Run the exact same OCR action on a different, known-good multi-page PDF document. If the action successfully processes all pages of the test document, your settings are correct, and the issue lies with the original file.
Open the problematic PDF and use the 'Save As' function to create a fresh copy. Alternatively, you can select 'Print' and choose 'Print to PDF' to flatten and recreate the file structure before running the OCR action again.
Easily Extract Text from Multi-Page PDFs with WPS Office
Avoid complicated wizard setups and file structure errors. WPS Office features a built-in, highly accurate OCR tool that effortlessly converts multi-page scanned PDFs into fully editable text or Word documents with just a few clicks.
- 1. Open your PDF: Launch WPS Office and open your scanned or image-based PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Select Output Format: Choose your desired output, such as 'Extract Text' or 'Convert to Word', depending on how you plan to use the content.
- 4. Process All Pages: Ensure the page range is set to 'All Pages' and click 'Confirm' to seamlessly recognize text across the entire document.

Frequently Asked Questions
Why does PDF OCR software sometimes skip pages?
OCR software may skip pages if the action settings are incorrectly restricted to the current page, if the PDF has corrupted structural tags, or if subsequent pages contain unrenderable complex graphics that crash the background process.
How can I fix a corrupted PDF file before running OCR?
You can often fix minor PDF corruption by opening the file and using 'Save As' to write a new file. You can also print the document using a virtual 'Print to PDF' driver, which generates a brand-new, clean PDF structure.
Can I extract text from a specific page range instead of the whole document?
Yes. In most modern PDF editors, including WPS Office and Acrobat, you can specify a custom page range (e.g., pages 2-5) within the OCR or export settings menu prior to initiating the text recognition process.


