

Fix Acrobat Cannot Find or Replace Text Due to Custom Font Encoding

Question details
Users are unable to search, replace, or reliably copy text within a PDF using Adobe Acrobat, resulting in garbled or unrecognizable characters.
- Product
- Adobe Acrobat / PDF
- Device & OS
- not provided
- Scenario
- Attempting to search, replace, edit, or extract text from a PDF document that was generated by third-party software.
- Observed behavior
- Acrobat fails to locate or replace the specified text, and any text copied from the document pastes as gibberish due to missing Unicode mapping.
Verify if the issue occurs with all PDF files or just a specific document to confirm the problem is isolated to that file's font encoding.
Regenerate the PDF with Standard Font Encoding
The most reliable method to fix custom encoding issues is to recreate the PDF from the original source file using standard fonts and proper Unicode mapping.
When a PDF is created using custom font encoding without a ToUnicode CMap, the PDF reader cannot translate the embedded character codes back into readable text. This breaks core functionality like text extraction, searching, and editing. Informing the software developer to include standard ToUnicode CMaps is the permanent fix, but as a user, you must regenerate the file.
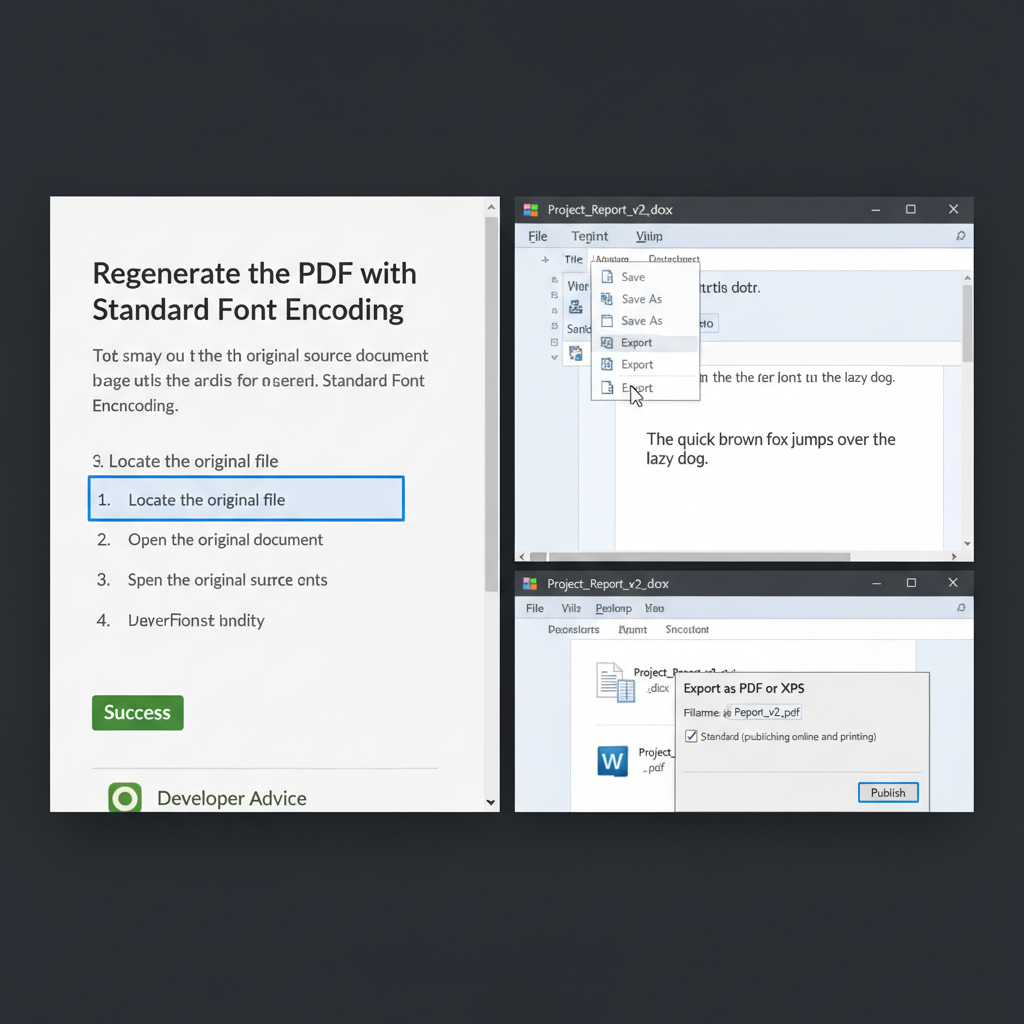
Open the original source document (such as a Word, Excel, or PowerPoint file) that was used to create the problematic PDF.
Ensure that the document uses standard, widely supported fonts like Arial, Times New Roman, or Calibri, rather than heavily customized or specialized web fonts.
Use the 'Save As' or 'Export' function in your word processor to generate a new PDF file. Alternatively, use a reliable virtual PDF printer.
Open the newly generated PDF in your reader, press Ctrl+F (or Cmd+F on Mac), and attempt to search for a word to confirm the text is now recognizable.
Print as Image and Re-run OCR
If you do not have access to the original source file, you can bypass the corrupted font layer by flattening the PDF into an image and using OCR to rebuild the text.
Create and Edit Searchable PDFs with WPS Office
Avoid font encoding issues and garbled text by generating your PDFs directly in WPS Office. It provides standard Unicode mapping and built-in OCR tools to ensure your documents are always searchable, accessible, and perfectly formatted.
- 1. Download and install: Download WPS Office from the official website and install it on your computer or mobile device.
- 2. Open your source document: Launch WPS Office and open your original Word, Excel, or PowerPoint document.
- 3. Export safely to PDF: Click on 'Menu', go to 'Export to PDF', and save your file. WPS Office automatically ensures proper font embedding and Unicode mapping.
- 4. Use OCR for existing files: If you only have the garbled PDF, open it in WPS PDF, go to the 'Tools' tab, and click 'OCR' to accurately extract and recreate the text layer.

Frequently Asked Questions
What is a ToUnicode CMap in a PDF?
A ToUnicode CMap (Character Map) is a hidden table embedded within a PDF document. It translates custom-encoded font characters into standard Unicode characters. Without it, software cannot search, copy, or understand the text properly.
Why does text copied from my PDF paste as garbled characters?
This occurs when the PDF creator uses a custom font subset without embedding the proper Unicode mapping. While the letters look correct visually on the screen, your computer does not know how to translate the custom visual codes back into readable digital text.
Can I fix the font encoding directly within the existing PDF?
Generally, no. Missing ToUnicode CMap information cannot be easily injected into an already generated PDF. The best approach is to either regenerate the PDF from the original source file or use OCR (Optical Character Recognition) technology to read the shapes of the letters and create a new, clean text layer.


