

Fix Acrobat Cannot Find or Search Selectable Text in PDF

Question details
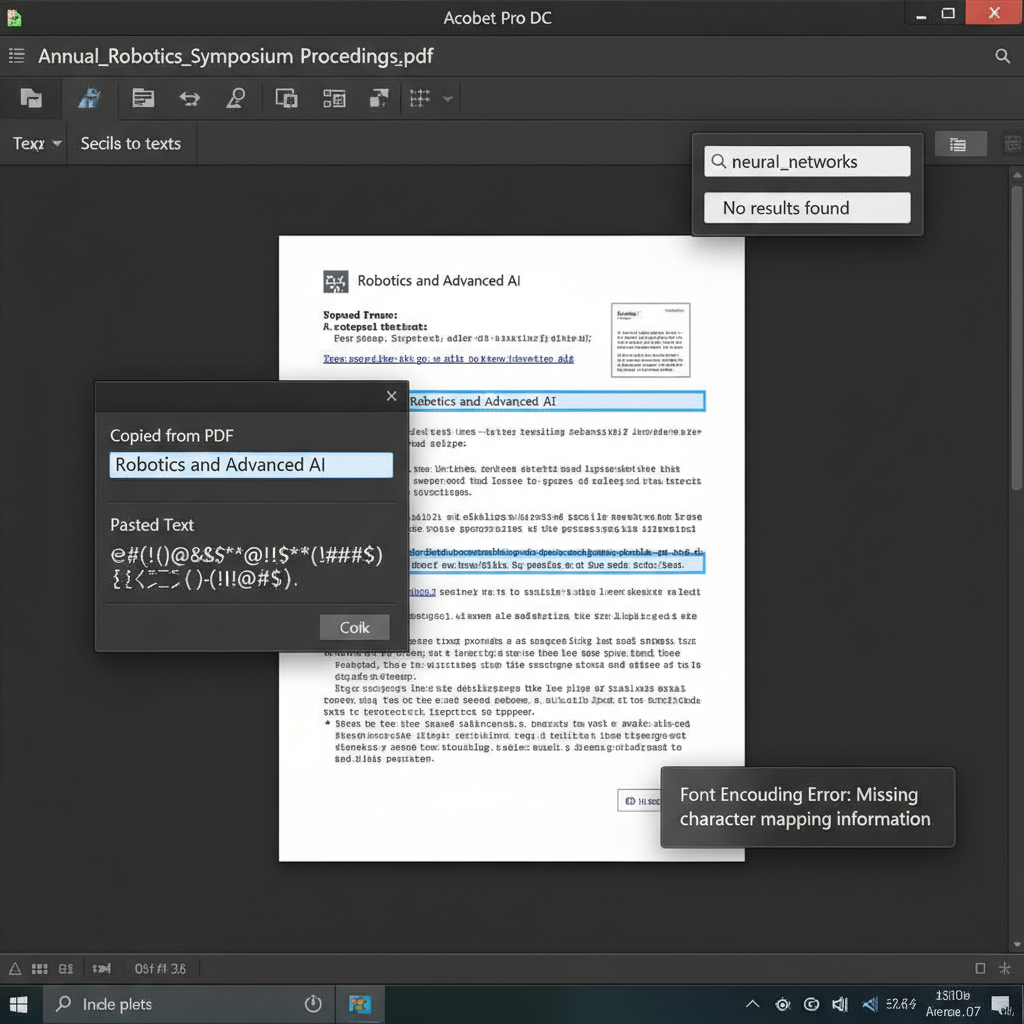
The user is unable to search, copy, or paste text in a PDF document using Adobe Acrobat, even though the text can be highlighted and selected.
- Product
- Adobe Acrobat / PDF
- Device & OS
- not provided
- Scenario
- Searching for specific keywords or attempting to copy text from a PDF document for use elsewhere.
- Observed behavior
- Acrobat allows text selection and may process OCR, but fails to correctly find, search, copy, or paste the text, often resulting in gibberish due to missing font encoding information.
Verify if the search issue occurs with all PDF documents or just a specific file. If it only happens with one document, the issue is likely corrupt font encoding within that specific file rather than an application error.
Recreate the PDF from the Original Source Document
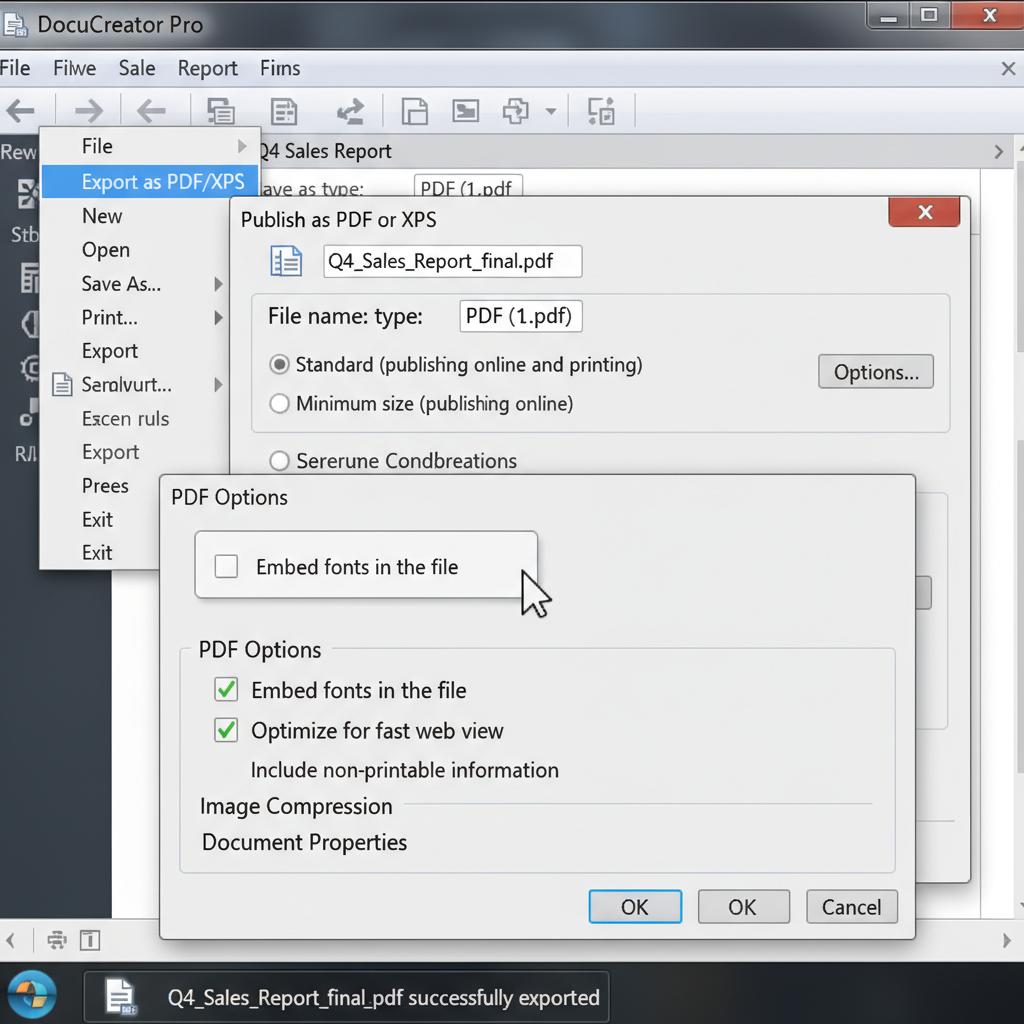
The most reliable fix is to re-export the PDF from its original creation software with standard, embedded fonts to repair corrupt encoding.
When a PDF is generated with non-standard fonts or incorrect export settings, the visual text layer may appear normal, but the underlying character map is broken. Re-exporting the file resolves this mapping issue.
Launch the application where the document was originally created (such as Microsoft Word, Excel, or Adobe InDesign).
Navigate to the 'File' menu and select 'Export', 'Save As', or 'Print to PDF'.
Before saving, open the PDF options or preferences and ensure that the setting to 'Embed all fonts' is checked.
Export the new PDF file, open it in your PDF viewer, and test the search (Ctrl+F) and copy-paste functions.
Print, Rescan, and Run OCR
Use this workaround to generate a fresh text layer if you no longer have access to the original source file.
Easily Search and Extract Text with WPS Office
Bypass complex font encoding errors and seamlessly search, edit, or extract text from problematic PDFs using the highly accurate built-in OCR tools in WPS Office.
- 1. Open the PDF in WPS: Launch WPS Office and open your problematic PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on 'OCR'.
- 3. Extract or Convert: Choose to extract the text directly or convert the document into a fully searchable Word document.
- 4. Search your text: Press Ctrl+F to open the search bar and easily locate your desired text.
Frequently Asked Questions
Why can I select text in my PDF but it copies as gibberish?
This happens when the PDF uses custom or embedded fonts without proper character encoding. The text is visually rendered correctly on the screen, but the underlying system maps those visual characters to incorrect or blank codes, resulting in gibberish when copied or searched.
Does flattening a PDF fix text search issues?
No. Standard flattening merges annotations and interactive elements into the background layer, but it does not correct the underlying text layer's broken font encoding. You must convert the document to an image and run OCR to generate a new text layer.
How do I force OCR on a PDF that already contains selectable text?
Most PDF editors, including Acrobat, will skip OCR if they detect a renderable text layer. To bypass this, print the document as an image or to physical paper, then rescan it. This removes the broken text layer entirely, allowing the OCR engine to analyze the visual characters from scratch.


